Yes—if they can be converted into bounded, testable instructions without losing their human accountability. That is the premise behind Collibra’s September 23 announcement: Agent Contracts are intended to make enterprise rules machine-readable, while Guardian Agents are intended to supervise whether AI agents stay inside those rules at runtime. The important qualification is timing. Collibra says Maestro Studio and Maestro Assistant are in public preview now, Live Map is with a small group of design partners, and Agent Contracts plus Guardian Agents are planned for October. These are not equivalent stages of product availability. Collibra’s announcement and Collibra’s Agent Contracts product post are the primary record; independent coverage reaches the same basic staging distinction.
For senior leaders, the announcement is less a reason to declare AI governance solved than a useful test of the next operating model. A policy PDF tells people what should happen. An executable policy system attempts to tell an agent what it may access, which tools it may use, what it may do, when it must escalate, and what evidence it must leave behind. That could make governance more repeatable across a growing agent fleet. It could also create a new failure mode if teams mistake a well-formatted contract for proof that an agent is safe, compliant, or correctly integrated.
What Collibra announced—and what is actually available
Collibra announced three connected capability areas: Maestro, Live Map, and Guardian Agents with Agent Contracts. The shared commercial message is reducing what Collibra calls the “hallucination tax”: staff time spent rechecking agent context and reviewing or correcting output. That framing and the performance benefits are Collibra’s claims, not independently measured outcomes.
| Piece, as this page names it | Status already on this page | What it does not replace |
|---|---|---|
| Maestro | Public preview | Identity control, human accountability, or an integration test |
| Live Map | With design partners | A general release |
| Agent Contracts | Described as machine-readable boundaries. Planned for October 2026 | A policy a person is no longer accountable for |
| Guardian Agents | Described as a planned runtime-supervision layer. Planned for October 2026 | A reason to skip review at the point of action |
Machine-readable policy is useful if it is testable. It is not a substitute for deciding, before the agent acts, what it may read, disclose, contact, publish, or spend: authority-in-the-loop [blocked].
Maestro: governance automation inside the Collibra environment
Confirmed: Collibra says customers can access Maestro today, with Maestro Studio and Maestro Assistant in public preview. Maestro Studio is described as a visual environment where governance teams configure agents, including their persona, permissions, tool access, and knowledge sources. Maestro Assistant is described as the chat interface through which end users interact with those agents.
The practical significance is modest but real: governance work that already resides in the platform may be easier to structure into repeatable workflows. It does not confirm that an enterprise can now govern every third-party agent in production. Public preview is an invitation to evaluate, not a guarantee of coverage, maturity, or suitability for a specific regulated workflow.
Live Map: a design-partner bet on reusable context
Confirmed: Live Map is opening this quarter to a small group of design partners, according to Collibra. It is intended to give agents a context graph describing entities across enterprise documents, their relationships, and how those relationships change. Collibra presents it as a way to avoid reconstructing the same context for every question and to support retrieval from curated unstructured content.
That is a credible architectural problem to solve. Agents can generate fluent answers while relying on stale, incomplete, or improperly scoped context. However, the outcome remains unproven from the announcement. There is no disclosed general-availability date, compatibility list, benchmark, or independent performance evidence in the cited materials. Inference: if Live Map eventually makes provenance, freshness, and authorization visible inside retrieval workflows, it could strengthen the evidence available to a governance layer.
Agent Contracts and Guardian Agents: planned runtime governance
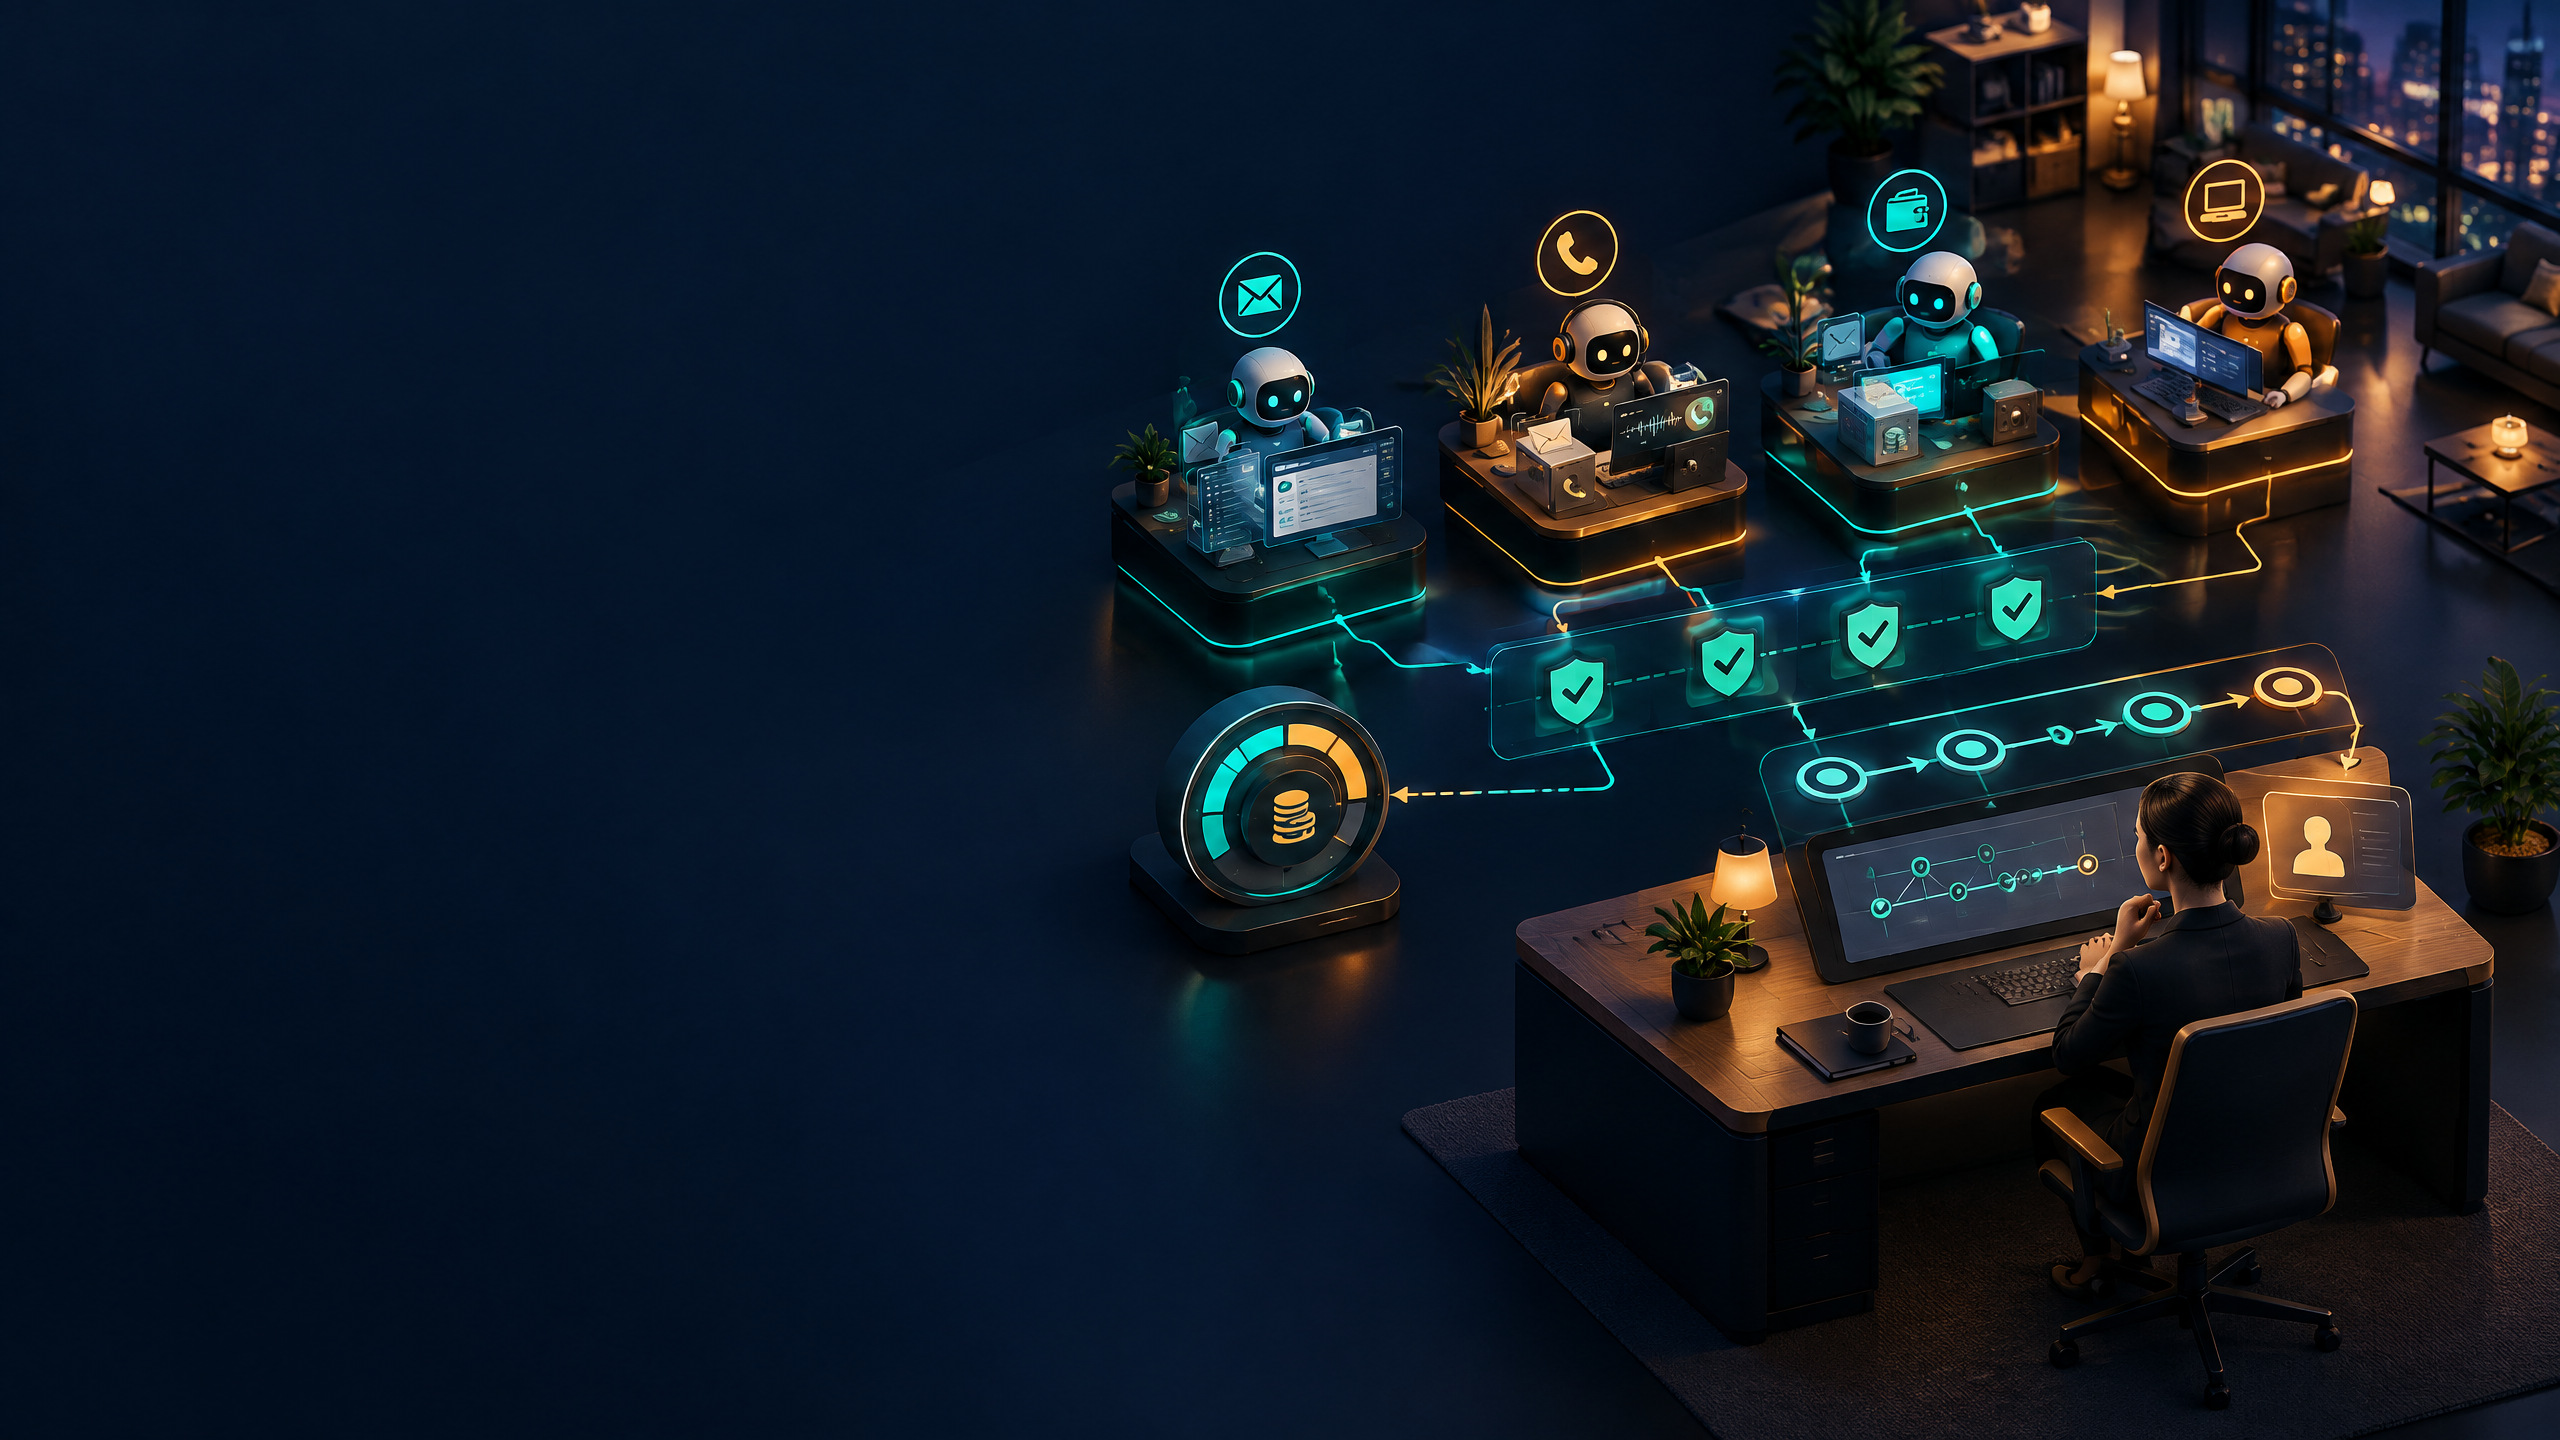
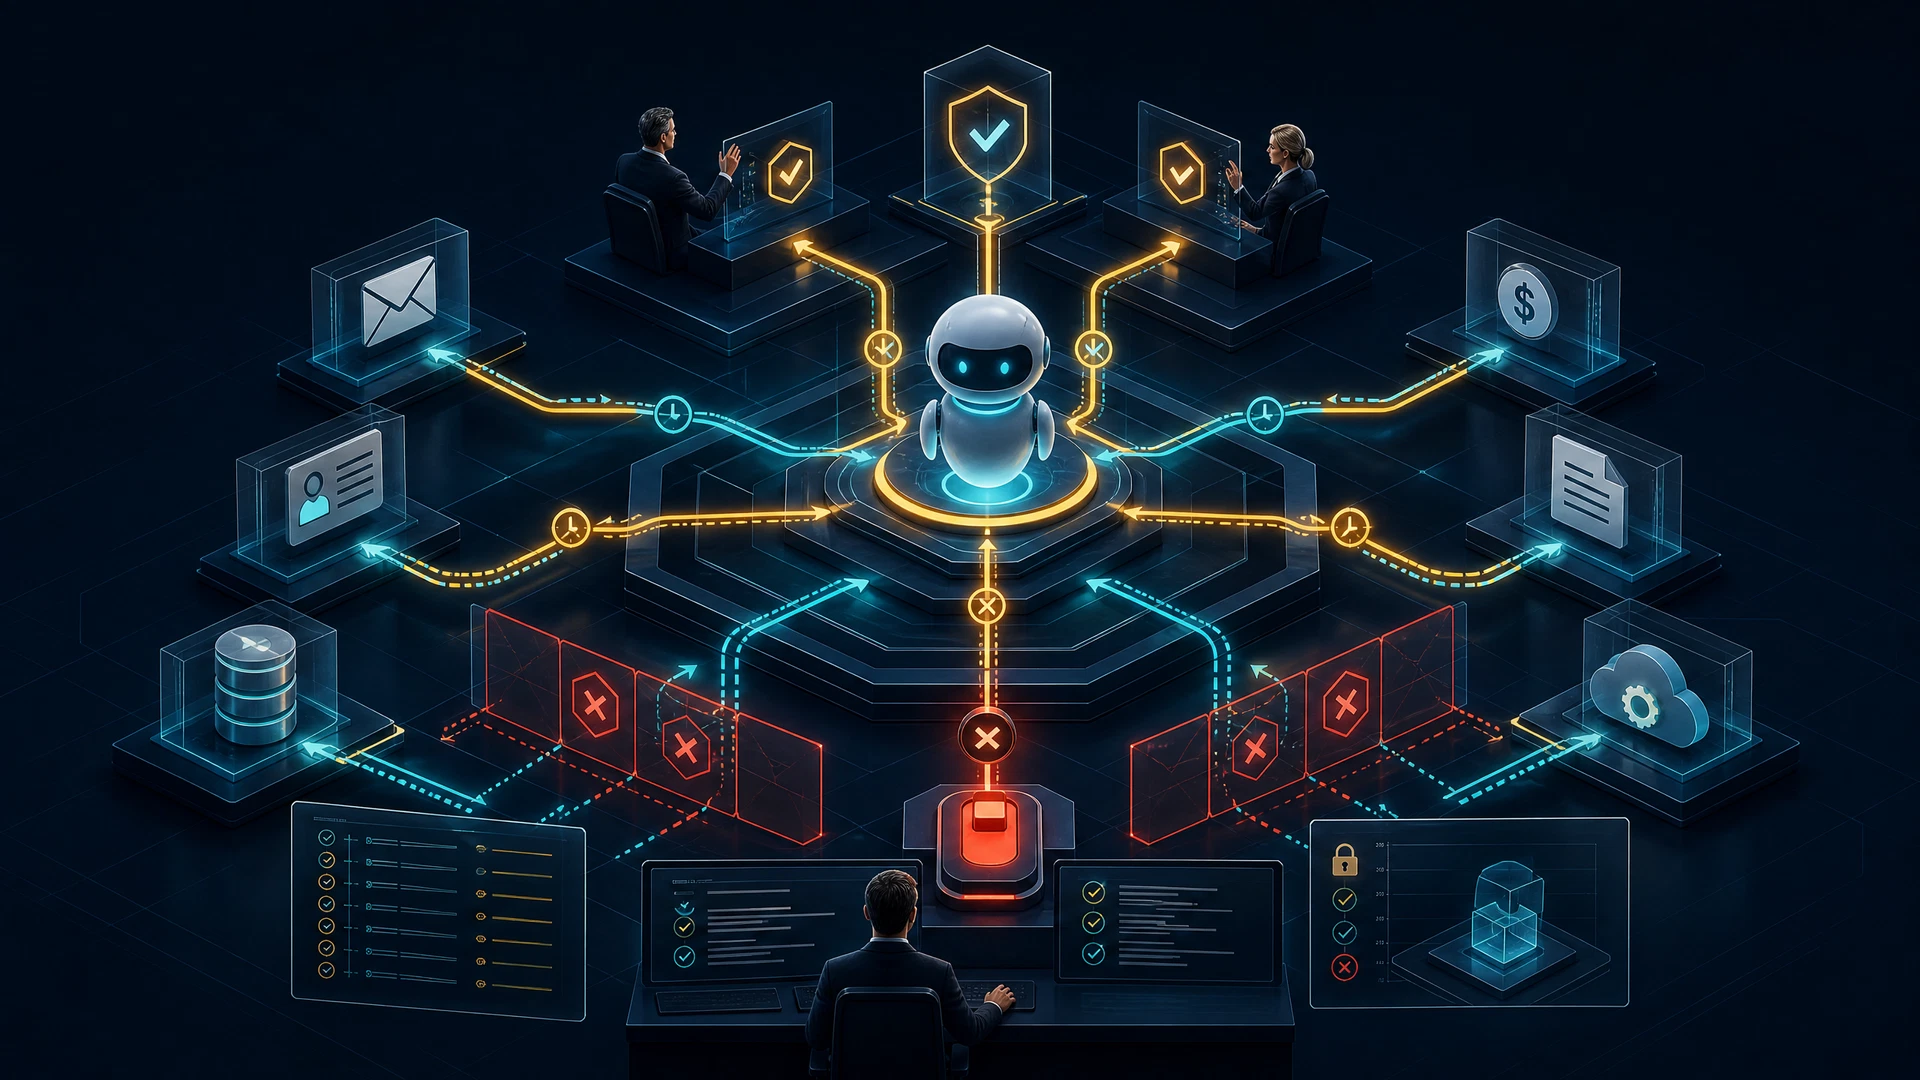
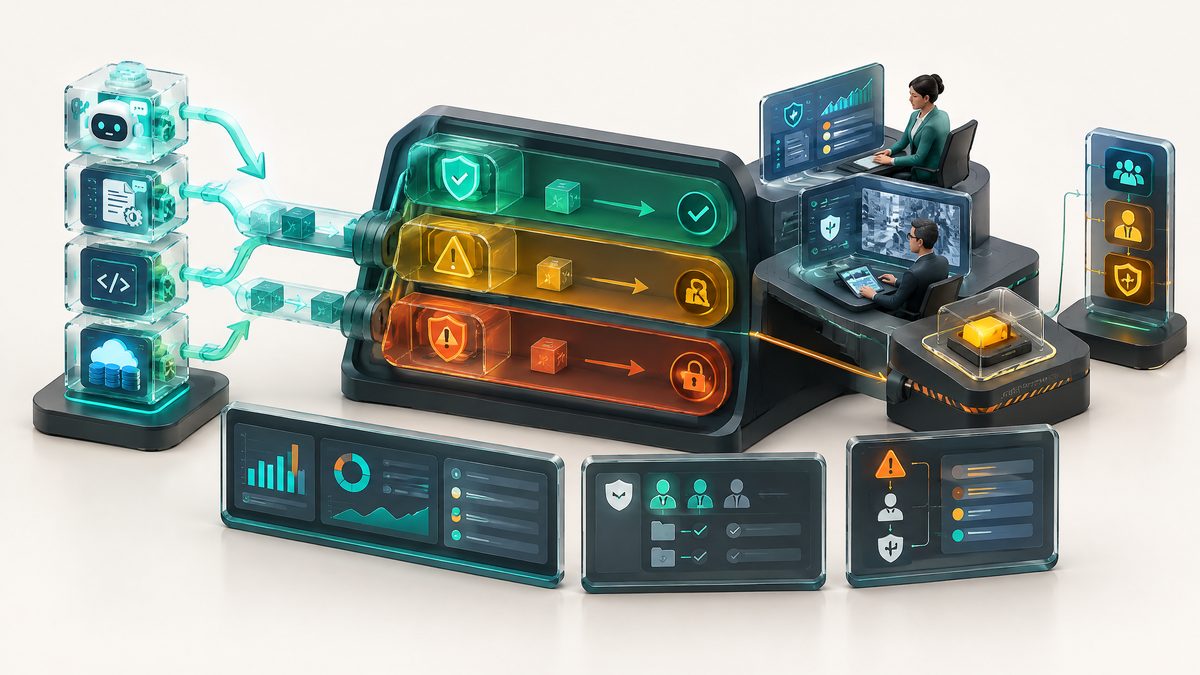
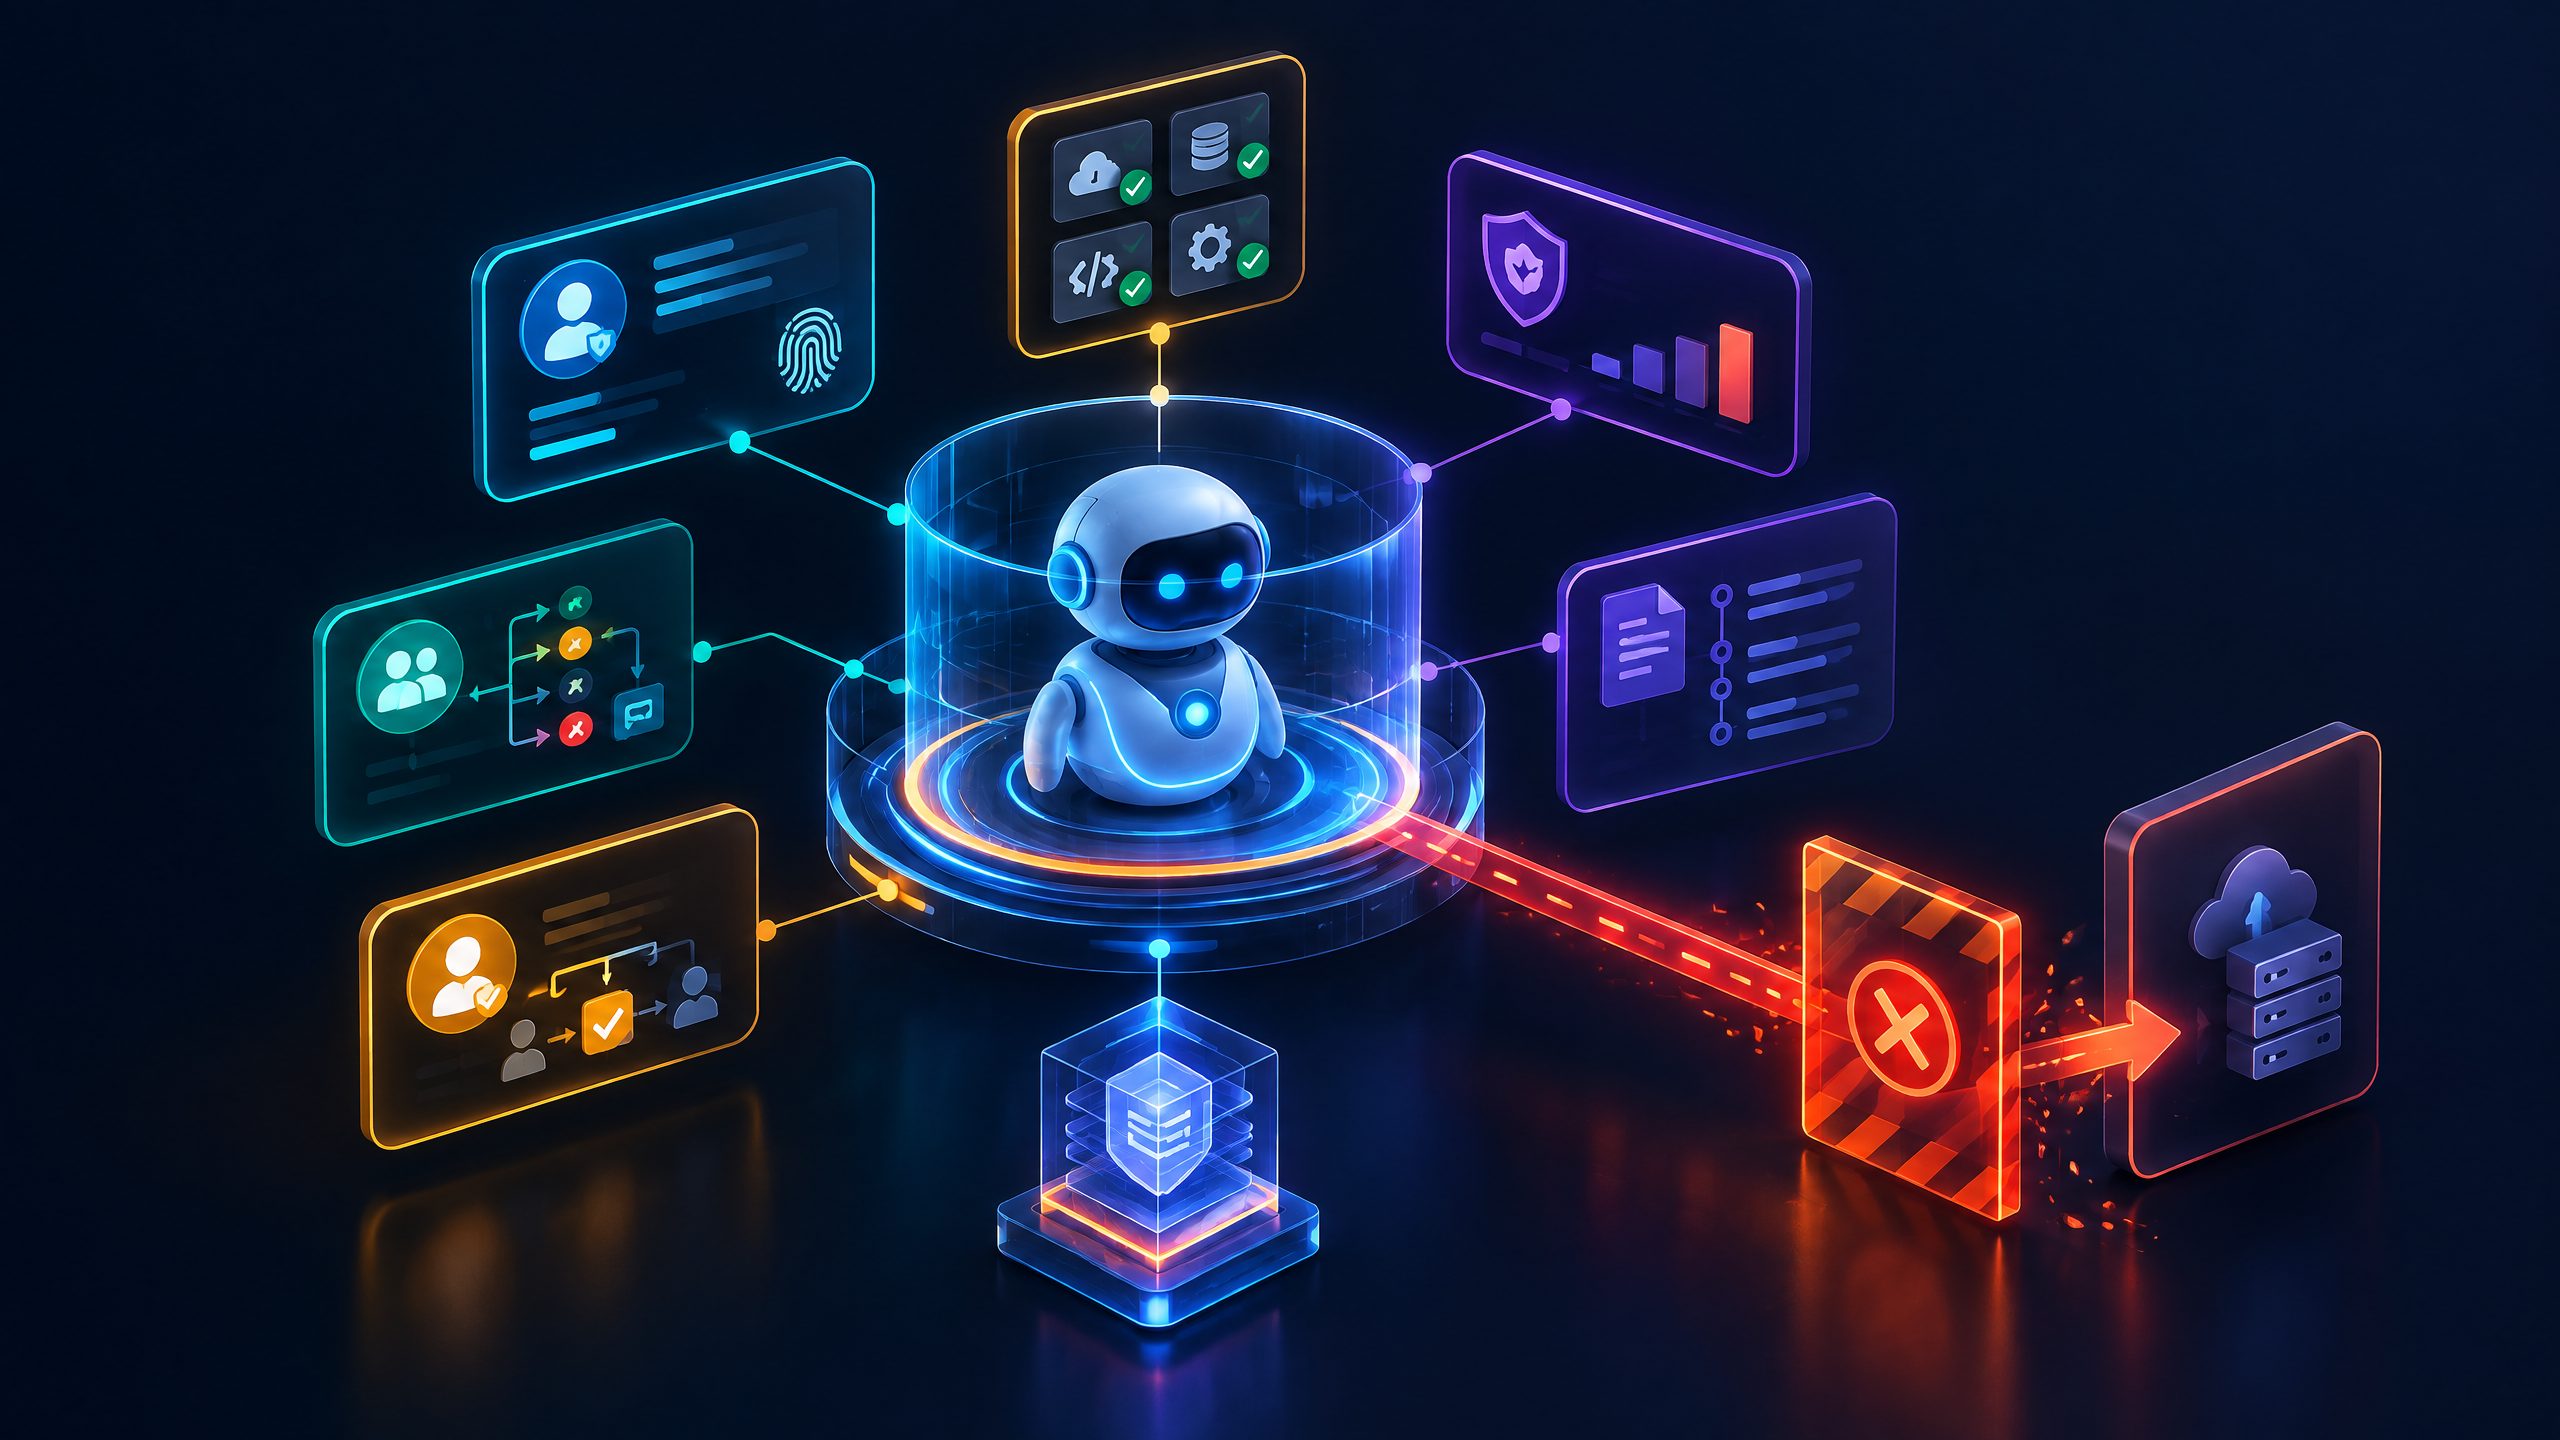
Confirmed: Collibra says Agent Contracts and Guardian Agents are planned to be available through AI Command Center in October 2026. Its product description separates two roles. Agent Contracts define machine-readable rules and intended operating boundaries. Guardian Agents are intended to read applicable contracts at runtime and supervise behavior, with possible responses ranging from flagging and escalation to blocking an unauthorized action.
Collibra describes contracts as a layered model: global contracts establish a minimum enterprise code of conduct, while specialized contracts add controls by function, specialty, risk class, or operating context. The company also says the approach is designed as an open standard independent of a specific runtime environment. That is a product claim and design intent, not proof of runtime neutrality today. The announcement does not establish which frameworks, clouds, tools, or agent runtimes will be supported at launch, how policy conflicts resolve, or when blocking will be technically possible.
Why readable policies are not enough for agent fleets
Human-readable policy remains necessary. It provides intent, accountability, legal interpretation, and a place for exceptions that cannot be compressed into a rigid rule. But agents cannot reliably act on a 40-page policy just because it exists in a document repository. They operate through identities, data permissions, tools, APIs, prompts, retrieval sources, thresholds, and action sequences.
A usable control model therefore needs a bridge between the policy and the operating environment. Consider a marketing research agent that may summarize approved public sources, query a licensed intelligence platform, draft a brief, and create a task in a work-management system. Its policy needs more than “protect confidential information.” It needs explicit answers: which data classifications are out of bounds; which source domains count as acceptable evidence; whether a human must approve an external-facing draft; whether the agent may create, edit, or only propose tasks; and which actions require a review record.
Collibra’s approach is notable because it attempts to join explicit controls with intent-level context. In its description, a contract may reference an agent’s use case, model, tools, data, metadata, policies, and ownership. This is closer to a governance object than a static checklist. Yet it also raises a hard implementation question: an executable rule is only as dependable as the systems that interpret it and the data that keeps it current.
A stale data classification, an unregistered tool, a bypassed integration, or an overly broad service identity can make a formally correct contract operationally weak. Machine readability is valuable because it enables consistency and testing. It is not a substitute for identity architecture, data governance, human decision rights, or monitoring.
The announcement’s evidence base needs careful reading
Collibra supports the announcement with findings from its 2026 Hallucination Tax Report, a survey conducted by The Harris Poll on Collibra’s behalf. The company reports that 76% of data and AI decision-makers hit critical roadblocks moving agents from pilot to production in the prior 12 months; 87% regularly re-verify that agent context is accurate and current; and 51% spend significant staff hours manually reviewing and correcting autonomous-agent outputs before go-live. These figures are useful indicators of where respondents say work accumulates, but they remain vendor-sponsored survey results, not universal rates or a causal test of the announced products.
The phrase “hallucination tax” also deserves precision. In this context it is Collibra’s label for costly re-verification, correction, and loss of trust associated with unreliable agent outputs or context. It is not a standardized financial measure, and the cited announcement does not calculate a dollar value for it.
That baseline matters because the most consequential claim in the launch is not that policies can be made machine-readable. It is that those rules could be applied across an agent fleet and enforced at runtime. The answer will depend on deployment coverage and quality, not on vocabulary. Contracts that work only inside one control plane may still be useful. They simply should not be represented as enterprise-wide governance until the organization has tested its actual agents, tools, permissions, and workflows.
A practical checklist before treating policy as executable
Use the following questions to assess the operating model—not just the announcement.
- Inventory the agents and action surfaces. List each agent, owner, business purpose, model, data sources, tools, APIs, identities, and actions it can initiate. Include shadow or team-built agents where possible.
- Translate one high-value policy into testable boundaries. Start with a workflow that has clear data classes, permitted tools, approval conditions, and prohibited actions. Avoid trying to encode every policy at once.
- Define global and specialized layers. A global baseline might cover identity, logging, protected data, and escalation. Specialized layers should address a finance, HR, marketing, or customer-service agent’s particular risk and authority.
- Name the enforcement point. Identify where each rule is evaluated: before tool invocation, during retrieval, before a system write, after output generation, or in a human review queue. “Runtime enforcement” is incomplete without a precise control point.
- Make exceptions explicit. Define who can override a rule, for how long, with what approval, and what record is retained. Unlogged exceptions are often where real governance erodes.
- Test failure paths, not only happy paths. Try stale context, a newly restricted field, prompt injection, a request outside purpose, excessive privilege, a missing owner, and an unavailable approval reviewer. Record the expected and observed response.
- Measure evidence rather than intent. Track contract version, decision logs, tool calls, blocked or escalated actions, human overrides, review time, and unresolved incidents. These metrics help show whether the control works in the workflow it is meant to govern.
This checklist is technology-neutral by design. It remains relevant whether Collibra’s planned capabilities meet a particular organization’s needs or not.
The commercial implication: governance becomes an operating design issue
Marketing, growth, and operations leaders may be tempted to treat governance as the team that arrives after an agent program has been designed. That approach becomes expensive once agents touch customer data, publish content, change campaign settings, update CRM records, or coordinate across multiple systems. The better design question is: what authority is needed for this defined task, for this time period, against these sources and tools—and what must happen if the agent is uncertain?
That question aligns with the prior Integrated.Social analysis, “AI Agents Do Not Need More Access. They Need Contextual Authority” [blocked]. The goal is not to freeze useful automation. It is to give agents narrowly scoped authority that a team can explain, inspect, and withdraw.
For organizations deploying agents in commercial workflows, Integrated.Social can help scope a controlled evidence, measurement, or governance review before broader rollout, including decision rights, source quality, approval gates, and test cases. See our Agentic AI services [blocked]. This is a scoping and design activity, not a promise that a particular platform or control will eliminate errors, generate revenue, or satisfy every compliance obligation.
What to watch in October
The announcement has set a useful standard for what Collibra should disclose next. Buyers and governance leaders should ask for a supported-runtime matrix; contract syntax or open-standard documentation; examples of global-versus-specialized rule inheritance; conflict-resolution behavior; modes for monitor, escalate, and block; identity and permissions integration; audit-log contents; and a clear account of what is preview, design partner, planned, or generally available.
The central idea is sound: agent governance will be stronger when policy can be represented in forms systems can evaluate. But the end state should not be “policies without people.” It should be policies that remain interpretable by people, executable by systems where appropriate, measurable in practice, and reversible when evidence shows a control is failing.
FAQs
What are Collibra Agent Contracts?
They are Collibra’s proposed policy object for an agent fleet. In the company’s model, an enterprise can express a common behavioral baseline once, then attach stricter or more specific conditions to an agent group—for example, when its task, data sensitivity, or operating setting warrants them.
Are Collibra Agent Contracts available now?
Not at the date of this article. Collibra’s stated target is October 2026 through AI Command Center. The public preview designation applies to Maestro Studio and Maestro Assistant, while Live Map is at the design-partner stage; those labels should not be transferred to the planned Contracts and Guardians release.
How do Guardian Agents differ from Agent Contracts?
Think of the contract as the declared operating boundary and the Guardian as the proposed supervisory mechanism. Collibra says a Guardian may observe behavior against the applicable boundary and respond with monitoring, escalation, or an action block, depending on the implementation and enforcement mode.
What should an enterprise validate before adopting machine-readable agent governance?
Start with a bounded pilot rather than a platform-wide declaration. The team should be able to show which agents are covered, where rules are evaluated, what happens when a rule fails, who can approve exceptions, and which logs demonstrate the control operated as designed.
Sources
- Collibra press release, September 23, 2026: https://www.collibra.com/company/newsroom/press-releases/collibra-launches-new-capabilities-to-reduce-the-hallucination-tax-on-enterprise-ai
- Collibra, “Agent Contracts: Set the boundaries for your entire AI agent fleet,” September 23, 2026: https://www.collibra.com/blog/agent-contracts-set-the-boundaries-for-your-entire-ai-agent-fleet
- WindowsForum, “Collibra Maestro Enters Preview; Agent Contracts Arrive in October”: https://windowsforum.com/news/collibra-maestro-enters-preview-agent-contracts-arrive-in-october.445774/?amp=1