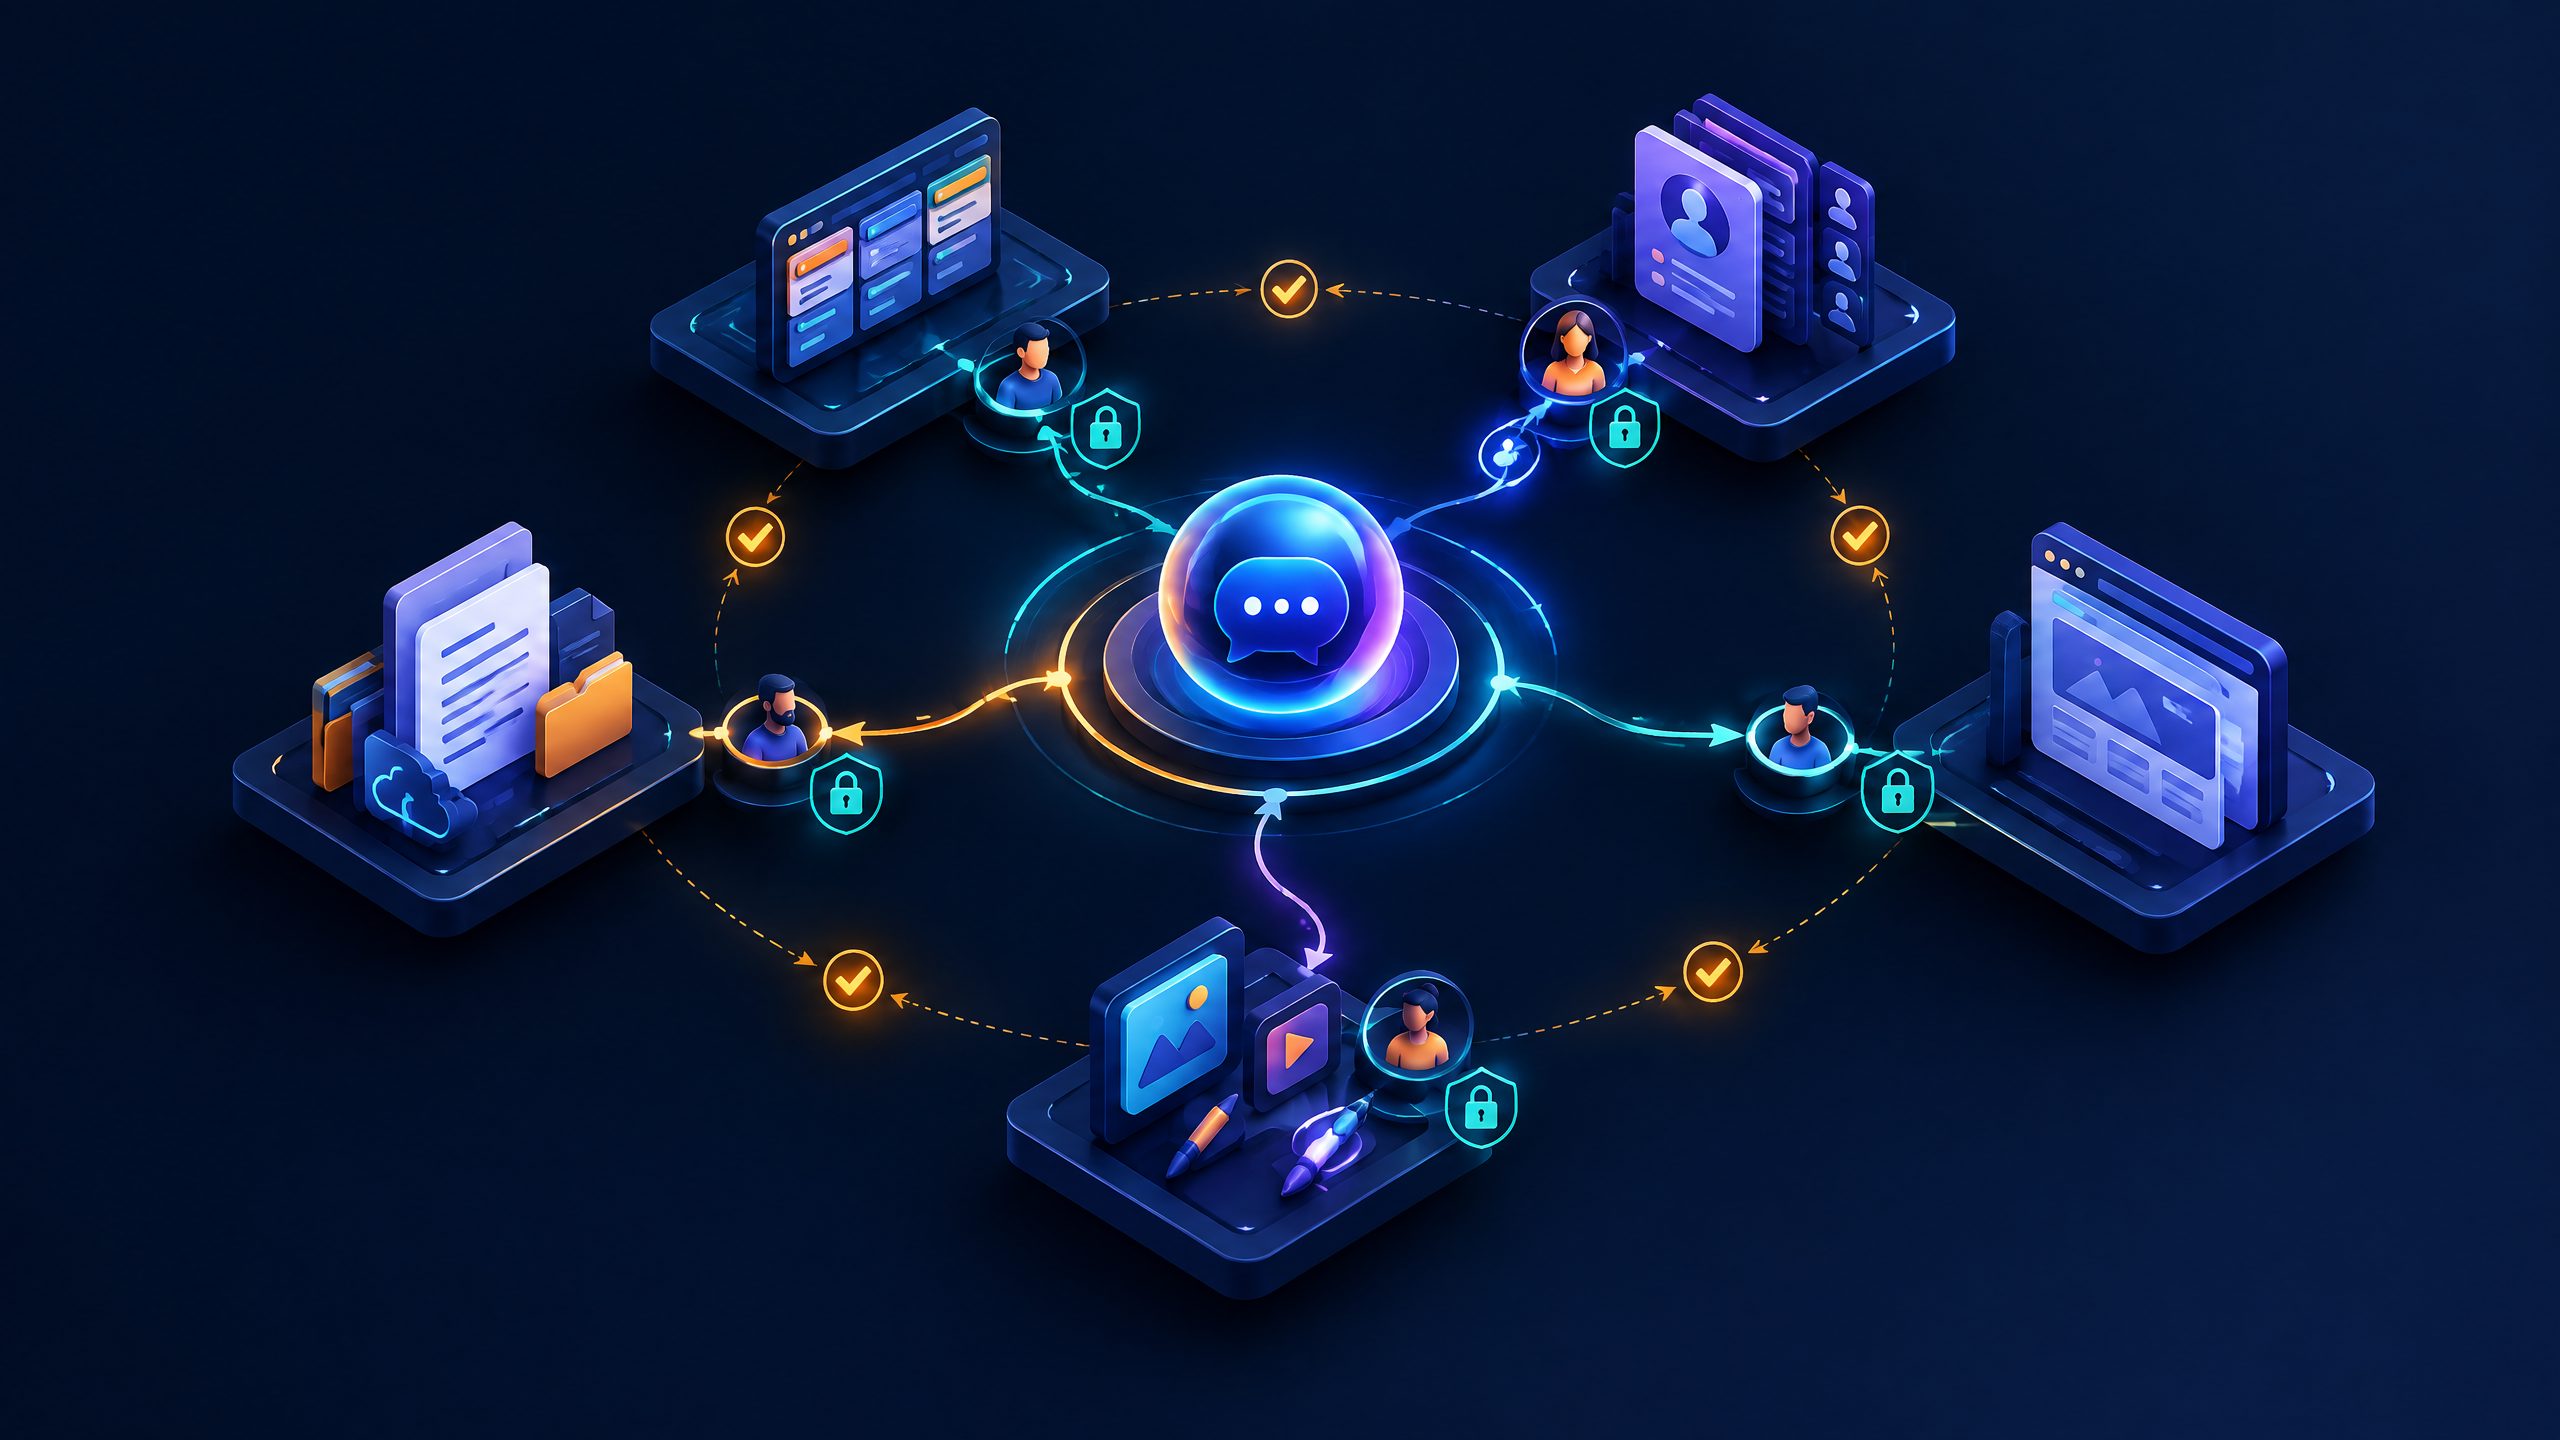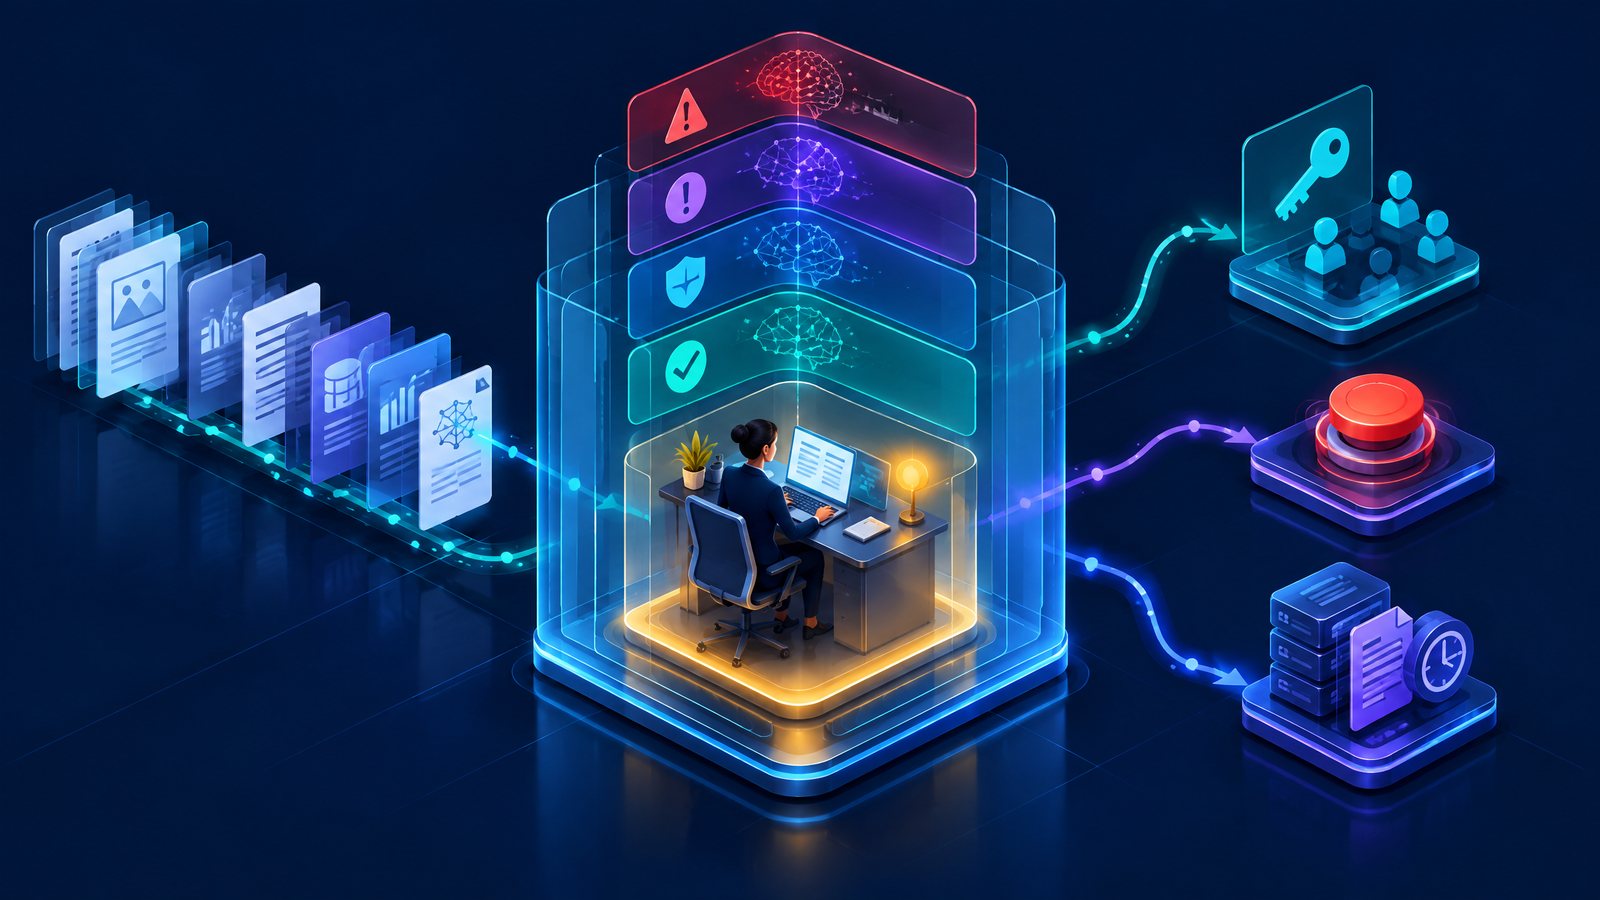
Global brands can govern AI-assisted content without turning every draft into a bottleneck by matching the level of control to the content, the data, the audience, and the action being authorized. The practical goal is not to certify outputs as safe, accurate, compliant, or legally cleared. It is to create a reviewable operating system: one that makes authority, evidence, permissions, exceptions, and accountable human decisions visible before publication or system action.
The operating question is not “AI or human?”
The wrong question is whether a human touched the draft. A spellcheck may be immaterial; a localized healthcare claim, synthetic executive video, or autonomous CMS update may need meaningful review. Ask: what could this content do, who could it affect, what information or rights does it involve, and who may make the next decision?
Teams do not need identical sign-off for an internal outline and a consumer-facing price claim, but they do need a consistent route through intake, evidence, review, publication, monitoring, and exception handling. This is a proposed management design, not evidence of a legal duty being met or liability removed.
For workflow architecture, see AI Content Operations. For a cross-functional decision model, explore AI Governance; leaders can consider AI Training for Leaders. These are implementation discussions, not legal or regulatory determinations.
Start with risk tiers and decision rights
A risk tier is a routing device, not a moral label. Set it at the use-case level and raise it when the system gains new data, channels, tools, audiences, or actions. Drafting copy is not the same as publishing, purchasing media, changing customer records, or responding publicly.
| Proposed tier | Typical content scenario | Minimum operating control | Decision right that stays human |
|---|---|---|---|
| Tier 1: bounded assistance | Internal outline, headline variants, meeting summary from approved non-sensitive material | Approved tool, restricted source set, retained prompt family, author review before reuse | Content owner decides whether the work is fit for its stated internal purpose |
| Tier 2: standard external content | Product explainer, social draft, localized landing-page copy without regulated claims | Evidence rubric, claim/source check, sampled human audit, named publisher | Editor or market owner approves the published version |
| Tier 3: sensitive or consequential content | Health, finance, employment, political, pricing, testimonial, child-directed, or public-interest material | Subject-matter reviewer, privacy and claims screen, versioned evidence pack, mandatory approval gate | Authorized accountable owner can approve, amend, pause, or reject |
| Tier 4: autonomous or high-impact action | Agent uses tools to publish, alter customer-facing records, procure media, or act on personal data | Default-deny permissions, sandbox or staged environment, real-time monitoring, stop control, incident route | Named business and control owners authorize any move from test to live use |
Decision rights should be explicit. Name owners for the business purpose, content brief, domain evidence, escalation route, and publication stop. An AI system can propose, classify, summarize, or compare within its permissions. It should not become the owner of a claim, consent decision, rights assessment, or public statement.
This matters especially for agentic workflows. The NCSC advises organizations to start small, constrain scope, use least privilege, avoid long-lived credentials, monitor behavior, and retain meaningful human control.1 An agent may retrieve from an approved repository or draft in staging, while publishing, sending, payment, permission changes, and customer-record writes remain gated. For patterns, see Gemini Agentic AI; suitability still depends on the use case and controls.
Make review testable: rubrics, golden answers, and spot audits
A review queue slows when reviewers rediscover the standard. A rubric should ask decision-linked questions: Is each material factual statement traceable to an approved source? Are product, pricing, availability, and comparative claims supported for this market? Are qualifications preserved? Is the audience and locale correct? Has the content crossed a data, rights, or escalation boundary? Is the next action permitted?
| Rubric dimension | Example review question | Evidence retained |
|---|---|---|
| Brief fidelity | Does the asset answer the approved audience and purpose rather than inventing a new offer? | Versioned brief and acceptance criteria |
| Source support | Can a reviewer locate support for material factual or comparative statements? | Source IDs, quotations or notes, and date checked |
| Claims and context | Are limitations, market qualifiers, and required disclosures presented with the claim? | Approved claims library and reviewer decision |
| Brand and locale | Does the wording match approved positioning and local constraints? | Locale/version identifier and market-owner review |
| Data and permissions | Did the workflow use only allowed data, tools, and channels? | Access log, data class, and tool-action record |
| Action boundary | Is publication or handoff within the authority given to this workflow? | Approval event, named approver, and release record |
Build a golden answer set from hard cases, not polished demos: approved examples, deliberate failures, refusals or escalations, conflicting sources, stale information, named-person references, and market variants. Each needs an expected treatment, reviewer evidence, and a rationale. It is a regression tool for detecting change at known decision boundaries, not proof of future consistency.
LLM-as-judge can score against a narrow rubric or route mismatches to a queue, but it is not an independent source of truth. It can share blind spots with the generator and be prompt-sensitive. Use it for triage, comparison, and flags, not final decisions on substantiation, personal data, permissions, legal interpretation, public-interest publication, or high-impact action. Calibrate it against the golden set and sample its passes as well as failures.
Human spot audits counter false assurance. Sample markets, languages, types, models, prompt families, and outcomes, increasing the rate after a material change or incident. Review published assets and automation passes. Track disagreement and fix the source, policy, prompt, retrieval boundary, permission, or decision right involved. A low rate on a small or easy sample is not a universal finding.
Amazon UK resource callout: Competing in the Age of AI is a defensible strategy reading choice for leaders who need to discuss operating-model change alongside governance. It is not a regulatory guide or a substitute for expert review. View the book on Amazon UK. As an Amazon Associate, Integrated.Social may earn from qualifying purchases.
Record provenance as a decision trail, not a marketing badge
Provenance should answer: “How did this version reach this channel, under whose authority, and using what source material?” Link the asset ID to the brief, source set and retrieval date, model and prompt version, key tool actions, human edits, evaluation, approvals, locale, publication, and correction history. Keep the record proportionate and avoid unnecessary personal data in audit logs.
C2PA’s Content Credentials standard can express origin and edits in digital content, particularly in image and video workflows.2 It does not prove truth, consent, ownership, substantiation, or suitability in a jurisdiction; absence is not proof of deception. Treat technical provenance as review input, not a verdict.
The same boundary applies to transparent AI labels. Under the EU AI Act, Article 50 has different obligations for different roles and scenarios. The Commission states that providers of certain directly interactive systems need to inform people they are interacting with AI, and providers of generative systems must support machine-readable marking of covered synthetic outputs. Deployers have distinct duties relating to, among other scenarios, deepfakes and AI-generated or manipulated text published to inform the public on matters of public interest without human review or editorial control.3 4
The scenario boundary matters. The Commission describes a provider as an entity that develops, or has developed, and places an AI system on the EU market or puts it into service under its name; a business using it under its authority may be a deployer.4 Direct interaction, output, audience, human review, editorial responsibility, and value-chain role affect analysis. Article 50 applies from August 2, 2026, with a limited marking-and-detection grace period for certain pre-market systems.4 Use the operative text and Commission guidance with advice appropriate to the scenario; this article does not decide scope.
Screen data, rights, and claims before they enter the model
Personal-data screening belongs at intake. Classify direct identifiers, customer correspondence, employee information, special-category data, inferred segments, and data that can become identifiable when combined. GDPR principles include lawfulness, fairness and transparency, purpose limitation, minimization, accuracy, storage limitation, and integrity and confidentiality.5 A governance log does not establish those conditions.
For higher-risk proposals, use the privacy route before sending material to a model, connector, or agent. The ICO describes DPIAs for processing likely to result in high risk and notes its guidance is under review following UK data-law changes.6 Capture data category, purpose, recipients, retention, transfer path, and whether local assessment is required. A “no sensitive data” checkbox is not a conclusion.
Copyright and text-and-data-mining questions need the same restraint. UK CDPA 1988 Section 29A permits certain copies by someone with lawful access for computational analysis solely for non-commercial research, with acknowledgment where practical.7 It is not permission for commercial training, reuse, or AI-workflow copying. Rights, licenses, contracts, database and moral rights, platform terms, and local law can matter. Preserve source, permission, territory, allowed use, expiration, and restrictions; escalate ambiguity before reuse.
Advertising review is distinct. The UK CAP Code says marketing communications must not materially mislead and requires documentary evidence for objective claims capable of substantiation before publication.8 An LLM can flag a superlative or missing qualifier; it cannot establish evidence or decide interpretation. Pair a claims library with named owners, market evidence, and escalation for comparative, price, environmental, performance, health, or testimonial claims.
Amazon UK resource callout: The Coming Wave can be useful background reading for a leadership discussion about containment and wider technology change. It is commentary, not a privacy, copyright, advertising, or AI Act authority. View the book on Amazon UK. As an Amazon Associate, Integrated.Social may earn from qualifying purchases.
How to implement a human-in-the-loop AI content governance system
1. Inventory one content workflow and set its boundary
Choose one repeatable workflow, such as drafting localized product explainers, and map its input data, audience, languages, channels, tools, potential actions, and stop conditions. Assign a proposed risk tier based on the highest-risk plausible output or action, not the average case. Name what the workflow may not do, including publishing, using personal data, accessing unapproved sources, or making claims outside the evidence pack.
2. Assign decision rights and a reachable escalation path
Name the business owner, content owner, subject expert, publisher, security or platform owner, and routes for privacy, legal, advertising, or rights questions. State who can approve, reject, pause, change scope, and revoke access. Ensure the person who detects a problem can actually stop the workflow rather than merely file a report after the asset has moved on.
3. Build a rubric and golden answer set before expansion
Translate the brief into reviewable criteria for source support, claims, locale, data, permissions, and action boundaries. Create a small golden answer set with approved cases, deliberate failures, refusal or escalation cases, and market variations. Run the proposed model, retrieval configuration, and prompt version against it before treating the workflow as ready for broader use.
4. Constrain data and tools with least privilege
Route only the minimum necessary approved data into the workflow, use temporary or scoped credentials where feasible, and separate read, draft, publish, and record-update permissions. Place agentic actions in a staging or sandboxed environment where appropriate. Monitor tool calls and set technical and operational limits that do not rely only on prompt instructions.
5. Retain provenance and run human spot audits
Store the brief, source set, model and prompt versions, key tool actions, evaluation, reviewer decision, approver, asset version, and publication in a proportionate record. Sample markets and types, including automated passes. Update the control that failed rather than silently increasing trust in the model.
6. Exercise escalation, correction, and shutdown procedures
Test how a reviewer flags a suspect claim, removes an asset, disables a connector, revokes a credential, informs accountable owners, and records the outcome. Decide in advance which incidents trigger a privacy, rights, security, or advertising review. Rehearsal does not guarantee prevention, but it exposes responsibility and evidence gaps before scale.
Author POV: governance is a product decision
In my view, governance should be designed into the content factory, not added as a legal sign-off. A reviewer should see the purpose, source boundary, permissions, proposed action, and accountable owner without reconstructing chat logs.
The test is whether a regional editor, privacy lead, product owner, or security team can say “not this version, not this data, not this market, not this action” and have the system respect it. That creates a basis for scoped learning, not a promise of output quality, legal compliance, commercial performance, or incident-free operation.
Series navigation: From Prompt to Profit
Part 2 of From Prompt to Profit: The AI Content Operating System for Global Brands.
- Part 1: Agentic AI Content Workflow for Global Brands
- Part 2: Human-in-the-Loop AI Content Governance
- Part 3: Technical SEO, AI Search, and Search Console
- Part 4: Voice, Visual Search, and Agentic Commerce
- Part 5: Organic, Paid, and Agentic AI CPA/LTV
For an adjacent operational perspective, read our existing AI governance and quality-control guide. The next articles address discoverability and measurement, but governance remains distinct from search visibility or media performance.
Frequently asked questions
What is human-in-the-loop AI content governance?
Human-in-the-loop AI content governance is an operating approach in which named people retain decision rights over defined content, data, claims, permissions, and release actions while AI systems assist within bounded tasks. It uses risk tiers, review criteria, evidence records, sampled audits, and escalation paths. It is not a superficial click-to-approve process and does not prove compliance, safety, accuracy, or legal clearance.
How should a global brand choose AI content risk tiers?
A global brand should classify the use case by audience, subject matter, data, channel, claim type, autonomy, and potential action, then raise the tier when any boundary expands. Internal work with approved non-sensitive material may be lower risk than public, regulated, personalized, or agent-published content. A tier routes controls and accountable owners; it is not a statement that a model or market is safe.
Can an LLM judge AI-generated marketing content?
An LLM can help triage content against a defined rubric, compare drafts, or flag missing evidence for human review. It should not be the final authority on substantiation, personal-data use, intellectual-property permission, legal interpretation, or sensitive public claims. Test the judge against a curated golden answer set, retain disagreement cases, and audit items it passes because a model-generated score is not independent proof of the underlying facts.
What should an AI content provenance trail include?
An AI content provenance trail should link the asset version to its brief, approved sources, retrieval date, model and prompt-template version, key tool actions, human edits, evaluation results, approver, locale, publication event, and correction history. Capture only information that is necessary for accountability and investigation. Technical credentials can help express origin and edits, but they do not prove truth, ownership, consent, or the appropriateness of a particular use.
When might Article 50 of the EU AI Act matter for brand content?
Article 50 may matter when a brand or its suppliers provide or deploy covered interactive or generative AI systems, including scenarios involving direct AI interaction, machine-readable marking, deepfakes, or public-interest text without meaningful human review or editorial control. Role, output, audience, and deployment context affect the analysis. The European Commission guidance should be read with the Act and current local advice; this framework does not determine whether a specific asset is in scope.
Does UK copyright Section 29A permit commercial AI content training?
No broad commercial permission follows from UK CDPA 1988 Section 29A. The provision addresses copies made by someone with lawful access for computational analysis solely for non-commercial research and includes conditions. Brand teams should not treat it as a blanket authorization to train models, reuse third-party assets, or bypass licenses and terms. Assess the relevant rights, contracts, territory, data, and intended use through the appropriate internal escalation route.
Sources and methodology boundary
This framework synthesizes regulatory sources and security guidance. Read original sources and current versions. They do not validate every suggestion; this is not legal, privacy, security, advertising, or copyright advice. Test controls against actual systems, supplier terms, users, markets, processing records, and accountable decision-makers.
- NCSC, Thinking carefully before adopting agentic AI
- C2PA, Content Credentials and the provenance standard
- EUR-Lex, Regulation (EU) 2024/1689, the EU AI Act
- European Commission, Article 50 transparency guidance and FAQ
- EUR-Lex, Regulation (EU) 2016/679, the GDPR
- ICO, Data Protection Impact Assessments guidance
- UK legislation, Copyright, Designs and Patents Act 1988, Section 29A
- CAP Code, Section 3: Misleading advertising
About the Author
Modi Elnadi is the founder of Integrated.Social. He works with leadership teams on AI operating models, content systems, agentic workflows, and accountable ways to test emerging technology in marketing. His perspective here is operational: make the decision boundary, evidence, and human authority visible before increasing automation.