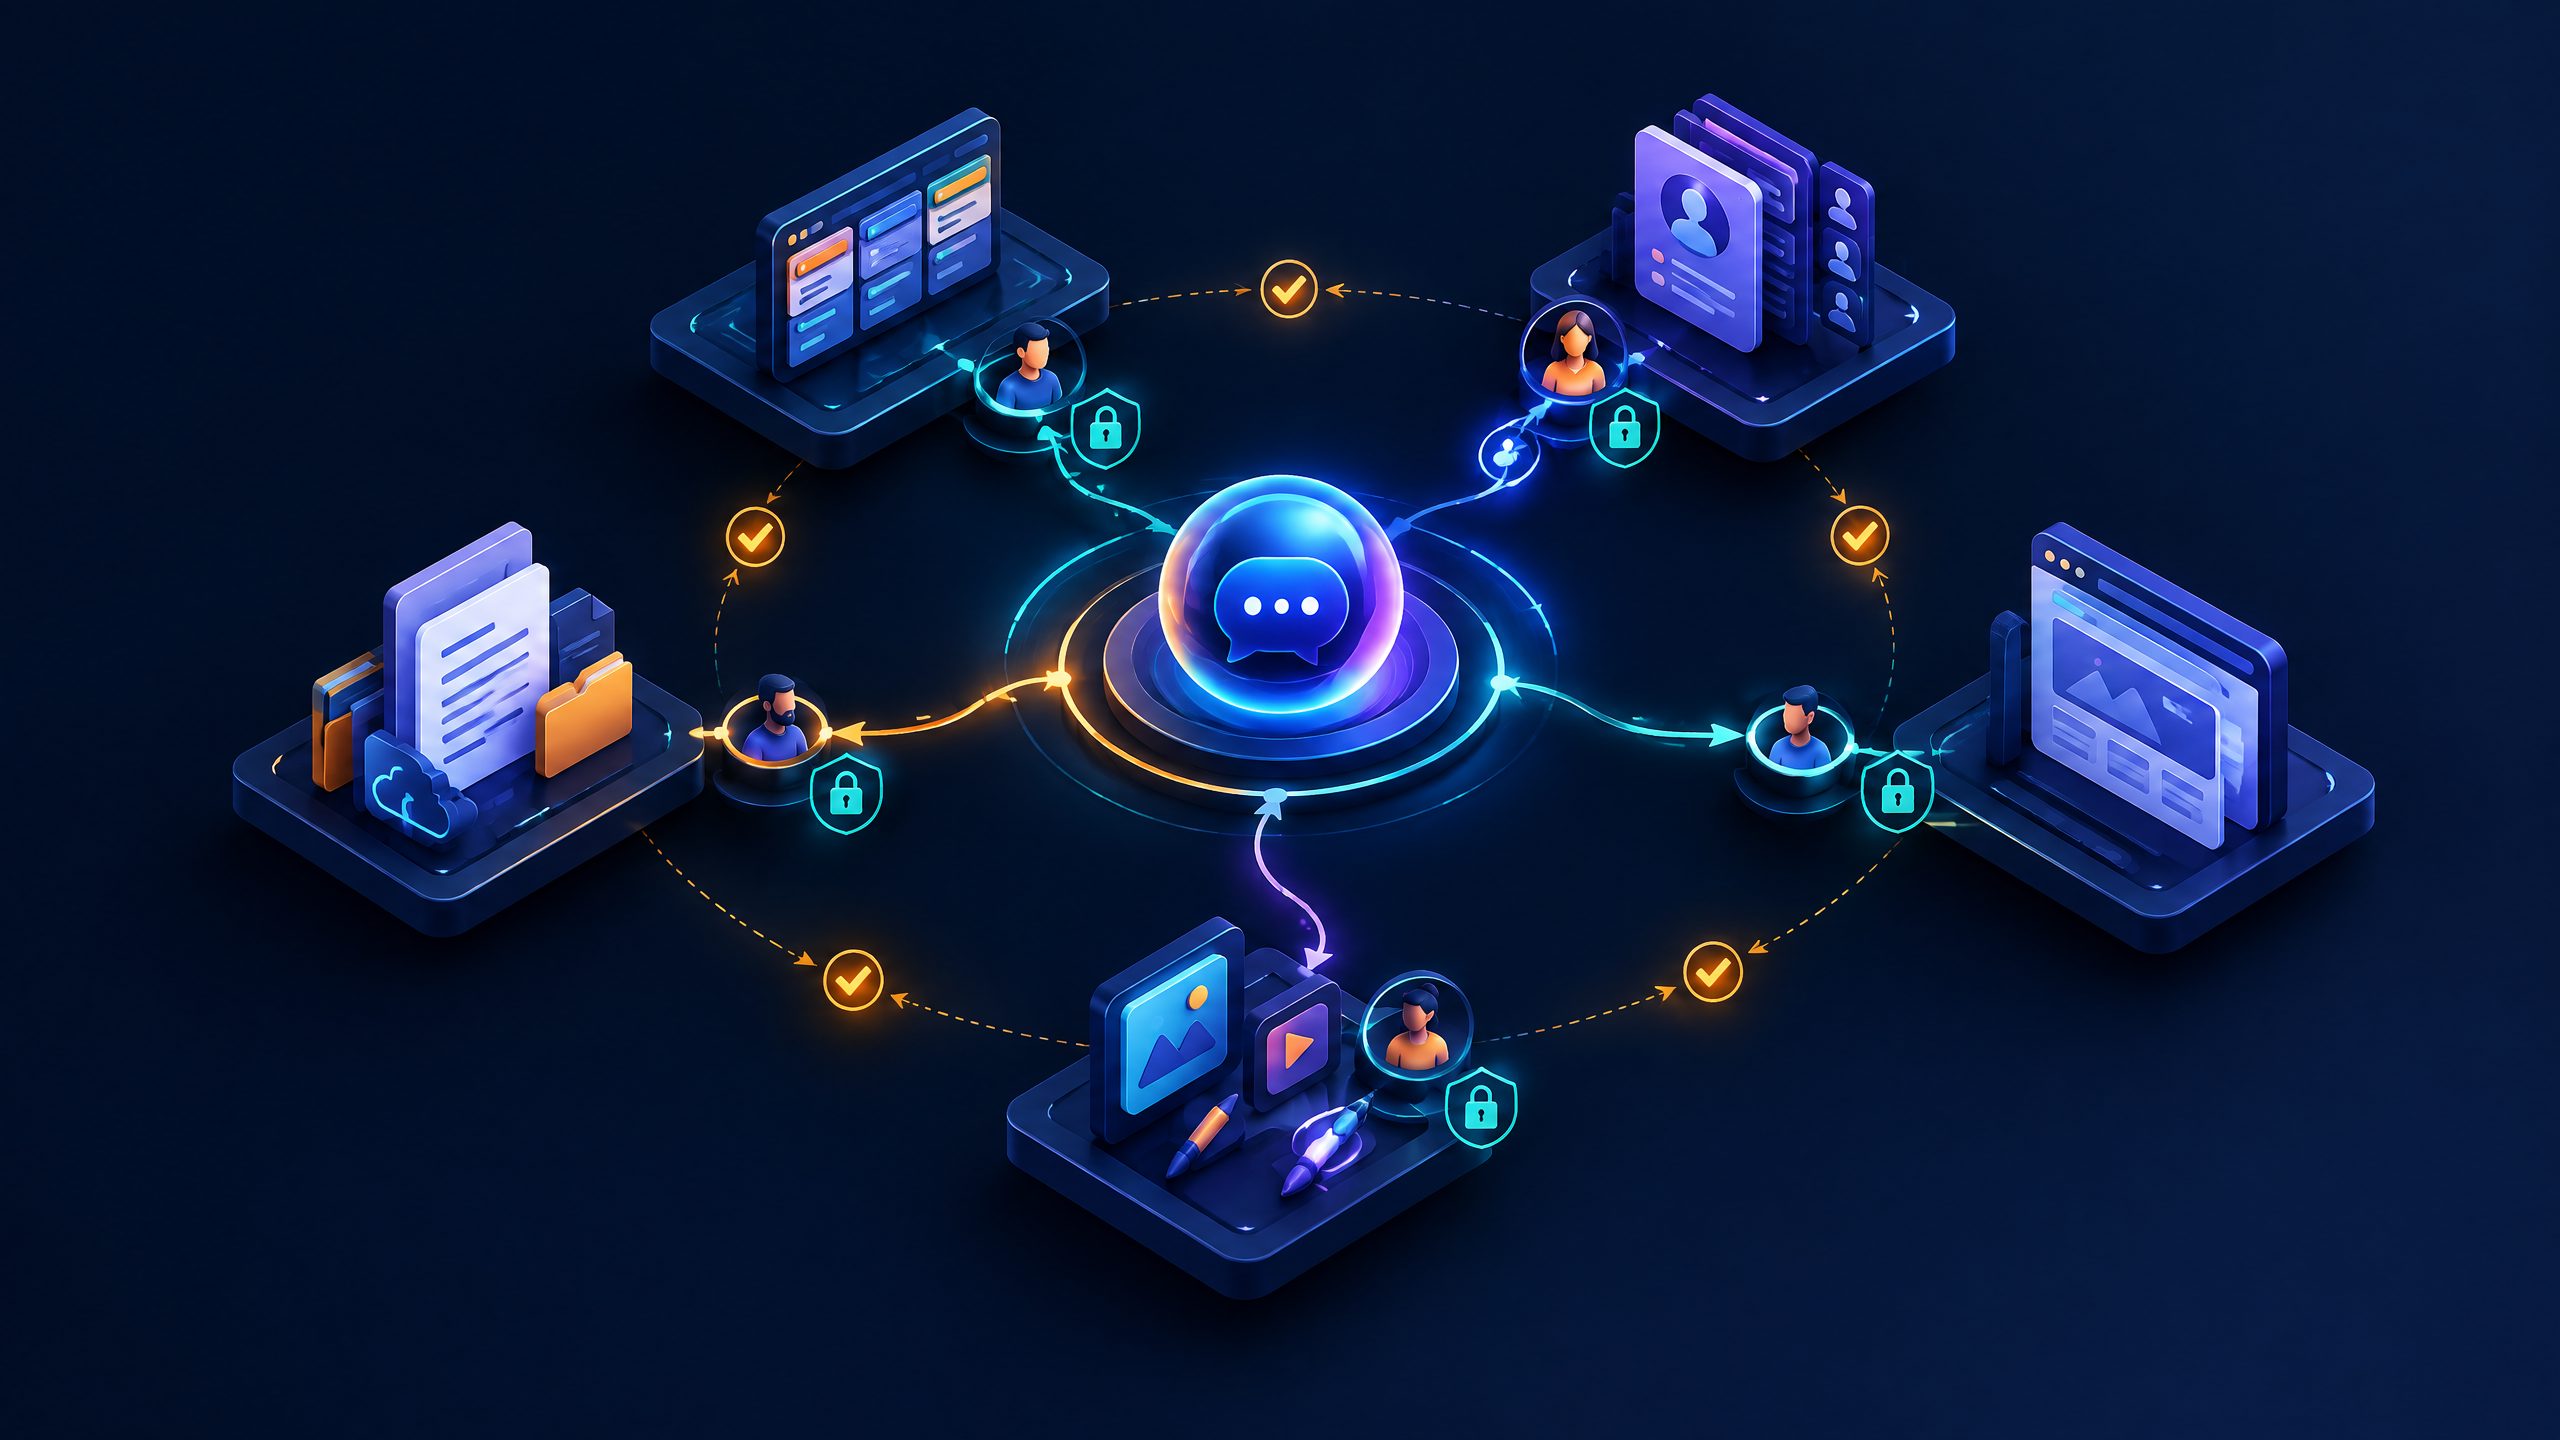
An agentic AI content engine is most useful when it starts with governed customer evidence, a versioned product truth, and explicit human decisions, then uses models to accelerate bounded research and drafting work. It is not a self-running publishing machine. For a global brand, the operating question is not which prompt produces the most fluent copy; it is whether every published claim can be traced to an approved source, understood in its local market context, and evaluated against a measurement plan that does not confuse activity with impact.
The operating principle: evidence before instructions
A prompt is a temporary instruction. An operating system is a repeatable way of deciding what information may enter a workflow, who can change it, what an agent may do with it, and who accepts responsibility for publication. That distinction matters because generative systems can produce plausible prose from incomplete, stale, or poorly scoped inputs.
Google describes grounding as connecting model output to verifiable information sources, which can tether output to specified data and reduce the chance of invented content. It also notes that grounding support can supply links back to sources. That is valuable workflow infrastructure, not a substitute for editorial substantiation. A source can be outdated, a quote can be used beyond its scope, and an internal document can express a commercial ambition rather than a defensible fact. Google’s grounding overview is a useful technical reference for keeping that distinction clear.
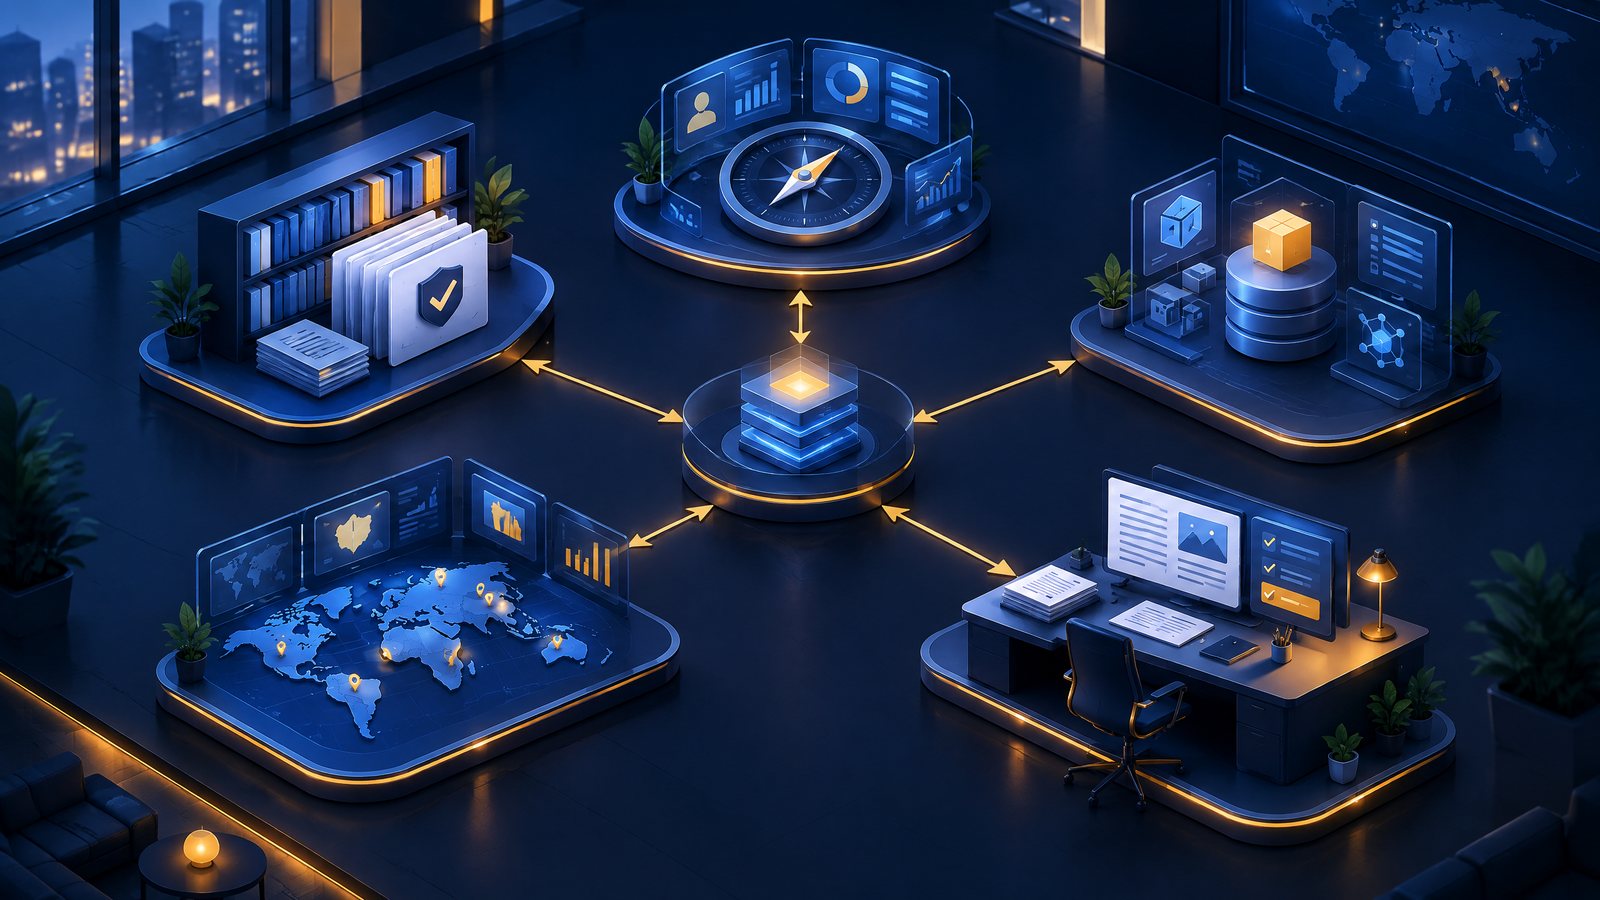
The framework has three layers: governed customer evidence with an owner, access rule, date, and use boundary; product truth, a versioned record of capabilities, exclusions, availability, proof, and approval owner; and dynamic market evidence, dated primary documentation and market-specific inputs. Give the agent only what is appropriate to the task and require it to identify uncertainty. The NIST Generative AI Profile, AI 600-1 is a useful reference: it focused on governance, content provenance, pre-deployment testing, and incident disclosure across the AI lifecycle.
Governed customer evidence is not a content quarry
Customer evidence is often the highest-value input because it reveals the language, constraints, and decision criteria a brand cannot learn from generic keyword tools. It is also where careless automation can create unacceptable exposure. Build an evidence register before connecting research material to an agent. For each item, record the source class, purpose, permitted audience, whether personal data is present, retention rule, market, date, and named business owner. Remove identifiers where the task does not require them, and do not place sensitive source material in a broadly accessible prompt library.
The UK Information Commissioner’s Office explains that its AI and data protection guidance is intended to help organizations apply UK GDPR principles to information used in AI systems, and it provides a risk toolkit for assessing effects on individuals’ rights and freedoms. Read the ICO AI and data protection guidance in its original scope with the relevant privacy team. This article is an operating framework, not data-protection, regulatory, or legal advice.
A useful control is an evidence card: a source reference, dated extract, permitted use, supported inference, confidence level, and approver. It can show that a recurring onboarding question warrants a tutorial without converting one customer’s comment into a universal product-performance claim.
Product truth must be more durable than a campaign brief
Campaign briefs change quickly. Product truth should not be treated as campaign copy. Create a versioned dossier with approved names, feature descriptions, availability, proof references, prohibited claims, known gaps, and review dates. This is the controlled source an evidence agent retrieves before a writer receives a brief.
The commercial benefit is disciplined disagreement. If product marketing, sales, support, and a regional team describe the offer differently, the system should surface that inconsistency for a human owner. It should not synthesize the most flattering version. For teams formalizing this layer, AI content operations [blocked] is the relevant service context: the work is organizational design, evidence flow, and editorial accountability, not prompt decoration.
A model-neutral instruction architecture
A durable workflow should outlast a particular model. The instruction architecture below is model-neutral because it describes roles, inputs, permitted tools, outputs, evidence rules, escalation conditions, and evaluation criteria. A platform can change without requiring the brand to abandon its standards.
| Layer | What it contains | What it must not decide alone |
|---|---|---|
| Mission | Audience need, business context, desired reader action, market | Whether a new claim is acceptable |
| Evidence | Approved customer evidence, product truth, market sources, dates | Whether sources are complete or current enough for publication |
| Role contract | Scope, tools, allowed repositories, output format, handoff target | Publication authority or exception approval |
| Constraints | Claim boundaries, privacy rules, locales, accessibility, prohibited language | Legal, safety, or compliance clearance |
| Evaluation | Evidence coverage, source fidelity, readability, localization checks, unresolved questions | A guarantee that the content will rank, be indexed, be cited, or produce commercial results |
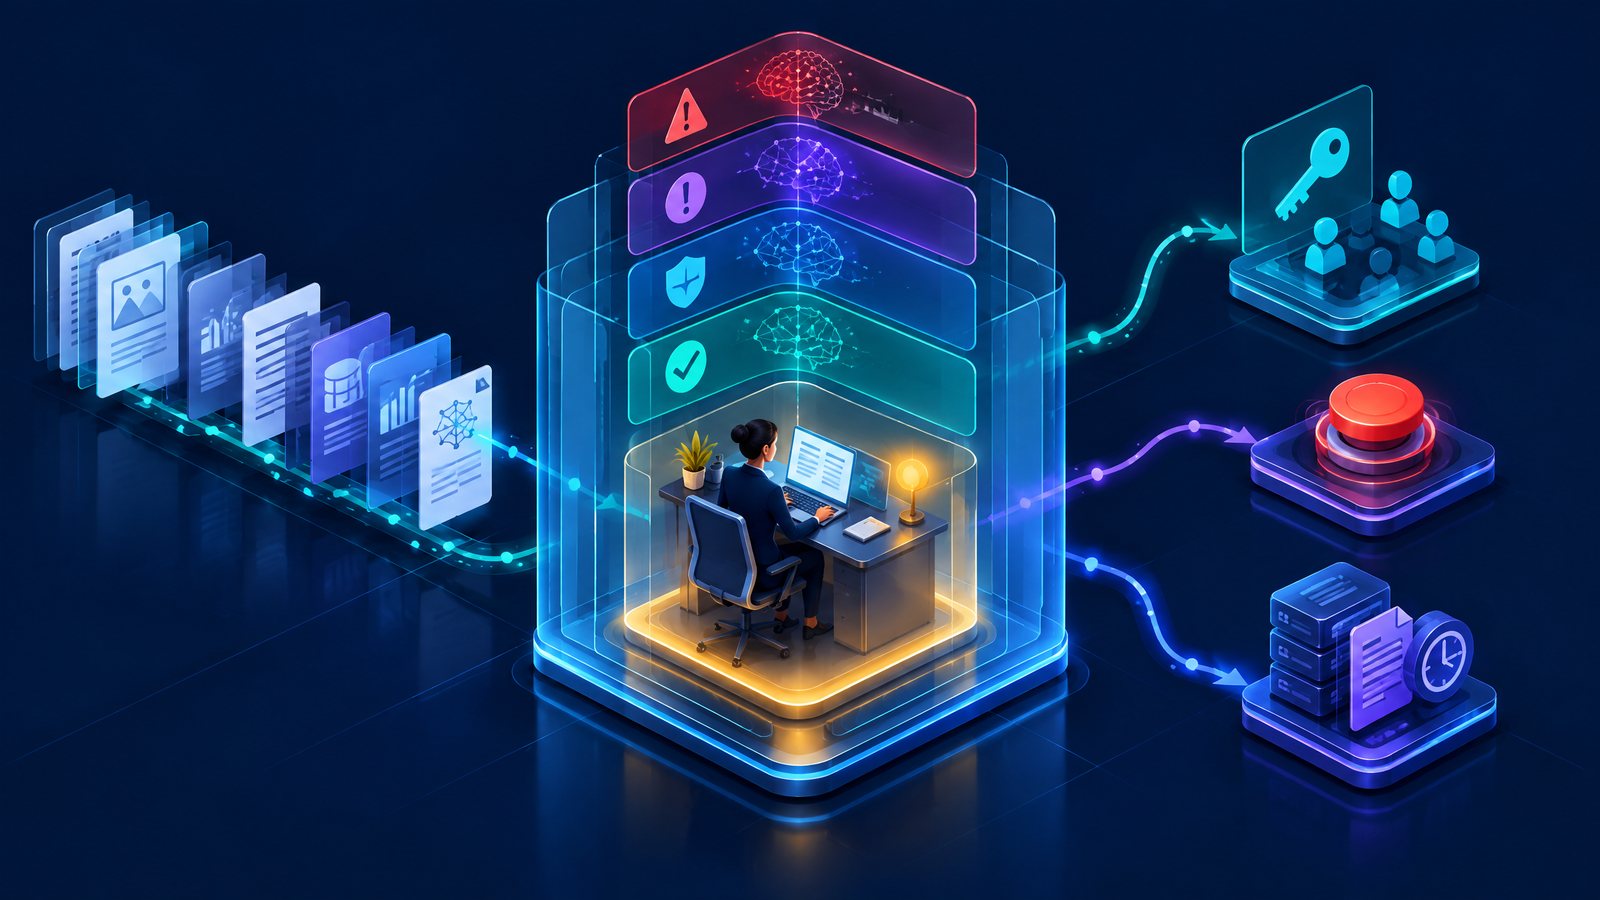
A role contract should ask an agent to return three things alongside its draft: the evidence used, the statements that need a person to verify, and the questions it could not answer. This avoids rewarding false certainty. It also creates a useful feedback loop: unresolved questions become research tickets, not polished omissions.
Do not build this architecture around supposed shortcuts for AI search. Google’s guidance for generative AI features says its generative features rely on core Search ranking and quality systems, and explicitly says there is no need for special AI markup or an llms.txt file for Google Search. The same guidance says indexing and serving are not guaranteed even where requirements and policies are met. Focus on helpful pages, crawlable technical foundations, and real reader needs rather than artificial rituals. For the technical work behind that foundation, see SEO, AEO, and GEO [blocked] and our related guide to AEO in 2026 [blocked].
The seven roles, and why a human remains in the loop
An agentic workflow does not need seven separate software agents. The roles can be performed by people, one model with distinct task contracts, or a combination. Separating them makes the handoffs inspectable.
1. Research role: find, label, and time-stamp
The research role collects primary sources, internal evidence cards, and clearly identified secondary context. It records publication date, market relevance, source type, access conditions, and what the source does and does not establish. Its output is a research pack, not prose for publication. A source that merely announces a capability cannot validate a quantified outcome claim.
2. Evidence role: test claim-to-source fit
The evidence role maps every material assertion to a source or flags it as interpretation, hypothesis, or open question. It checks whether a source supports the precise wording, not merely the topic. This role is where a customer quote may be anonymized, a market statistic may be narrowed to its method and geography, and a product statement may be sent back to its owner.
3. Persona role: turn evidence into a bounded reader model
The persona role turns evidence into a practical audience hypothesis: job context, desired progress, constraints, vocabulary, buying committee questions, and local context. It must not invent demographic certainty or pretend that a persona is a person. Customer research should guide the voice and problem framing, while the team remains alert to who is missing from the evidence.
4. Strategist role: choose the editorial job
The strategist selects the reader question, content format, source plan, internal destination, localization priority, and measurement hypothesis. This is a good place to connect editorial work to a broader AI marketing strategy [blocked], because the decision is about audience and business context before it is about channel output. A strategist can propose a test; it cannot claim future pipeline, revenue, or visibility from the proposal.
5. Writer role: draft from a defined evidence pack
The writer transforms the approved brief into clear copy, using direct answers, caveats, and source context where readers need it. Google says generative AI can be useful for researching a topic and adding structure to original content, but warns that generating many pages without user value may violate scaled content abuse policy. Its AI-generated content guidance also emphasizes accuracy, quality, relevance, and appropriate context about how content was created. The editorial objective is original utility, not volume.
6. SEO evaluation role: assess discoverability without making promises
The SEO evaluation role checks whether a page has a descriptive title, clear headings, human-readable structure, accessible assets, internal paths, and source context. It may examine Search Console data and technical errors. It must not promise a ranking, indexing, citation, or lead outcome. Google’s helpful, reliable, people-first guidance asks whether content provides original information or analysis, clear sourcing, and genuine value. It also explains that E-E-A-T itself is not a specific ranking factor; use it as a reader-trust lens, not as a ranking claim.
7. Human role: own the judgment and release decision
A named human reviewer accepts, revises, or rejects the work. Their checklist includes claim support, customer-data boundaries, product accuracy as approved by the product owner, market appropriateness, tone, accessibility, source currency, and publication destination. Higher-risk topics need specialized review. This is the core of AI governance [blocked]: assigning accountable decisions, maintaining an escalation path, and preserving a record of meaningful changes. For a companion perspective, read AI governance and quality control [blocked].
Global-to-local publishing: translate the decision, not just the words
Global content often fails locally because a shared draft is treated as universal truth. A global master should describe the central reader problem, approved product truth, source requirements, and non-negotiable brand boundaries. A local team should then assess whether the evidence, examples, offer availability, terminology, unit conventions, cultural assumptions, and calls to action make sense in its market.
Language and direction are technical as well as editorial requirements. The W3C advises authors to declare a page’s default language on the HTML element and to use an appropriate language attribute around content that changes language. It also notes that bidirectional text needs direction handling in addition to language markup. Review the W3C guidance on declaring language in HTML before treating a translated string as an internationalized page.
For a right-to-left locale, local review should consider reading order, interface direction, punctuation, numerals, imagery, form labels, and the placement of legal or commercial qualifiers. For any locale, ask whether a source is relevant to the country and whether the claim is still available in that market. A localizer should be able to reject or adapt the global premise, not merely edit sentence length. AI websites [blocked] and Gemini agentic AI [blocked] are useful implementation contexts when teams need to connect content operations, accessible interfaces, and bounded agent workflows.
Amazon UK resource: a checklist discipline for editorial gates
For teams designing human release gates, The Checklist Manifesto on Amazon UK is a defensible process-design resource. Its relevance here is not AI expertise; it is the practical discipline of making critical, repeatable checks visible when work becomes complex. As an Amazon Associate, Integrated.Social may earn from qualifying purchases.
How-to implementation: build a reviewable first pilot
Start with one topic, one market, and one content type. The aim is to expose the operating decisions before expanding scope, not to prove that automation can replace research or editorial judgment.
- Set the decision boundary. Define the reader problem, market, content type, business owner, and the decisions the workflow may support. State what it cannot decide, including publication approval and exceptions to claim or data rules.
- Build a permissioned evidence register. Inventory the customer, product, and market inputs that may be used. For each source, record owner, date, market, permitted purpose, handling rule, and the claim or question it can support.
- Publish a versioned product truth. Create a compact dossier of approved product language, availability, dependencies, evidence links, exclusions, and prohibited claims. Assign an owner and a review cadence for changes.
- Write role contracts and handoffs. Give research, evidence, persona, strategist, writer, and SEO evaluation tasks separate input and output contracts. Require each role to return sources used, uncertainty, and escalation questions.
- Run one global-to-local review. Have a local market owner evaluate the central premise, sources, terminology, availability, language, direction, and reader action. Record every localization decision as an adaptation, not a hidden rewrite.
- Measure the pilot against a prewritten hypothesis. Instrument observable events, record the baseline and implementation date, review qualitative reader feedback, and use a controlled test only when its design and volume are appropriate. Document what the data cannot show.
The steps are deliberately modest. A pilot that reveals conflicting product claims, missing source permission, or a localization gap has produced operational learning even if no draft is published.
Amazon UK resource: a systems view of model behavior and human controls
For leaders who want a broader discussion of why model behavior, incentives, and oversight matter, The Alignment Problem on Amazon UK is a relevant background resource. It does not provide a content-operations blueprint, but it can help a cross-functional group discuss why fluent outputs do not remove the need for human responsibility. As an Amazon Associate, Integrated.Social may earn from qualifying purchases.
Measurement boundaries: observe, attribute, and test without collapsing the categories
Content measurement is necessary, but it does not turn a framework into a proven outcome. Separate three questions:
- Observation: Did readers encounter and interact with a page or asset? Examples include a documented page view, source-link click, form start, or resource download.
- Attribution: Which recorded touchpoints received credit under a chosen analytics model? Attribution is a reporting rule, not proof that a touchpoint caused an outcome.
- Causality: Did an intervention change behavior compared with a credible counterfactual? This needs an experiment or another defensible causal design, and may not be feasible for every content program.
Google Analytics defines a key event as an event measuring an action that matters to business success. An event can be marked as a key event, and a Google Ads conversion can then be created from an Analytics key event where the accounts and use case support it. Review Google Analytics’ key event and conversion documentation before choosing names, values, and attribution settings. Do not label a scroll, a content click, or a form start as a sale or qualified lead unless the organization has a documented downstream definition and connection.
For paid distribution, Google Ads Conversion Lift describes a controlled experiment that compares people who see ads with a control group that does not. Google also states that Conversion Lift is not available to all accounts. Where it is available and suitable, it may help examine causal incremental conversions for a defined campaign. It cannot validate every editorial claim, and it should not be used to infer that a piece of content alone caused a future commercial result.
A minimum measurement card for each pilot should list the hypothesis, audience, market, observable events, source systems, baseline period, change date, attribution model, known blind spots, and review date. Add a qualitative review: what questions did readers ask, what did sales or support teams challenge, and which sources became stale? This is more useful than a dashboard that reports only an aggregate count.
Series navigation: From Prompt to Profit
This is Part 1 of the five-part series, From Prompt to Profit: The AI Content Operating System for Global Brands.
- Part 1: Customer research before prompts [blocked]
- Part 2: Human-in-the-loop AI content governance [blocked]
- Part 3: Technical SEO, AI search, and Search Console [blocked]
- Part 4: Voice, visual search, and agentic commerce [blocked]
- Part 5: Organic and paid agentic AI, CPA, and LTV [blocked]
Sources and methodology boundary
This article synthesizes the primary guidance linked below into a proposed operating framework for content teams. The sources supply context for specific governance, grounding, publishing, localization, and measurement practices; they do not verify every recommendation in this article or certify a particular implementation. Review their original methods, scope, eligibility criteria, and updates before making an operational decision.
- NIST AI 600-1: Generative AI Profile
- ICO: Artificial intelligence and data protection
- Google Cloud: Grounding overview
- Google Search Central: Creating helpful, reliable, people-first content
- Google Search Central: Using generative AI content
- Google Search Central: Generative AI features guidance
- W3C: Declaring language in HTML
- Google Analytics: Key events and conversions
- Google Ads: Conversion Lift
Modi Elnadi’s point of view
The strongest AI content systems I see are not the ones with the most elaborate prompts. They are the ones where a researcher can show the evidence, a product owner can correct the truth, a local marketer can challenge the premise, and an editor can decline to publish. The technology can make those handoffs faster and more legible. It cannot remove the brand’s responsibility for the choices it makes.
Treat this framework as a starting point for controlled learning. It does not guarantee ranking, indexing, citations, leads, revenue, reduced review time, safety, accuracy, compliance, or legal clearance. Results, risks, and appropriate controls depend on the organization, market, sources, systems, review design, and decisions made by accountable people.