AI agents can help qualify B2B inquiries by clarifying requirements, checking supplier fit and preparing a useful handoff. Whether they improve lead quality depends on the decisions they get right, the viable buyers they miss and what happens after contact. IndiaMART’s latest executive interview supplies a case for that measurement discipline, not independent proof of an AI revenue return.
In a November 2, 2026, CIO interview, IndiaMART CIO Nikhil Prabhakar describes AI-prioritized leads, suggested replies and voice-based qualification. He also distinguishes current assistance from a proposed next step: an agent replying on a seller’s behalf within seller-defined review limits. This is new reporting about existing deployments and their direction, not a newly announced launch. [1]
What IndiaMART reports, and what the numbers mean
Prabhakar says suggested replies and one-tap templates have boosted “buyer responsiveness by 3x.” Keep that description intact. The interview does not define responsiveness, disclose its baseline or observation period, identify the measured population, or publish a controlled evaluation. It does not establish threefold faster seller replies, threefold more orders or incremental profit. [1]
The inquiry figure needs equal care. CIO quotes “more than 29 million unique business enquiries a year.” IndiaMART’s official Q1 FY27 investor presentation separately reports 29 million for Q1 FY26 and 114 million for the full FY26 year. It defines uniqueness by buyer-day: a buyer posting on another day is counted again in the quarterly or yearly sum. These are not counts of distinct purchasing organizations across the entire period. [1] [2]
The interview’s annual wording is therefore not a reconciled current annual benchmark. Its “more than” phrasing is a lower bound, and the sources do not explain whether the scope differs. Do not silently change it to quarterly, or present it as a precise annual total. More recent corporate reporting gives 27 million unique business inquiries for Q2 FY27, the quarter ending September 30, 2026. None of these inquiry totals measures agent-generated demand. [3]
CIO also quotes VANI handling more than one lakh buyer calls, without a time period. One lakh means 100,000. The daily period comes from a separate June 17 company statement, which reports over 100,000 buyer-seller conversations every day. Attribute that volume to the dated statement rather than inserting “daily” into the November interview. It is a company-reported operating figure, not evidence of how many conversations became sales. [1] [4]
These boundaries leave a useful case: IndiaMART describes systems that collect requirements and support engagement. The commercial hypothesis is that better qualification can make the resulting connections more useful. Testing that hypothesis requires more than counting messages or calls.
Qualification should resolve the next decision
IndiaMART’s company-hosted June interview explains the inbound situation behind its voice workflow. When sellers miss buyer calls, calls can reach IndiaMART with product-viewing context already available. The system asks relevant questions about specifications, quantity, price and location. The company describes its question-generation and voice layers separately, and distinguishes seller verification from behavioral matching. This is corporate context, not independent validation of effectiveness. [5]
For a B2B team, the transferable idea is to resolve the uncertainty preventing a suitable handoff. Consider a hypothetical buyer asking for an industrial pump. Product category alone may be insufficient. The seller might need the application, operating conditions, quantity and delivery location before deciding whether it can help. The agent should identify which missing detail changes that decision, rather than run every buyer through a long questionnaire.
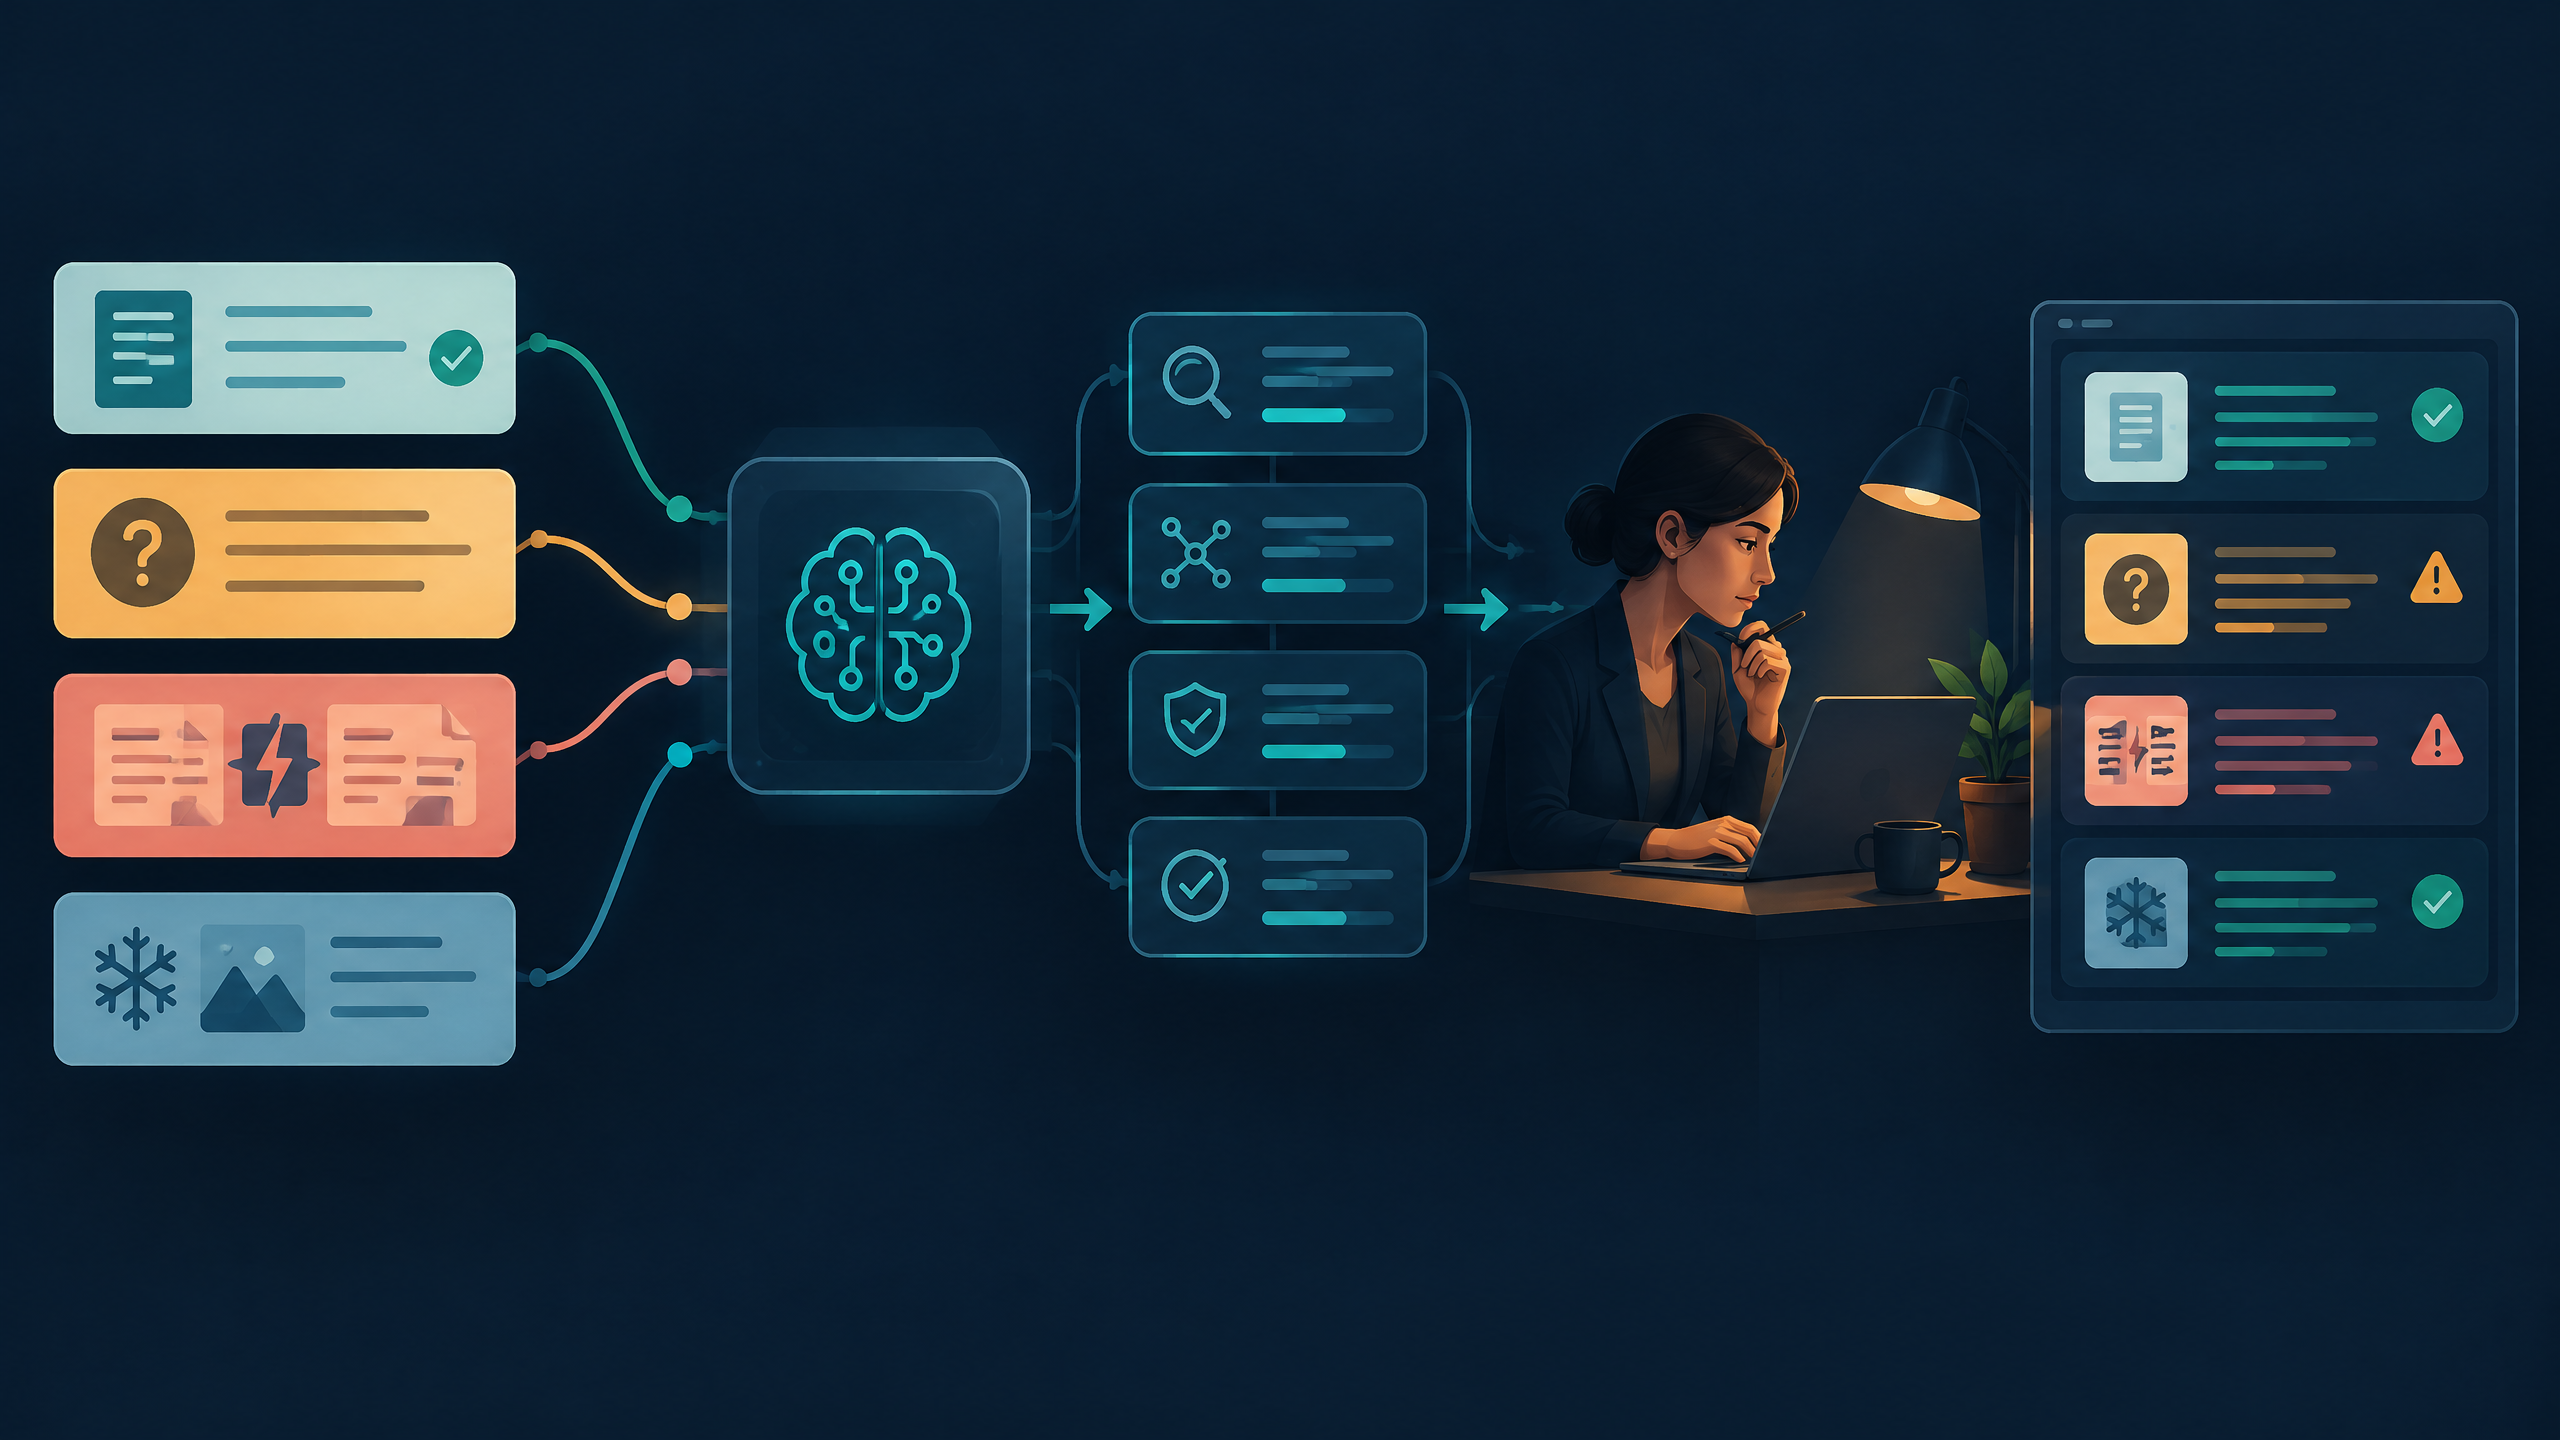
Our proposed qualification record has four checks:
- Requirement: What does the buyer need, and which essential specification remains unknown?
- Sourcing intent: What has the buyer explicitly said about the purchase, timing and next step?
- Supplier suitability: Which documented capabilities match the requirement, and what still needs confirmation?
- Handoff readiness: Can the receiving seller act on this record, or should a person resolve an exception?
These are editorial checks, not IndiaMART’s documented internal scoring system or measured results. Preserve the buyer’s answers and their source alongside any inference. A model-generated confidence score should not turn an unconfirmed requirement into a fact.
The existing governed lead-generation workflow covers research, drafting and outreach approval. This case asks a narrower question about inbound inquiries: does qualification produce an actionable supplier conversation without excluding suitable buyers?
Keep verification, fit and authority separate
A verified company may still be unsuitable for a particular order. A relevant product listing may omit a critical specification. An interested buyer may lack authority to approve a purchase. Prabhakar explicitly warns that confirming a business does not prove product quality and that an intent score is a signal rather than a verdict. [1]
Design the handoff so these distinctions remain visible. Record what was verified, which source supports it and what the verification covers. Keep supplier statements labeled as statements. Keep model inferences separate from both. A seller should be able to see “delivery capacity unconfirmed” without opening a transcript to discover why the agent recommended the match.
Permissions need the same specificity. Gathering a quantity requirement, suggesting a reply, issuing a quote and committing to delivery are different actions. A qualification agent should not gain commercial commitment rights because it collected the right fields. Requests for nonstandard terms, conflicting specifications or human assistance need a defined owner and escalation route.
Modi’s POV: the strongest qualification handoff gives the seller enough evidence to challenge the recommendation. An opaque “high intent” label transfers uncertainty to sales while making the automation dashboard look complete.
For teams defining these decision rights, agentic AI workflow support is relevant to task boundaries and handoffs. AI governance support addresses accountable review and permitted actions. Neither a framework nor a service engagement establishes that a workflow will improve revenue.
Measure accepted conversations and missed buyers
Start with the full eligible inbound cohort, not only the inquiries the agent successfully completed. Record the entry condition, channel, category and reporting period. Define how repeat buyers and repeat inquiries are handled. Otherwise changes in counting can look like changes in performance.
Then follow the decisions. How many inquiries reached a completed qualification record? How many proposed handoffs did sellers accept against written criteria? Why were others rejected? Separate missing specifications, unsuitable supply, wrong routing and buyers who were not ready. Report human corrections and escalation workload alongside completion rates.
Audit both error directions. Review accepted records to find unsuitable handoffs. Also sample records the system rejected, deferred or left incomplete to find viable buyers it missed. Reviewing only successful handoffs cannot reveal opportunities filtered out before a seller sees them. Report the sample sizes and uncertainty rather than presenting a small reviewed sample as marketplace-wide accuracy.
Responsiveness remains a useful intermediate measure if defined. For example, a team could measure whether a buyer replies within an agreed observation window after a relevant seller response. That is a proposed local definition, not an interpretation of IndiaMART’s undisclosed 3x metric. Keep automated sends, buyer replies, seller acceptance and orders as separate events.
Use the evaluation-set guide to test ambiguous requirements and exception routes before expansion. The decision-contract framework helps name the evidence standard and decision owner. Passing those tests supports a bounded deployment decision; it does not prove commercial lift.
Test commercial improvement against a credible comparison
Prabhakar notes that B2B deals often close off-platform and recommends controlled pilots and comparison groups. The interview does not publish such a study for the responsiveness claim. Treat that recommendation as a direction for measurement, not evidence that a causal test has already been completed. [1]
For a local pilot, define the primary outcome before starting. It might be seller-accepted conversations per eligible inquiry, accompanied by missed-buyer and complaint measures. Compare the assisted workflow with the current process over the same period. Where feasible, allocate comparable eligible traffic randomly and account for repeat buyers, shared sellers and contamination between groups. If random allocation is impractical, document how the groups differ and limit causal claims.
Keep product categories, language coverage, contact windows and available seller capacity visible. An apparent improvement could reflect a different inquiry mix or more available suppliers. Agree the observation window in advance so a short response measure is not compared with a long sales cycle.
Follow downstream outcomes only where records support the link. Separate confirmed orders from seller-reported outcomes, and retain unknown off-platform results as unknown. A missing order record is not automatically a failed sale. Conversely, an observed order after an AI-assisted conversation does not establish that the assistance caused it.
Include telephony, supplier fees, integration work, quality review, escalations and seller handling time when assessing operating cost. The free-to-use AI Token Calculator can estimate API token charges for a proposed text-processing step. It does not estimate the full cost of a voice-qualification system, provide free tokens or replace supplier billing.
Approve broader scope only when the pilot answers its stated question and the downside remains acceptable. Record who can pause the workflow, how rejected buyers can reach a person and which unresolved evidence prevents expansion. IndiaMART’s reported experience gives teams concrete questions to investigate; their own deployment decisions still require evidence from their own buyers, sellers and operating conditions.