OpenAI and Anthropic may be testing new models, but the latest clues do not establish public launches. As of November 3, 2026, the official sources reviewed do not announce GPT-6.2 Astra, Claude Fable 5.5, or Claude Mythos 5.5. TestingCatalog reports separate references with different evidence behind them. For businesses, the useful question is not which rumored model wins. It is what evidence would justify changing an existing workflow.
My position is straightforward: evaluate cost per successfully completed business task, subject to an agreed quality bar and human approval boundary. A benchmark improvement is a reason to investigate, not proof of better marketing performance. A lower token price is only one part of the calculation.
## What Do We Actually Know About the Reported New Models?The names need untangling before any comparison. TestingCatalog's November 2 Astra report describes gpt-6.2-astra in shared Codex usage screenshots. Its November 1 Anthropic report concerns a Mythos 5.5 website reference. Its separate October 17 report concerns rumored Fable 5.5 partner access. These are not interchangeable product announcements.
| Evidence level | What the source supports | Date and source |
|---|---|---|
| Confirmed | GPT-6 Astra is released; Fable 5.1 and restricted-access Mythos 5.1 are documented. | OpenAI: September 3 release entry; Anthropic: September 1 announcement entry. |
| Reported: Astra | A usage screenshot shows the identifier gpt-6.2-astra. Its public product status is not established. | TestingCatalog, November 2. |
| Reported: Mythos | TestingCatalog describes a hidden Mythos 5.5 reference; no new specifications are established. | TestingCatalog, November 1. |
| Reported: Fable | Partner-access claims and a subsequently removed third-party catalog entry do not prove a release. | TestingCatalog, October 17. |
| Speculative | Launch timing, joint releases, new prices, and business-performance improvements remain unconfirmed. | No supporting announcement found in the official sources reviewed November 3. |
The Astra report says the usage entry appears on October 31, while the picker still displays GPT-6 Astra. We inspected a linked public screenshot post showing the identifier, but did not authenticate the account or independently test the backend. A routing experiment is a possible explanation, not a confirmed release mechanism. Attractive demos cannot establish which model generated a particular result.
The Mythos report links a public screenshot post displaying “Claude Mythos 5.5.” That image is not an authenticated record of the underlying HTML. Our November 3 fetch of the official Mythos page still showed Mythos 5.1, and we did not reproduce the reported 5.5 string in that response. This limits what we can independently verify; it does not establish that the earlier observation was false.
The earlier Fable report also says a LiteLLM Azure entry was removed after Azure queries returned empty results. Its apparent specifications were largely carried over from Fable 5.1. Those figures should not become a Fable 5.5 price or context-window claim.
Evidence, not launch hype
Model Evidence Tracker
Read each reference with its evidence level. A reported identifier is not a confirmed public release.
Official announcement or documentation. Check exactly what it confirms.
Third-party observation or report, not an official launch announcement.
An unconfirmed interpretation, expectation or prediction.
2026-09-01
ConfirmedOfficial Mythos page dates its Mythos 5.1 announcement September 1; this is not a 5.5 announcement.
2026-09-03
ConfirmedOpenAI API changelog records GPT-6 Astra release; not GPT-6.2 Astra.
2026-10-17
ReportedTestingCatalog publishes separate Fable 5.5 partner-access rumor report; report date, not release date.
2026-11-01
ReportedTestingCatalog publishes Mythos 5.5 website-reference report; report date, not release date.
2026-11-02
ReportedTestingCatalog publishes GPT-6.2 Astra usage-identifier report; report date, not release date.
2026-11-03
ConfirmedEditorial source check: reviewed official sources do not announce these reported names; current Mythos response still identifies 5.1.
What the Official Sources Confirm Today
OpenAI's model catalog documents GPT-6 Astra alongside other released models, including GPT-6.1 Terra. Its API changelog and product release notes reviewed for this article do not announce GPT-6.2 Astra.
Anthropic's catalog already includes Claude Opus 5.5, Sonnet 5.5, and Haiku 5.5. Saying “Claude 5.5 has not launched” would therefore be misleading. The unresolved names are Fable 5.5 and Mythos 5.5. The release notes and announcements reviewed do not confirm those launches. Anthropic documents different safeguards and access arrangements for Fable 5.1 and Mythos 5.1; do not assume a future version will preserve them.
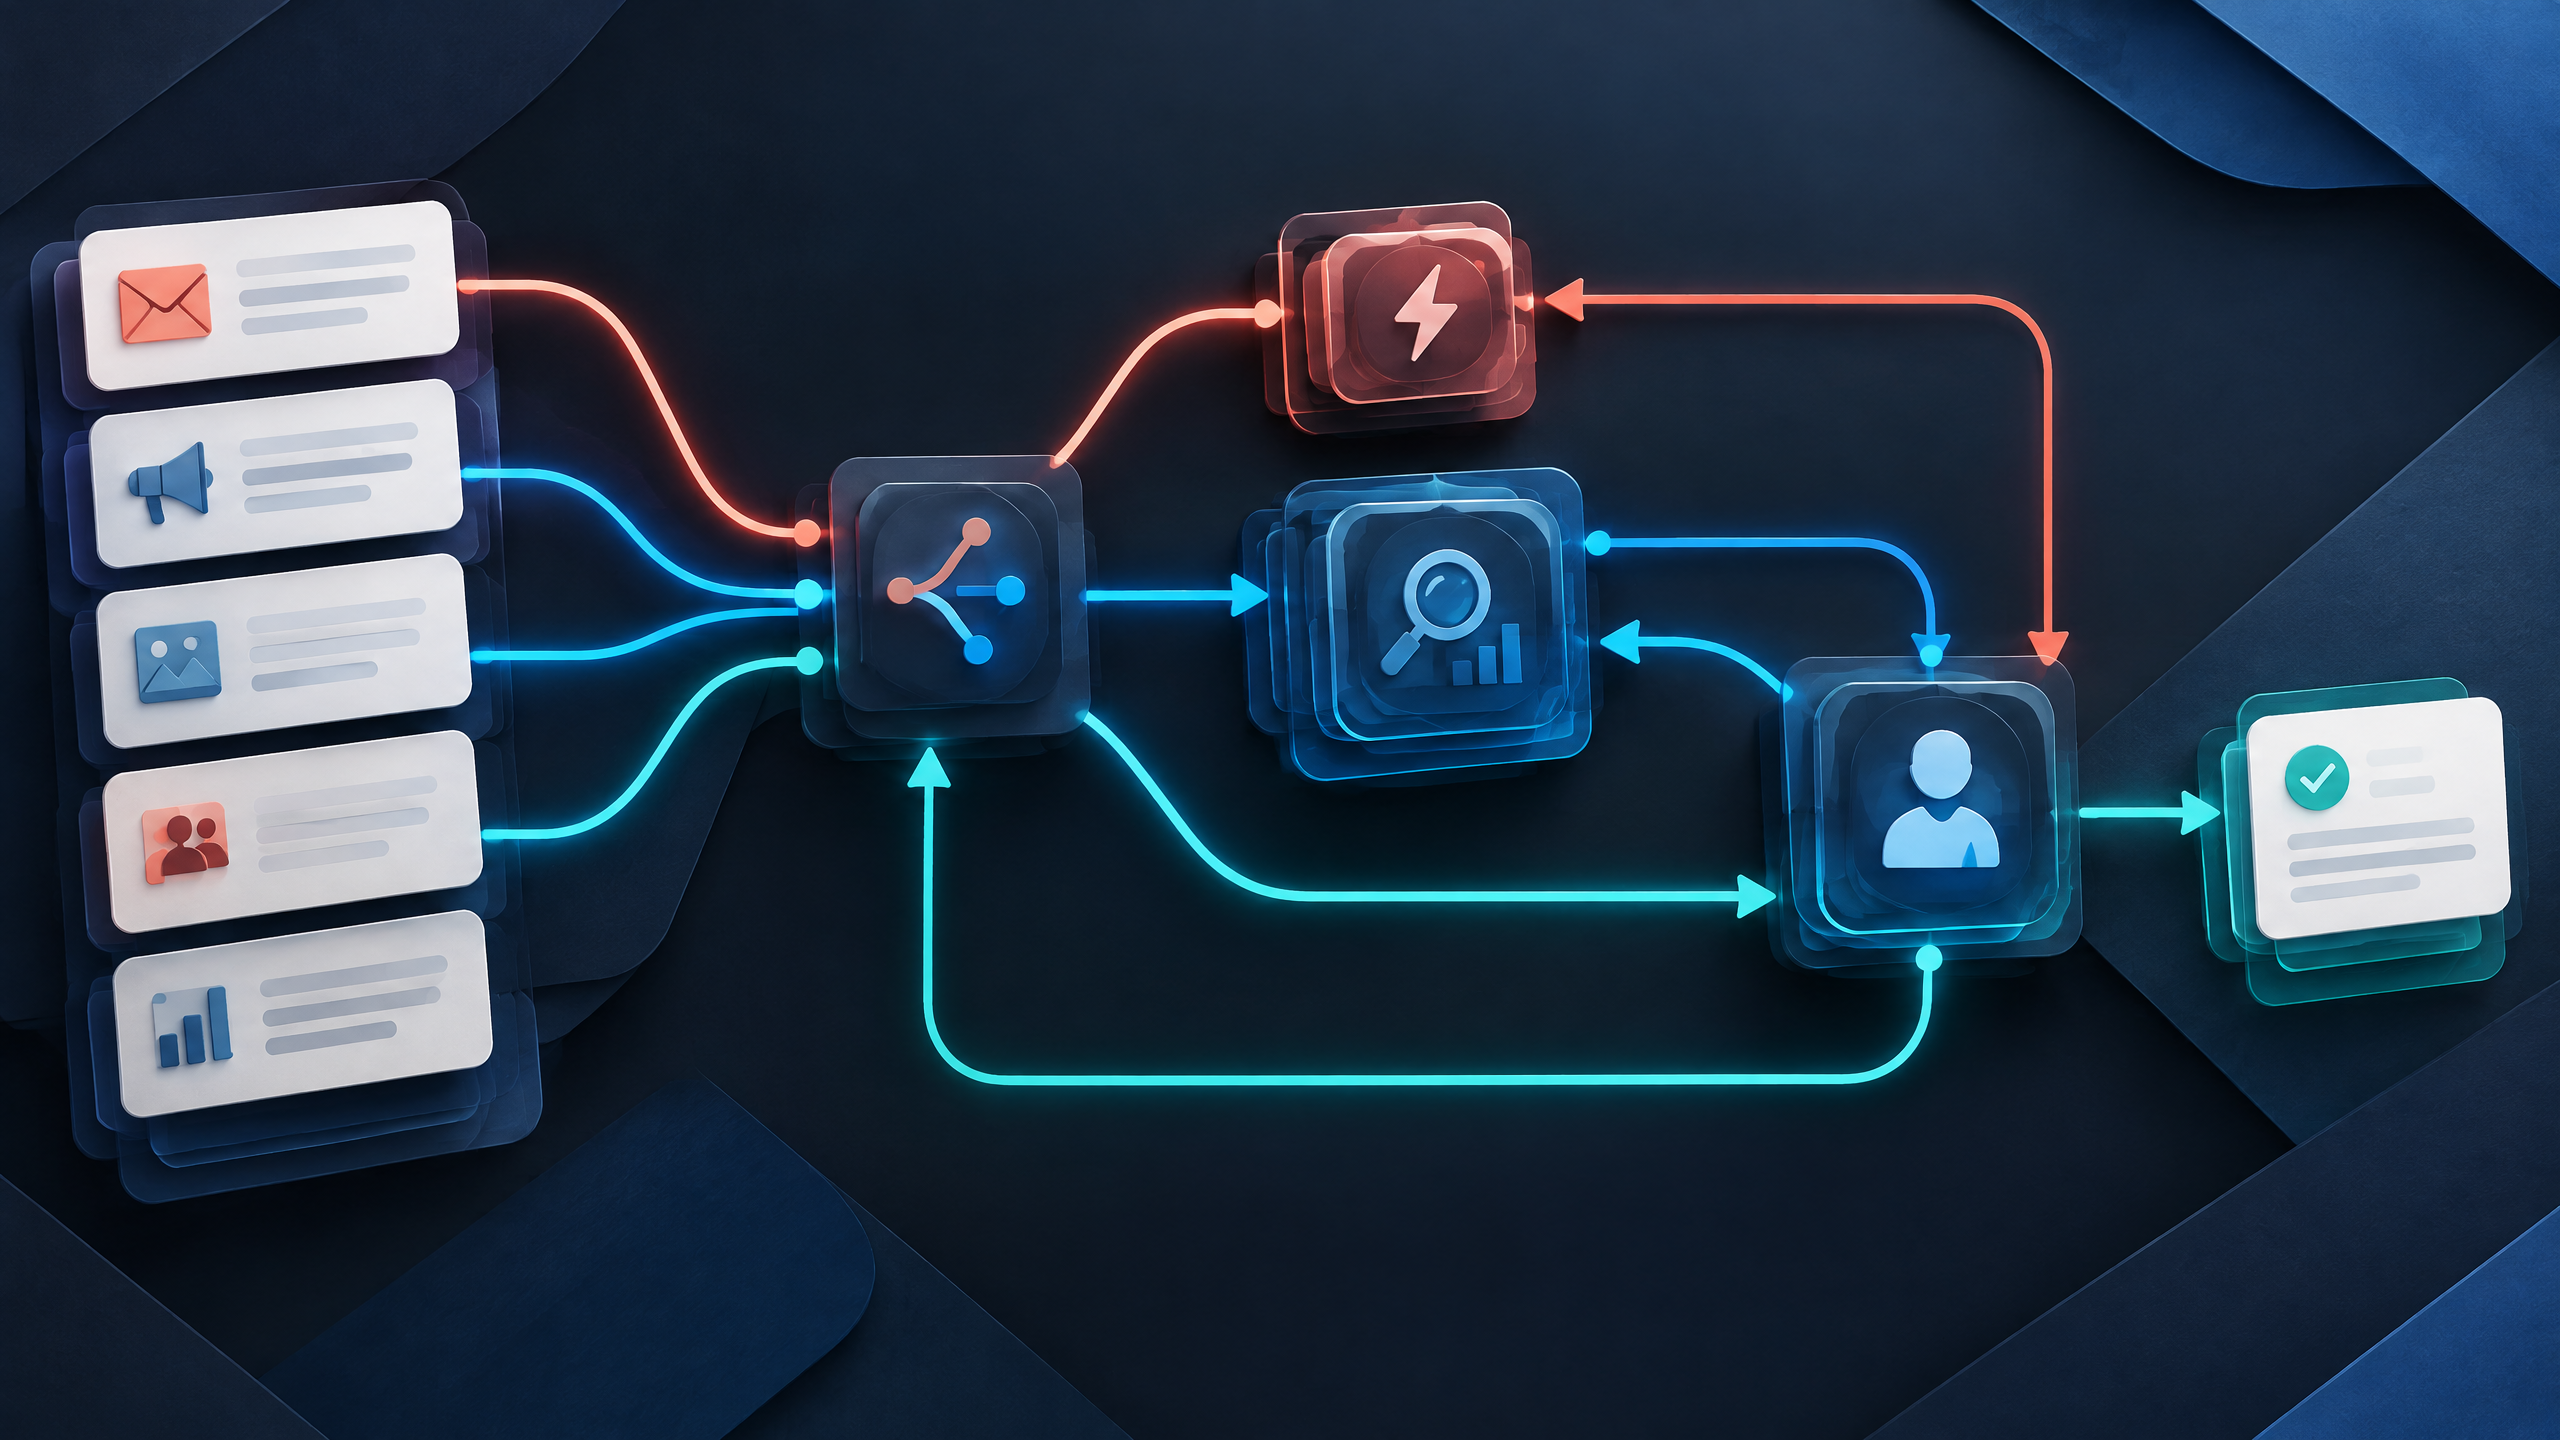
## Why the Next AI Model Race Matters to Businesses ### Reliability Matters More Than Benchmark HeadlinesA marketing workflow succeeds when its output meets a defined business requirement. A supplier comparison must preserve current evidence and exclusions. A campaign analysis must distinguish observed results from recommendations. A lead assessment must recognize missing information rather than invent buyer intent.
Evaluate unsupported assertions, tool failures, recovery behavior, and human intervention alongside task completion. Count work rejected at review as unsuccessful under the agreed definition, even when the model produced an impressive artifact. Use our model-routing acceptance criteria to decide which tasks need a stronger model and which need tighter controls.
### Cost per Successful Task Is More Important Than Token PriceToken prices describe a billing component, not a completed outcome. Record input and output usage, applicable reasoning charges, cache reads and writes, and any processing conditions using the supplier's actual rules. Then include repeated attempts, external tool fees, infrastructure, and human verification separately. A workflow that needs additional checking may cost more overall despite cheaper generation.
My proposed operating measure is total recorded workflow cost divided by outputs that pass the agreed acceptance and approval checks. Define the reporting period and success criteria first. If no output passes, report that failure rather than manufacture a favorable average. This is an editorial evaluation framework, not a claim about either reported model's economics.
### How Much Will Your AI Workflow Actually Cost?Before switching models, estimate the token costs of your existing workflow with our Calculate Your AI Token Costs Free. Compare supported input and output assumptions and projected workload volumes. It estimates model usage costs, not necessarily total workflow costs; retries, tool calls, human review, and infrastructure may need separate calculations. Do not use current-model rates as confirmed prices for an unannounced successor.
Carry those assumptions into the estimate-to-actual AI API budget worksheet before approving a pilot. Our Grok Bot costs and usage-limits guide applies the same discipline: separate documented charges from unknown costs instead of treating missing information as free usage.
Measure the whole workflow
The Real Cost of an AI Agent
A lower token price alone does not establish a lower cost per completed task.
Model usage
Record input, output and reasoning usage, with applicable caching and pricing.
Tool calls
Include paid APIs, retrieval and infrastructure used by the workflow.
Retries
Count failed attempts and rework; do not count the same usage twice.
Human verification
Include review time and corrections needed to accept the work.
Successful business outcome
Count only tasks that meet a predefined acceptance standard.
Cost per accepted task
Total workflow cost across all attempts ÷ number of accepted tasks in the same period.
Include failed attempts in the numerator. The denominator is accepted tasks, not tokens, tool calls or attempted tasks.
Zero accepted tasks: uncomputed. Do not divide by zero or report a zero cost per accepted task.
Agentic AI Needs Better Execution, Not Just Better Reasoning
A stronger model does not grant a workflow permission to spend, publish, or modify customer records. Keep tool permissions, logs, approval checkpoints, and recovery procedures explicit. Test whether the agent stops at a consequential boundary rather than simply whether it finishes more steps.
The maximum autonomous consequence framework asks what the system can change before a person intervenes. That question remains relevant after any model upgrade. Teams needing accountable handoffs can explore agentic AI workflow support; model selection and permission design are separate decisions.
What Could New Models Change for AI Search, AEO, and GEO?
Stronger models could interpret complex buyer questions, compare evidence across sources, and handle conversational follow-ups more effectively. They could also support agent-assisted purchasing. Those are plausible capabilities to test, not demonstrated effects of the rumored models. Answer engine optimization and generative engine optimization concern visibility in generated answers; a capability improvement does not automatically change citations or referral traffic.
Test whether a buyer-facing answer preserves product eligibility, distinguishes a brand's statements from independent evidence, and retains qualifications through follow-up questions. Measure mentions, citations, referrals, and qualified inquiries separately. None alone proves revenue impact. For source-qualified content and discovery work, see our SEO, AEO, and GEO services.
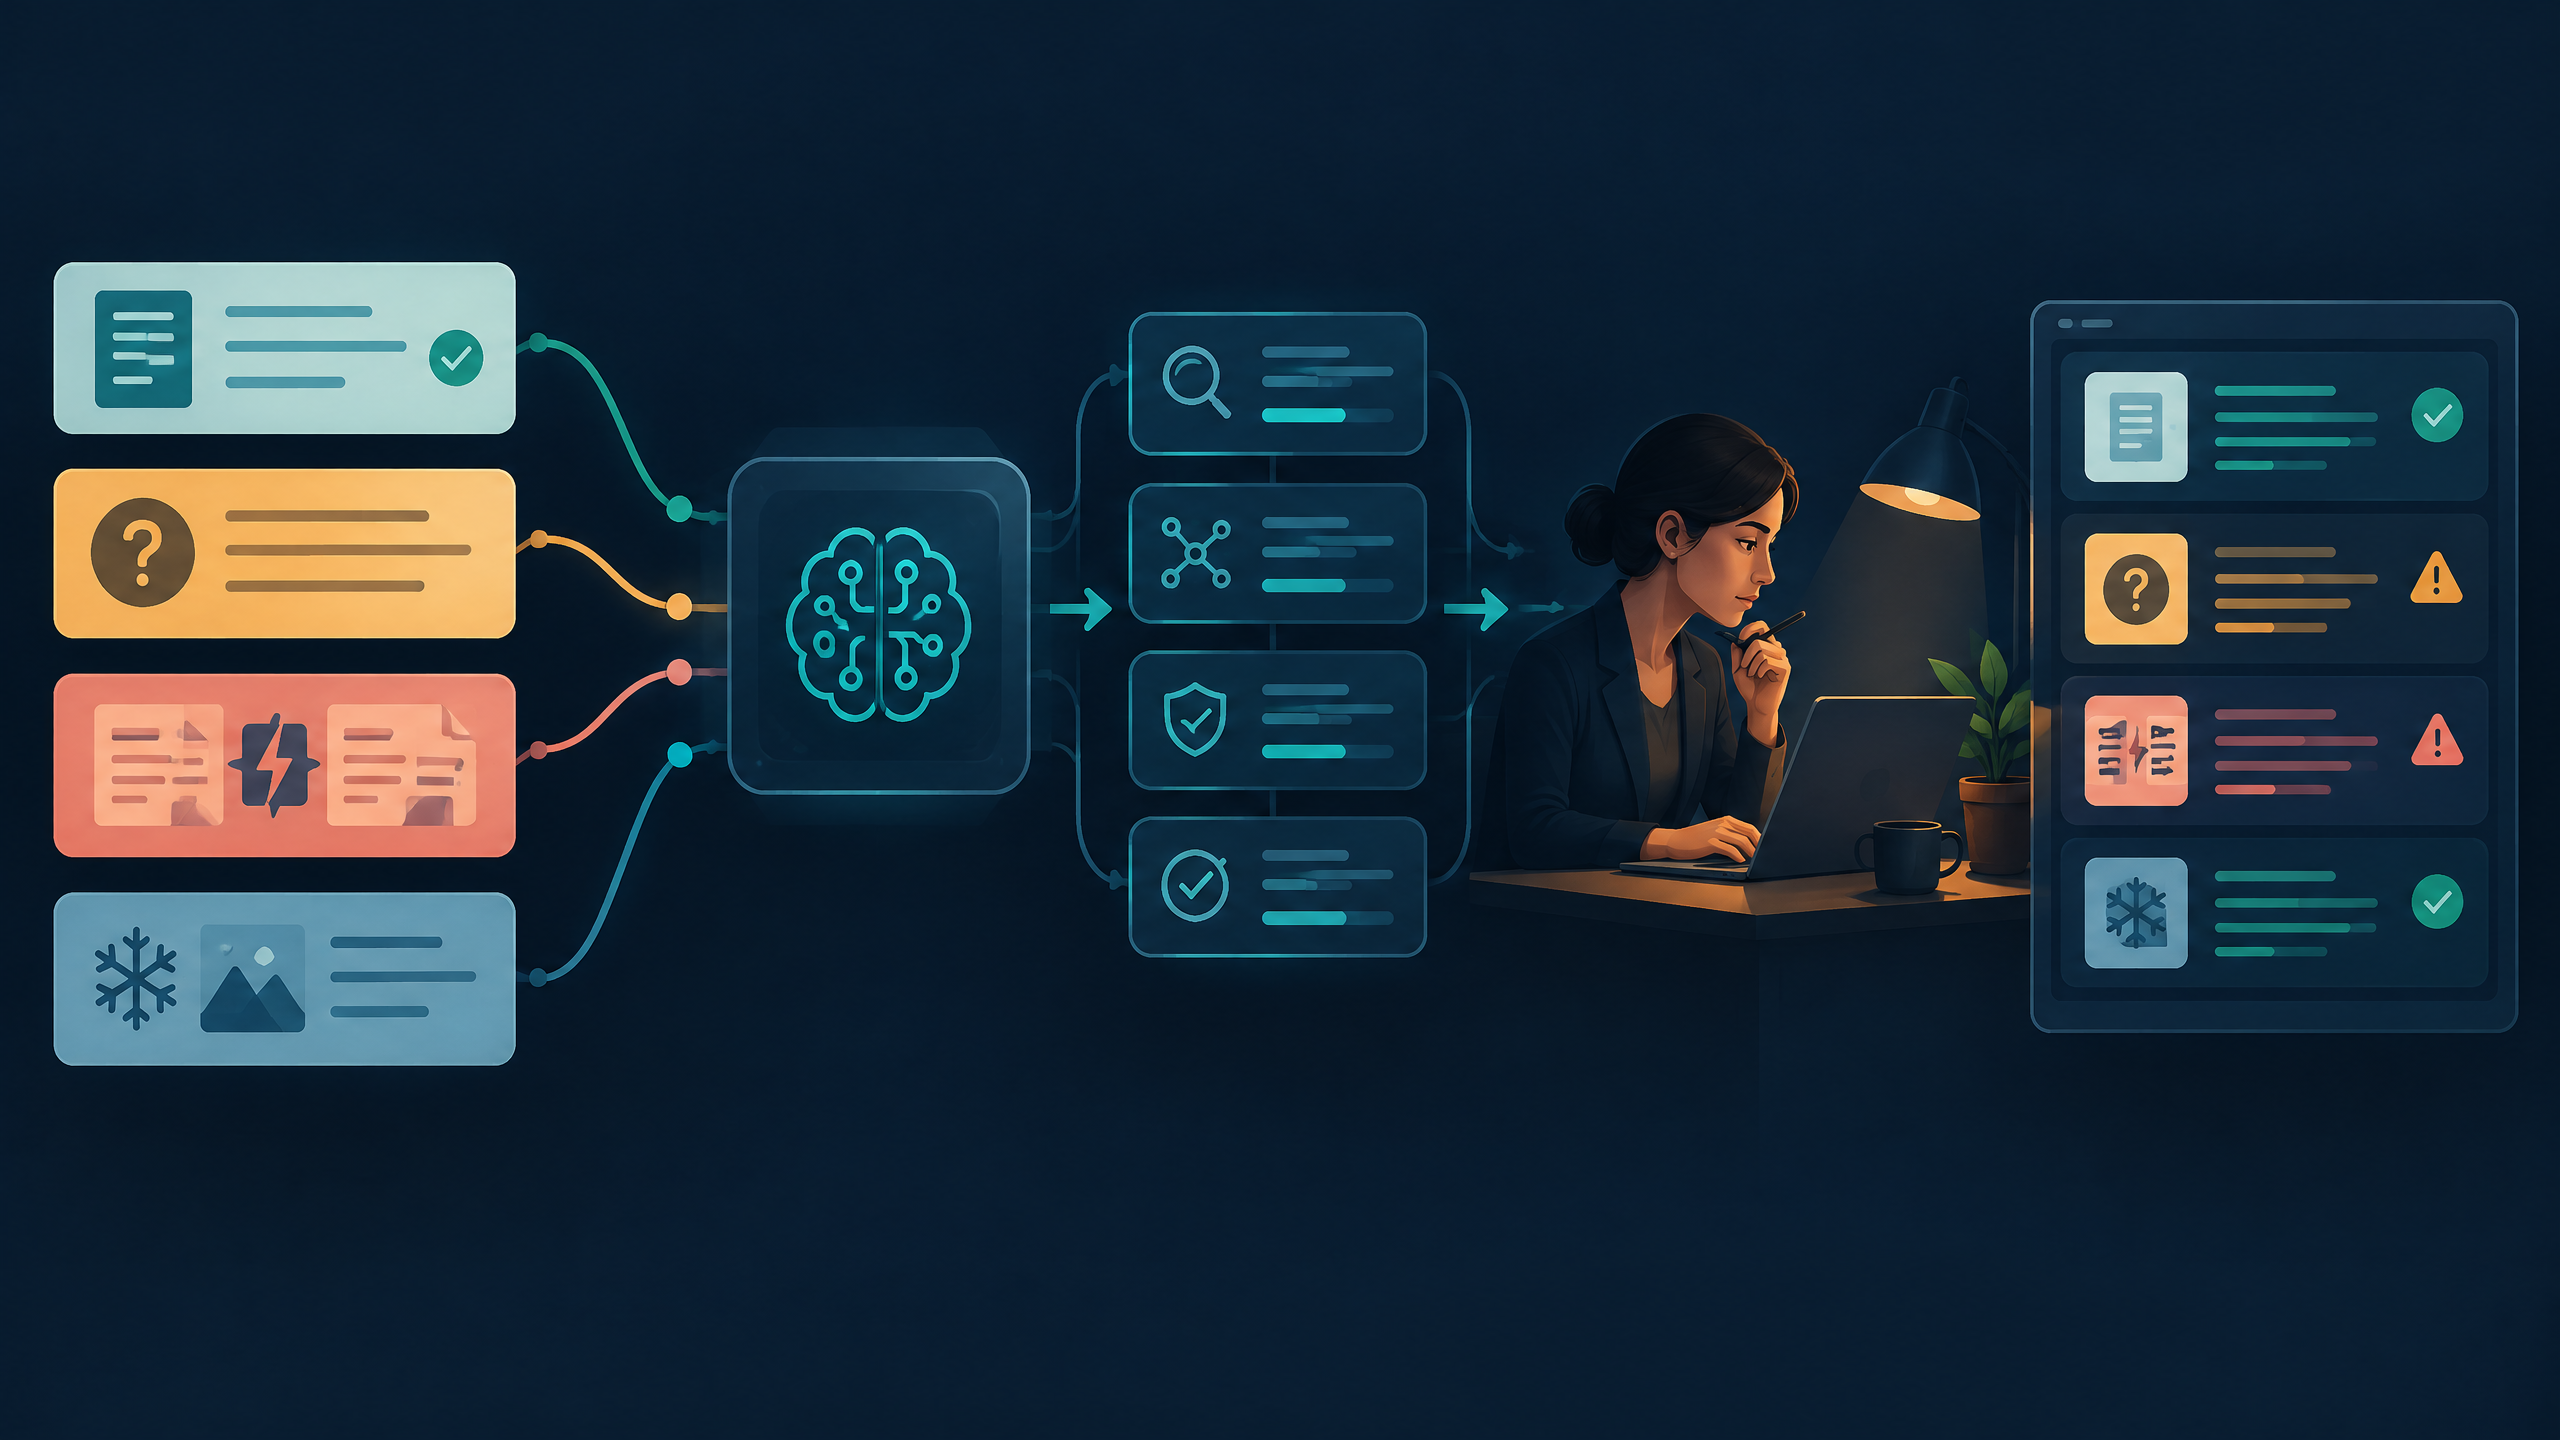
## What Should CMOs and GTM Leaders Test?Use these five editorial test categories on permitted, representative data. They are a proposed evaluation set, not comparative results. Keep prompts, retrieval sources, and approval rules stable enough to understand what changed.
- B2B buyer research: compare suppliers against stated requirements, checking every material claim and uncertainty.
- PPC analysis: analyze an approved campaign export, verifying arithmetic and separating diagnosis from an untested recommendation.
- SEO and AEO research: open cited sources, check dates, and test whether the draft preserves their actual meaning.
- CRM qualification: evaluate approved records against explicit criteria, including ambiguous intent and missing fields.
- End-to-end agent work: assemble a campaign proposal with tool-failure cases and a required human approval before consequential action.
Record accuracy, completion rate, latency, cost, human intervention, and repeat-run reliability. Track rework explicitly. Evaluate commercial impact separately through an appropriate business test rather than attributing a campaign result to a model change by assumption. Our marketing evaluation-set guide explains the next step without relying on a public leaderboard.
Agree on the decision before seeing the output. A research owner might require every material supplier claim to have an applicable source; a campaign owner might require recommendations to remain drafts until reviewed. Include cases where the right answer is to stop or request clarification. Otherwise, a system that guesses confidently can appear more productive than one that respects the boundary.
Keep a change record identifying the model, prompt, tools, and retrieval version used in each run. If several components change together, describe the result as a workflow comparison rather than attributing it solely to the model. Preserve a rollback route and name the person who can pause the pilot. Useful evidence should support a bounded next decision, not become a permanent permission to automate.
Evaluate before switching
AI Model Evaluation Scorecard
An unfilled assessment checklist for your own task set, not a vendor comparison or benchmark.
- Task accuracy
- Not tested
Check factual correctness and source support against a fixed rubric.
- Completion rate
- Not tested
Record accepted tasks out of all attempted tasks, including failures.
- Latency
- Not tested
Measure end-to-end time to an accepted result, including retries and review.
- Cost
- Not tested
Measure total workflow cost per accepted task over the same test period.
- Human intervention
- Not tested
Record reviewer time, corrections and approval steps required per task.
- Reliability
- Not tested
Repeat the same task set; record consistency, tool failures and error recovery.
GPT-6.2 Astra vs. Claude 5.5: What Can Be Compared Today?
For the reported names, evidence status can be compared. Product specifications cannot responsibly be filled in from their predecessors.
| Question | GPT-6.2 Astra | Fable 5.5 / Mythos 5.5 |
|---|---|---|
| Observed clue | Reported Codex usage identifier | Separate Fable partner rumors / Mythos website-reference report |
| Official public release | Not announced in sources reviewed | Not announced for these names in sources reviewed |
| Launch date and access | Not announced | Not announced |
| Pricing and context window | Not announced | Not announced |
| Comparative marketing results | Not independently verified | Not independently verified |
I don't think the next AI winner will necessarily be the company with the highest benchmark score. For enterprise adoption, the winner will be the model that businesses can trust to complete valuable work reliably, economically, and under appropriate human control. That is my commercial judgment, not a verified prediction about these candidates.
Keep the current workflow as a baseline, wait for documented access and specifications, then run a bounded comparison. Start with the AI Token Calculator's usage estimate and reconcile the broader costs against accepted work. If greater autonomy creates unresolved approval or data-handling questions, address them through AI governance support before expanding authority. Reported identifiers can prompt preparation; they cannot replace release evidence or your own acceptance decision.