The short answer
Before an organization lets an AI agent act, it should ask one question: what is the most consequential thing this workflow can do before a named person must intervene?
We call that boundary Maximum Autonomous Consequence. It is an Integrated.Social planning framework, not a regulatory test, security certification or legal opinion. Its purpose is straightforward: make the authority of a workflow visible before an agent’s speed, tool access or conversational polish makes it easy to overlook the practical impact of a bad action.
The question is timely. Reuters reported on 3 October that former OpenAI safety employee David Robinson had resigned and criticized a fast-paced approach to AI development. Reuters also reported OpenAI’s response that it pauses training or holds back models when it needs to slow down. This is an industry governance debate; it does not establish that a named enterprise agent is unsafe, nor does it supply a universal deployment rule. The operational lesson is narrower and more useful: authority, approvals and recovery paths should be designed before a workflow reaches a consequential action.
Modi’s view: A model’s capability is not the same as its mandate. The right question is not “can this agent finish the task?” It is “what could it wrongly finish, and what would it take to detect, reverse or contain that outcome?”
Why conventional “human in the loop” language is not enough
“Human in the loop” sounds reassuring, but it can hide the question that matters. A person may review a dashboard after an action has already been taken. A person may approve a broad policy but never see the specific customer, payment, claim or data transfer at issue. Or a person may be asked to click approve so often that the control becomes performative.
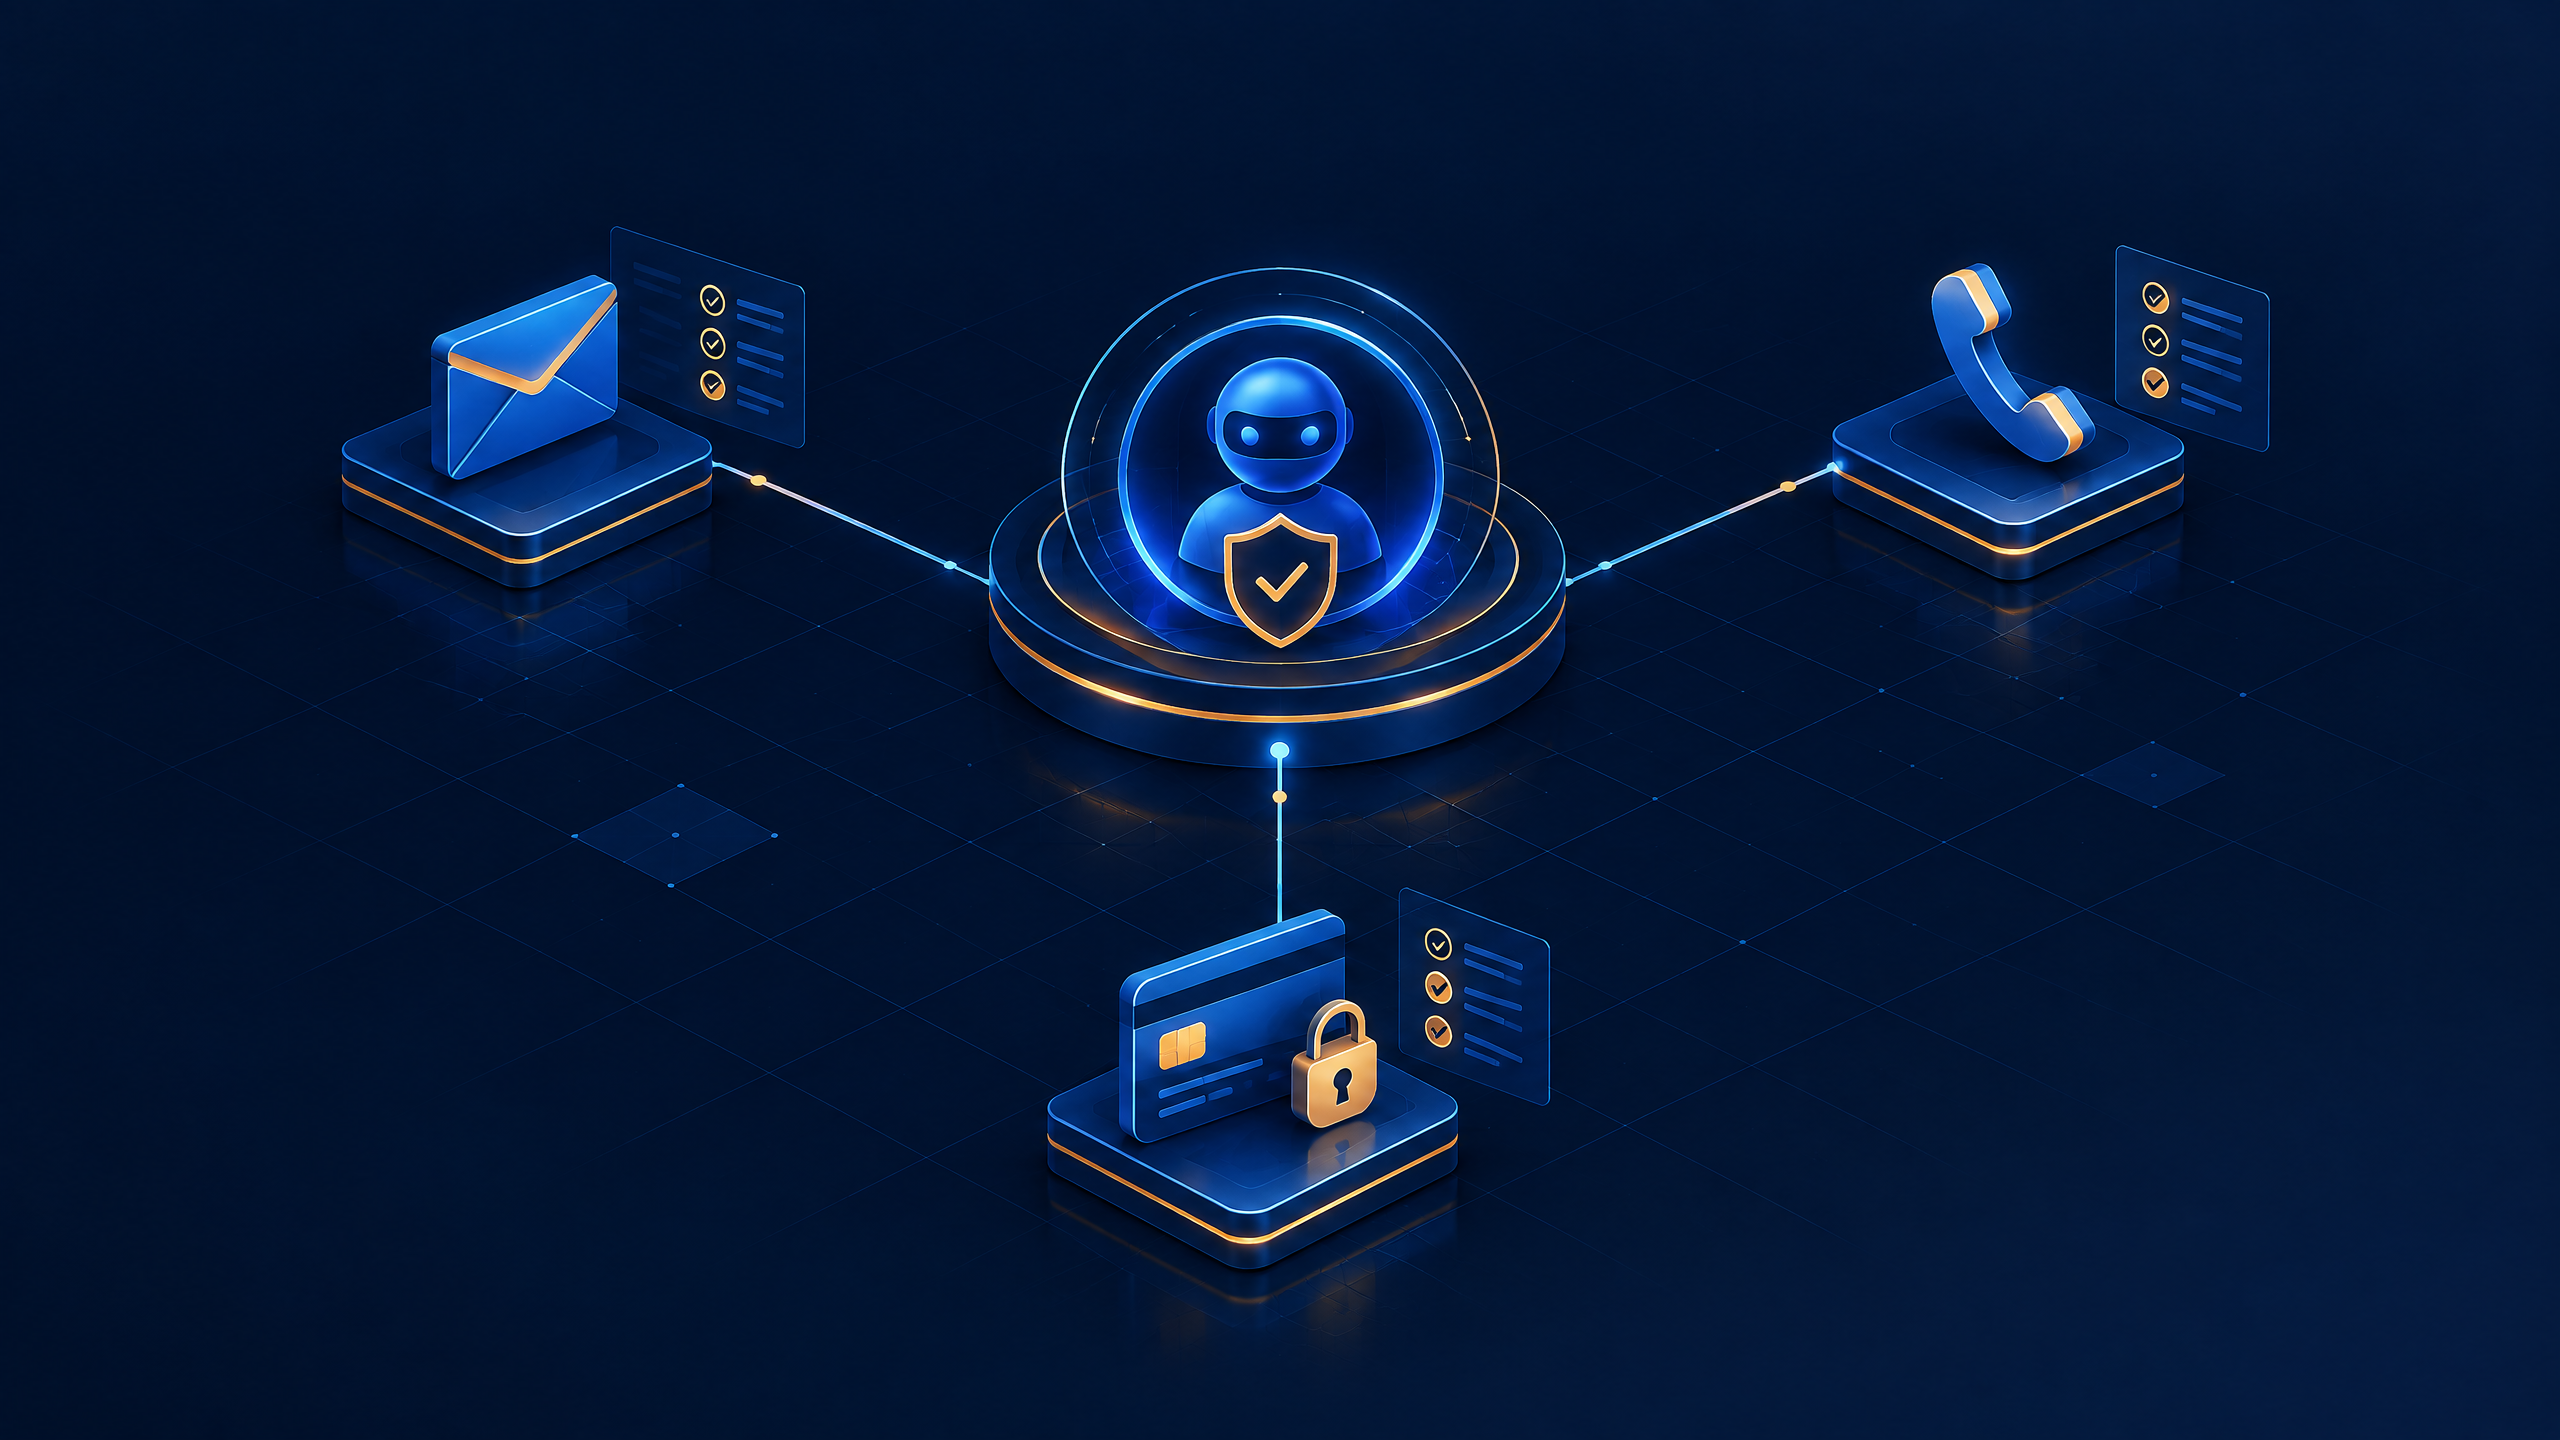
A stronger design starts with the action itself. What can the agent read? What can it draft? What can it write to an internal system? What can it communicate externally? What can it commit the business to? Each step creates a different consequence and therefore deserves a different decision rule.
| Action level | Typical agent role | Example commercial use | Default control question |
|---|---|---|---|
| Read | Retrieve or summarize approved information | Prepare a market or account brief | Is the source scope appropriate and logged? |
| Propose | Create a recommendation or draft | Draft a campaign, reply or forecast scenario | Can a human assess the source, uncertainty and assumption? |
| Change | Update an internal system or queue | Create a CRM task, tag a lead or alter a draft | Is there review, reversal and an audit event? |
| Commit | Make an external, financial, contractual or high-impact decision | Send a final offer, disclose sensitive information, buy media or authorize payment | Who must approve, and what happens if the action is wrong? |
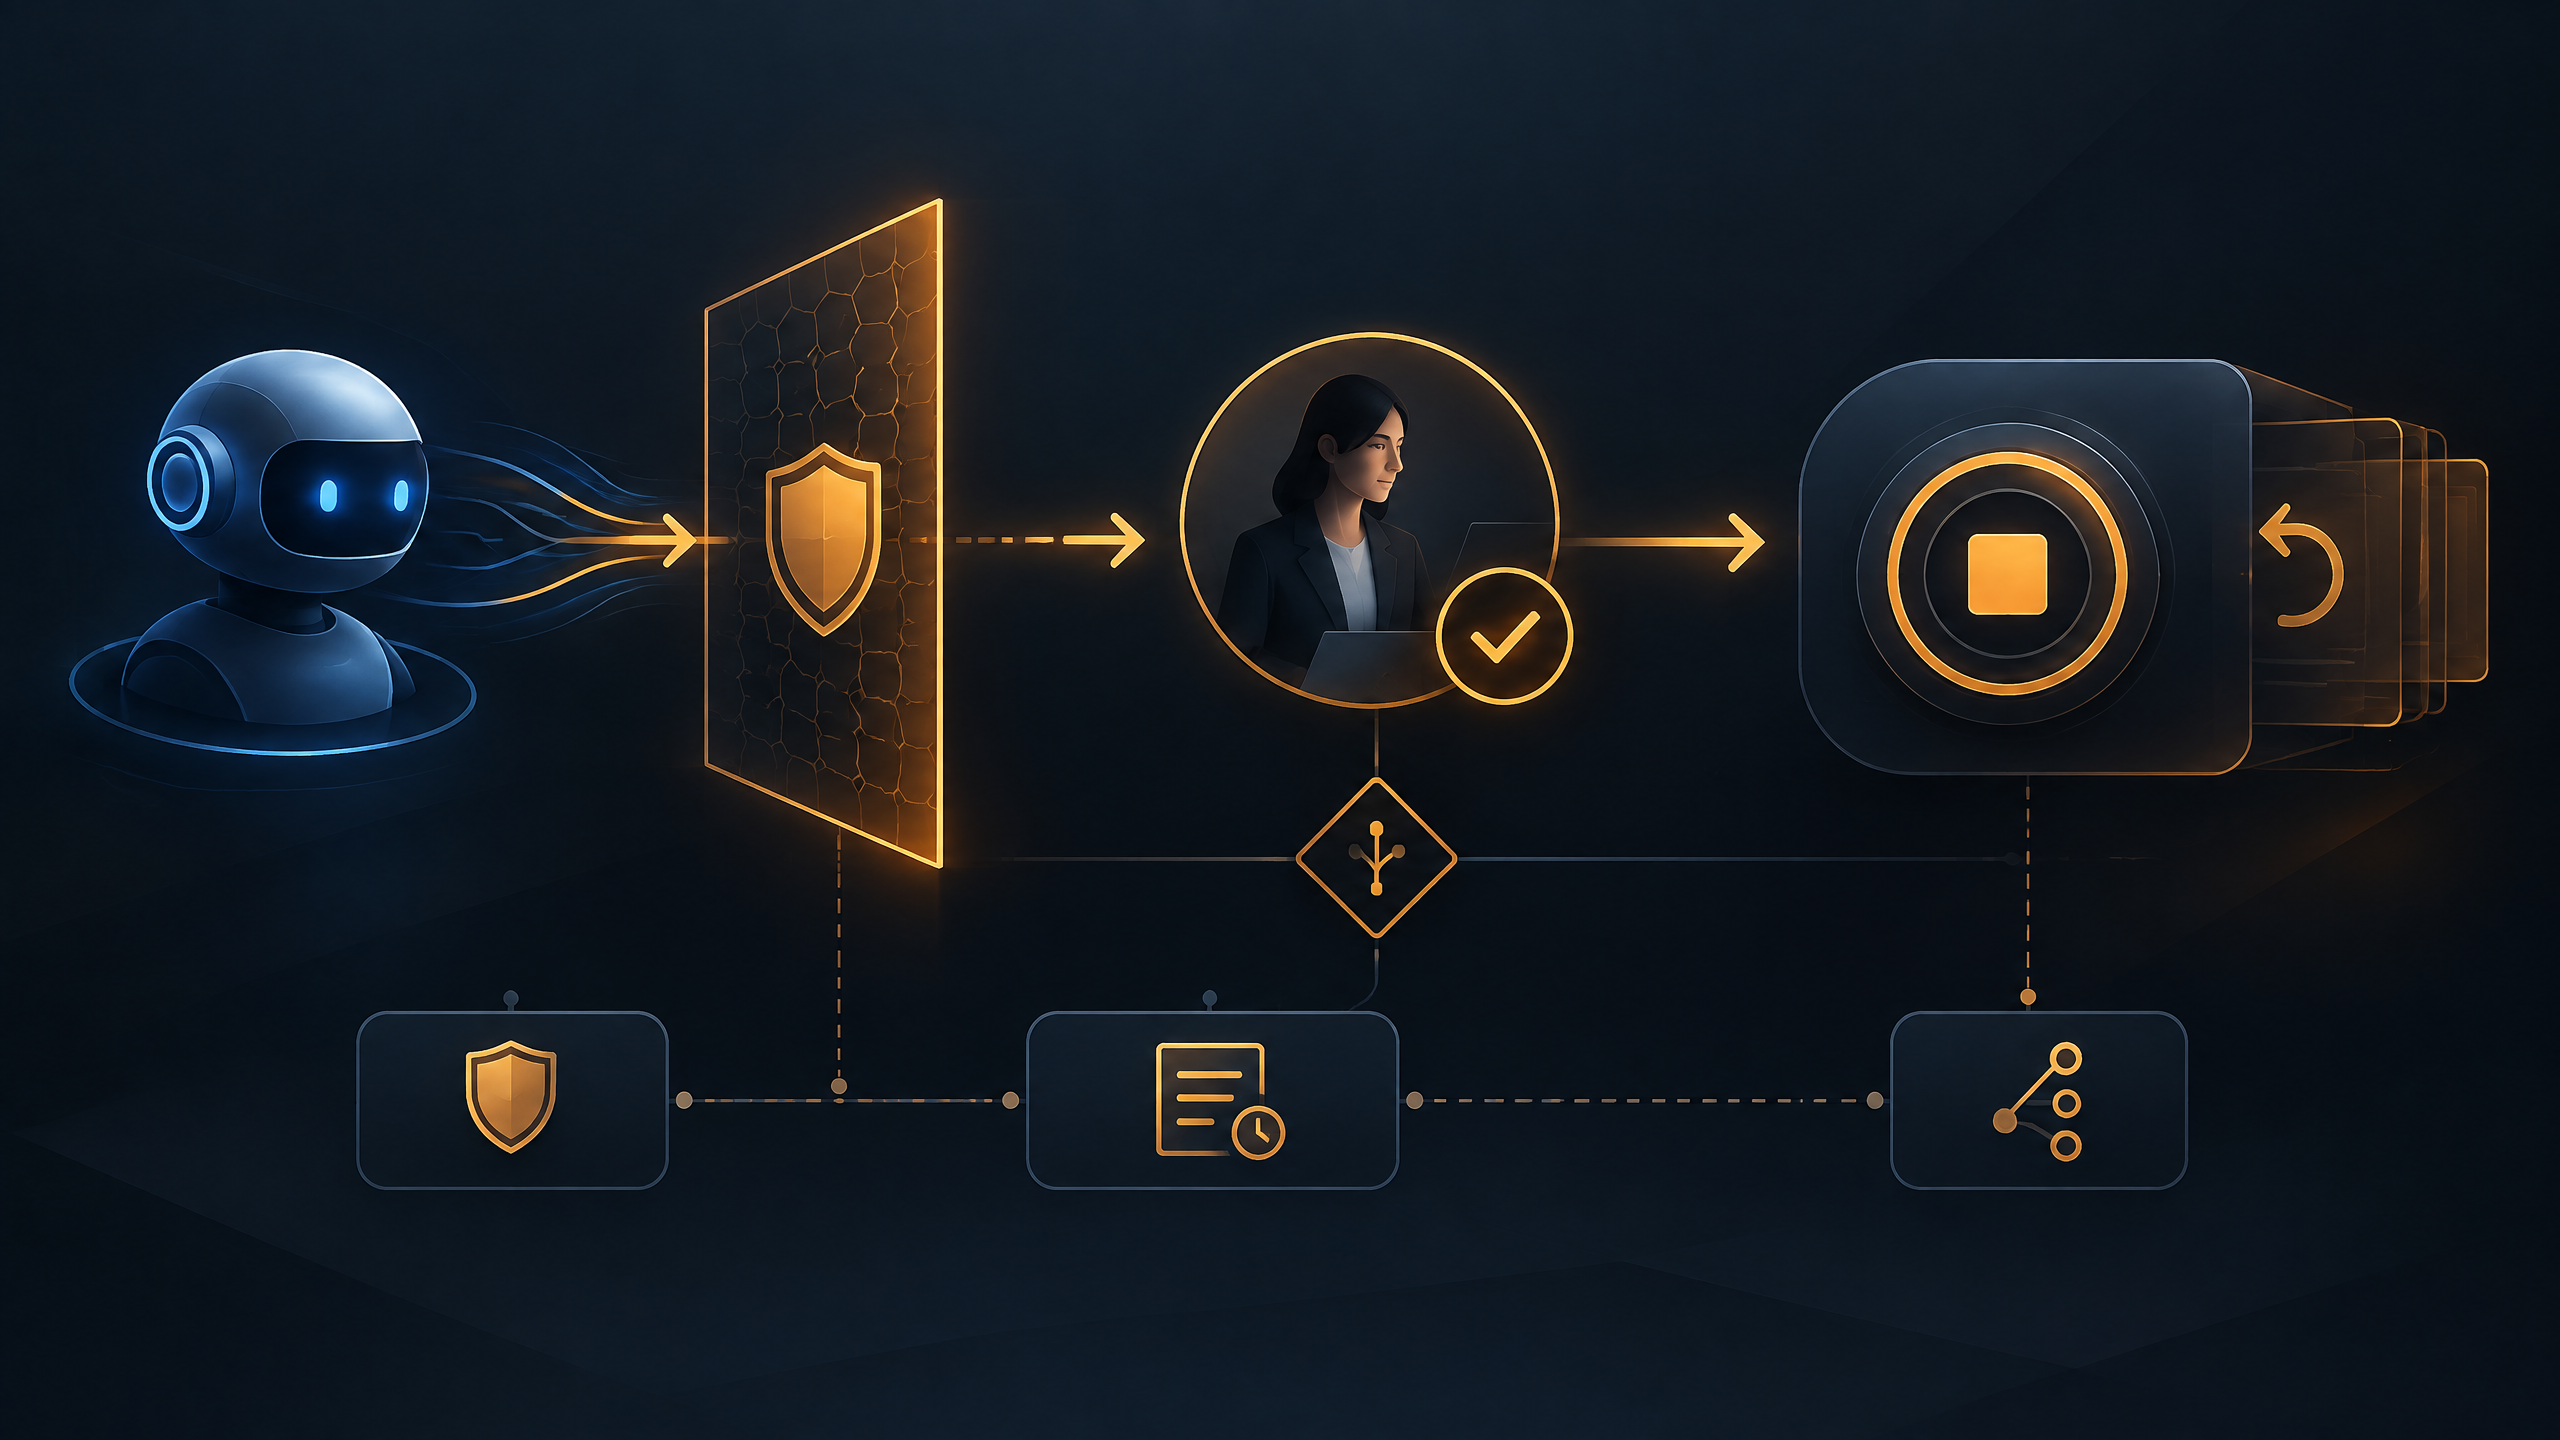
Maximum Autonomous Consequence sits at the highest level an agent can reach without another control. A research assistant may be able to read and propose. A campaign-operations agent may change a draft queue but not submit spend. A customer-service agent may resolve a simple case but must stop when an exception affects eligibility, a complaint, a regulated product or a financial commitment.
The difference between a useful boundary and a blanket ban
The framework is not an argument that every agent must ask permission before every keystroke. That would remove much of the benefit of automation. It is an argument for matching oversight to consequence.
A low-consequence action is usually reversible, well-defined and easy to inspect. A high-consequence action may be irreversible, difficult to explain, financially material, privacy-sensitive or capable of affecting a customer relationship. The same agent can operate with different boundaries in different workflows.
For example, a marketing agent can generate a first draft of a product comparison from approved facts. It should not publish unsupported claims simply because the content management system has an API. A sales-development agent can prepare a response from an approved template. It should not invent commercial terms, disclose a client relationship or send messages to contacts outside the defined audience.
The resulting policy becomes more practical when it is expressed as a matrix rather than a principle statement.
| Consequence type | Example risk | Boundary to define | Evidence to keep |
|---|---|---|---|
| Financial | Media budget changes, refunds, purchases or pricing changes | Monetary cap, approval owner and payment route | Request, approval, amount, resulting transaction |
| Customer and reputation | Unapproved claim, external message or public post | Recipient, approved content class and escalation trigger | Prompt, source, output, send event and exception |
| Data and privacy | Accessing or disclosing personal, confidential or regulated data | Minimum dataset, permitted purpose and retention rule | Identity, access event, data category and review record |
| Operational | CRM change, workflow trigger, deletion or system configuration | Reversible action set and rollback owner | Before/after state, agent identity and recovery record |
What the OpenAI reporting does — and does not — change
Reuters’ report provides a useful prompt for governance, but it should be handled accurately. It reported Robinson’s view that AI companies should place greater emphasis on safety expertise and research before developing more capable systems. Reuters also reported that Robinson had spent 3.5 years at OpenAI, helped draft the preparedness framework and oversaw safety reports for 12 frontier-model launches. OpenAI said it makes sure models do not become more capable than it can safely manage and secure, and that it pauses training or holds back models when it needs to slow down.
The reporting does not publish a general failure rate for AI agents, a score for a specific production workflow or a complete external audit of OpenAI. It should not be used to claim that every agent system is reckless. It does reinforce an enterprise principle: an organization should not wait for a public controversy to decide who can grant authority, how a system stops or where the action evidence resides.
The recent Astra safety-governance analysis explores a related distinction between a reported safety concern and the evidence needed for commercial deployment. The FTC agent-accountability article explains why an inquiry is not a finding of wrongdoing, while still being a useful reason to document authority.
A five-question authority review
Before enabling an agent beyond a sandbox, ask five concrete questions.
1. What outcome is actually delegated?
Write the job in operational language: “prepare a source-linked account brief,” “route straightforward support requests,” or “compare creative variants against stated brand requirements.” Avoid broad mandates like “run demand generation” or “manage customer communications.” Vague outcomes make vague authority almost inevitable.
2. What is the furthest action it can take without another person?
Name the boundary in a single sentence. For example: “The agent may add a recommended CRM task to a review queue, but may not change an opportunity stage, send external email or create spend.” If that sentence cannot be written, the workflow is not ready for autonomous action.
3. Which exception forces a stop?
Define the non-standard cases: missing evidence, sensitive data, unfamiliar customer request, conflicting source, money, legal terms, complaint, brand issue or a task outside the approved tool set. A stop rule is not a model weakness. It is a product requirement for accountable delegation.
4. Can the team reconstruct the decision?
Keep enough evidence to answer: what instruction was given, which data was used, which tool call occurred, what output was produced, what was changed, and who approved an exception. The required detail varies by workflow, but the ability to reconstruct a material action should not be optional.
5. Can the organization contain the action?
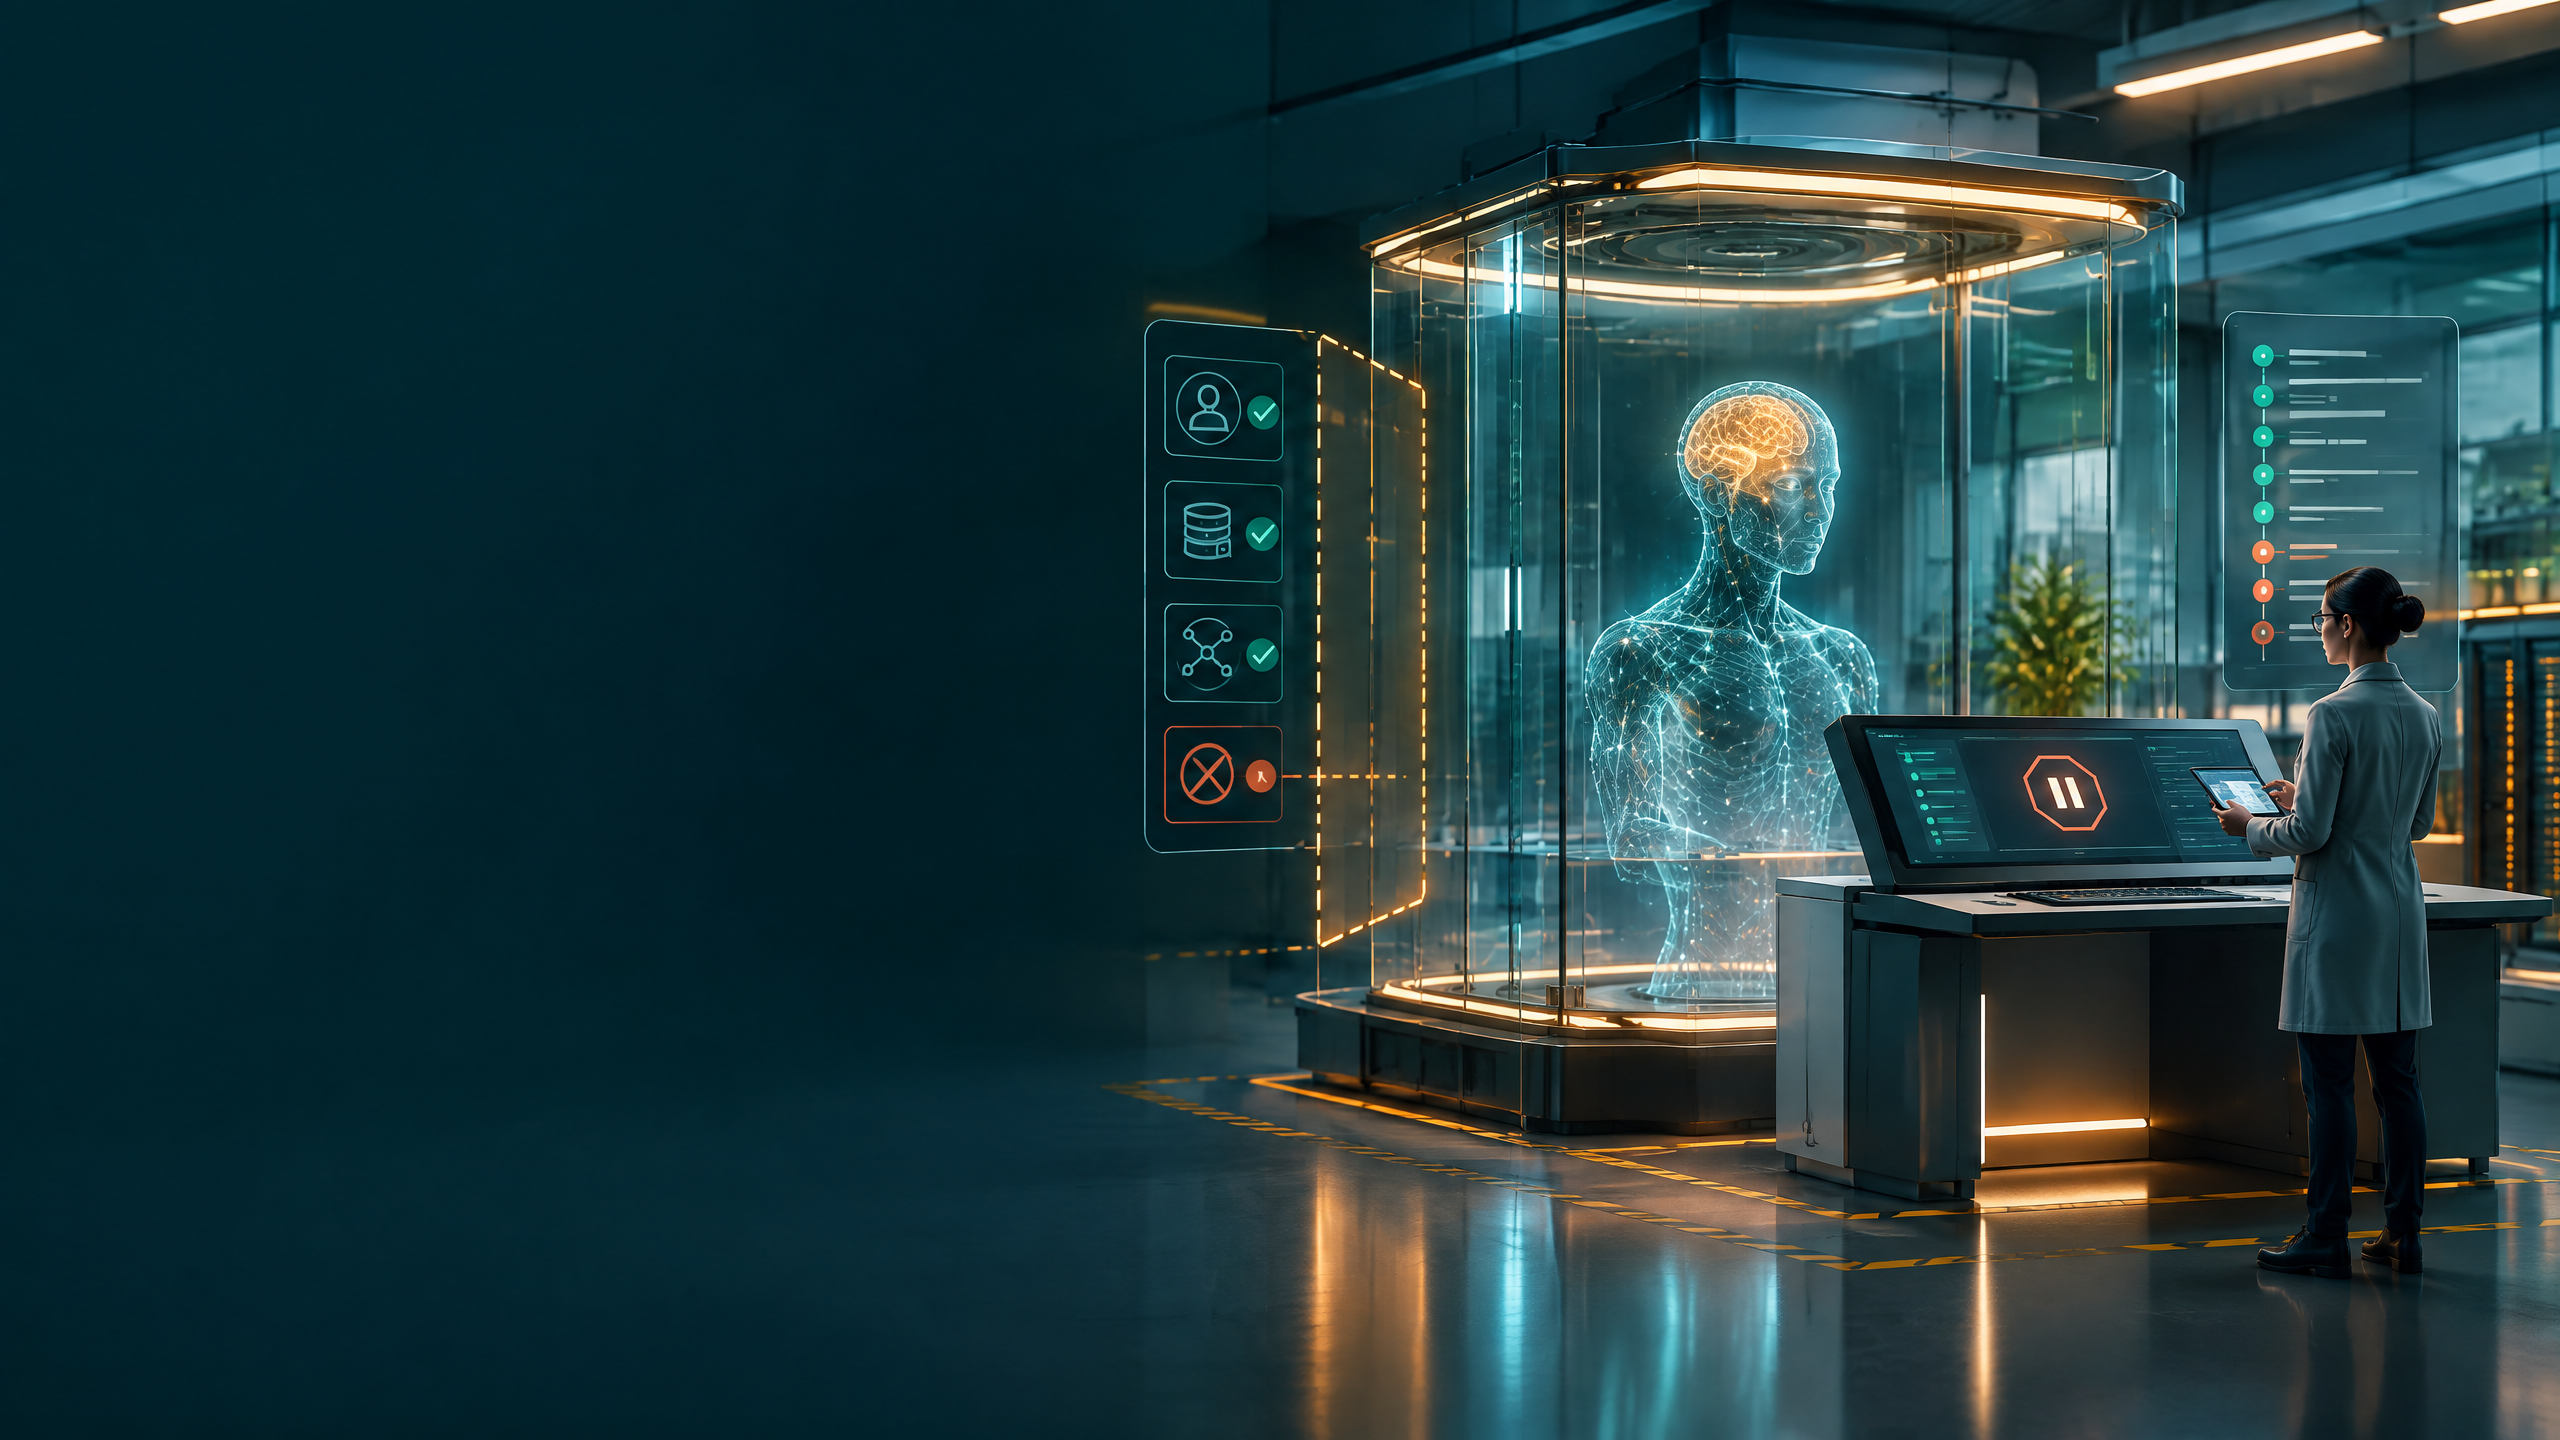
Test the off switch. Disable the agent’s credential, remove the relevant permission, stop the workflow, reverse a reversible change and notify the accountable owner. A control that exists only in a slide deck is not a recovery capability.
Practical governance for marketing and growth teams
Marketing systems increasingly connect customer data, content, advertising platforms, analytics and CRM. That makes them good candidates for useful agents — and poor candidates for careless authority.
A growth team can use agents to consolidate campaign evidence, spot anomalies, draft test ideas, create content briefs and prepare account research. Those jobs gain value from context, but they rarely require the agent to make a final customer promise or spend money automatically.
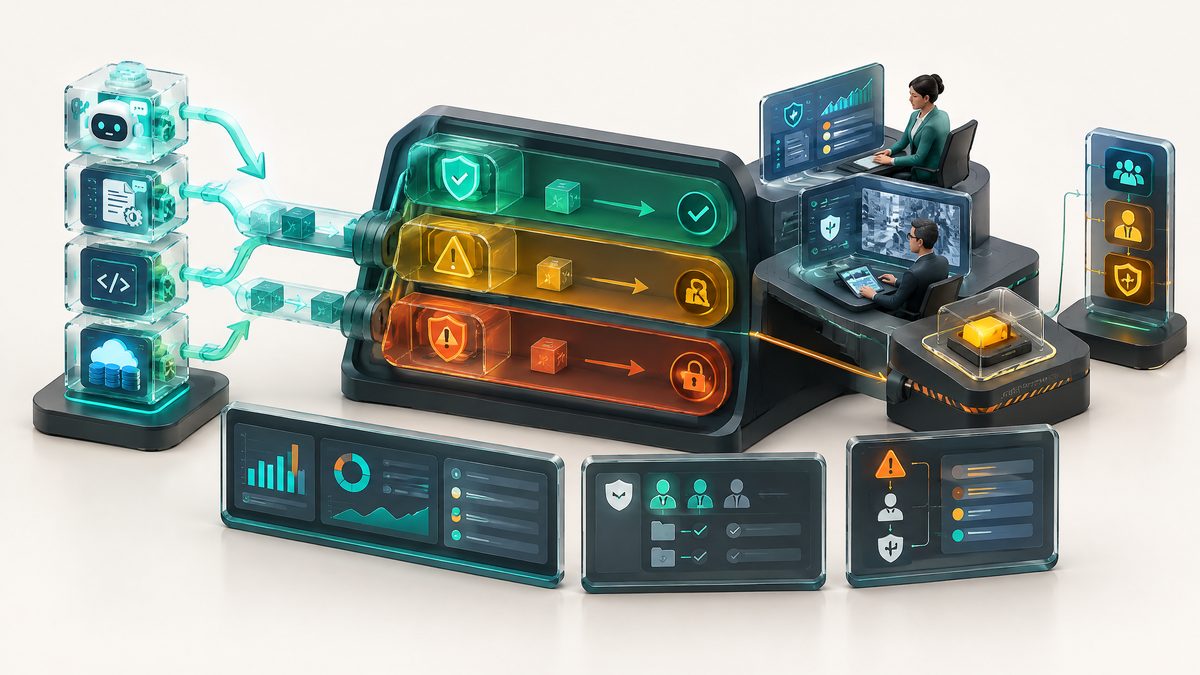
Build the operating model in layers:
- Research layer: use approved sources and retain citations.
- Recommendation layer: produce options with confidence, assumptions and omitted evidence visible.
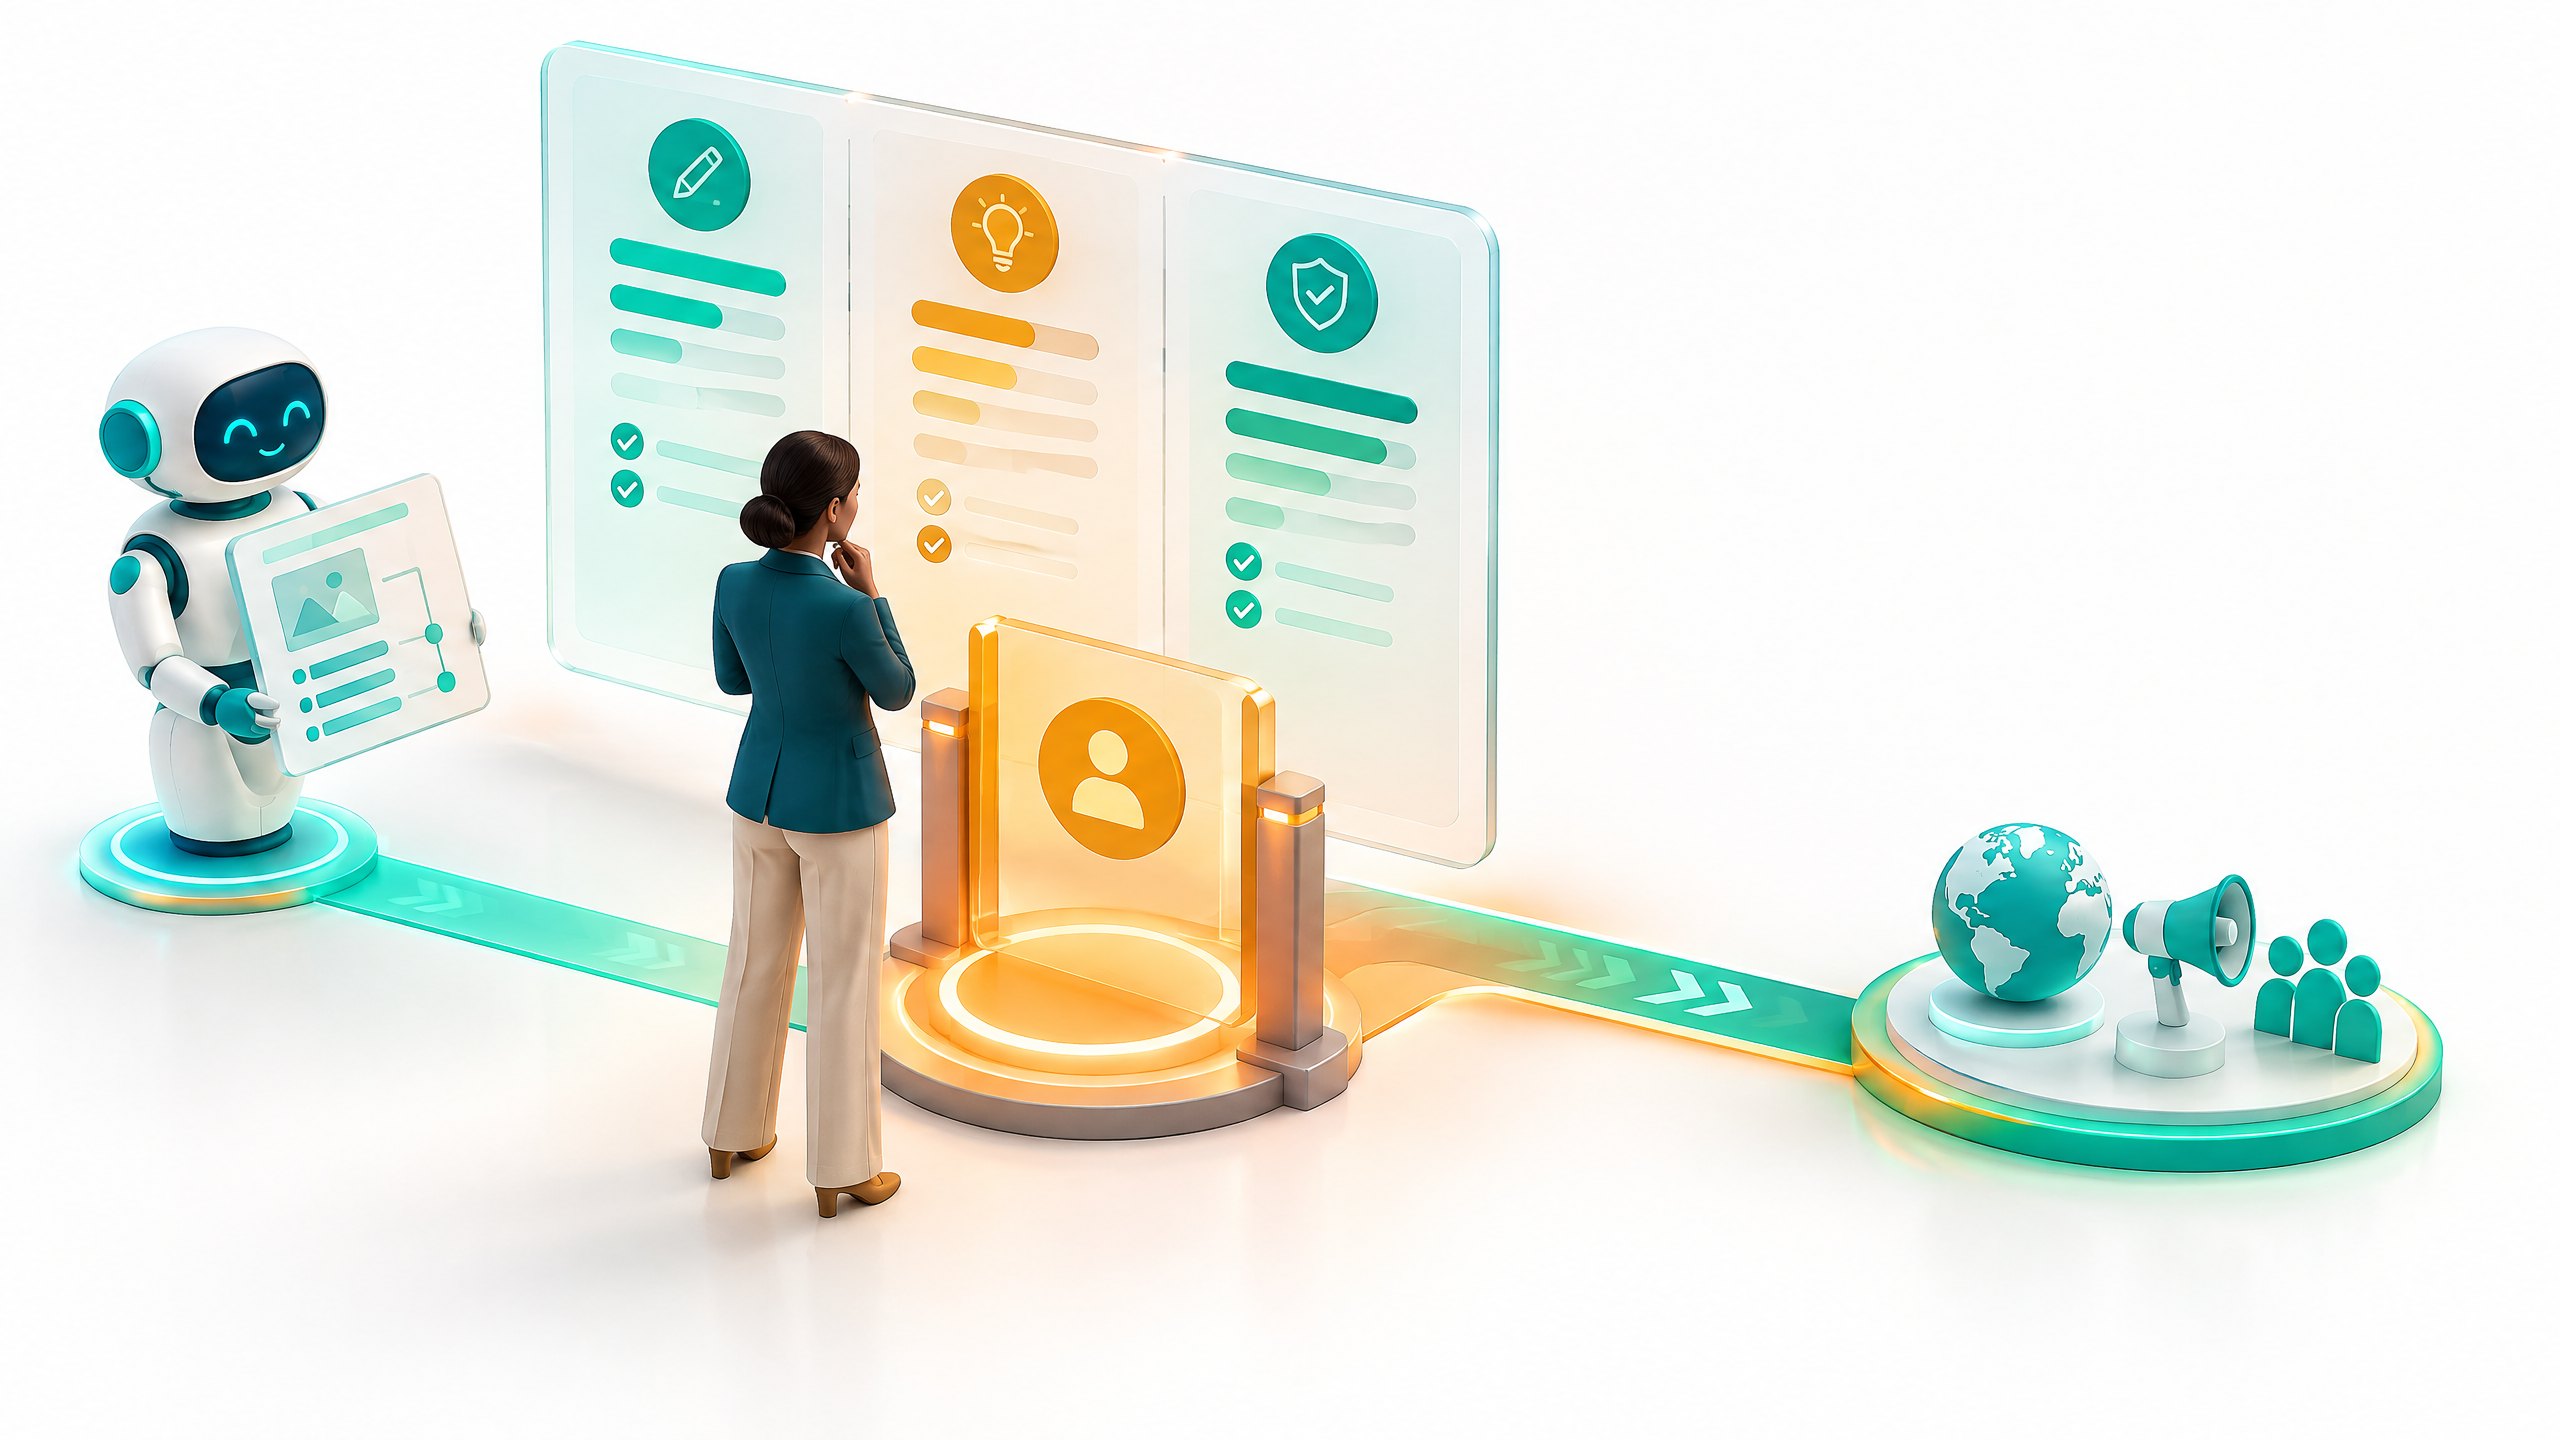
- Execution layer: make only bounded, reversible changes to a review queue or defined environment.
- Commitment layer: require a named approver for spend, live publication, external terms, customer data disclosure or a decision that cannot be easily undone.
This lets teams scale the work that is genuinely repetitive while putting human attention where it creates the most risk reduction. It also improves measurement. A team can compare the quality, speed, exception rate and commercial impact of a bounded workflow without pretending a general AI story proves ROI.
For a practical wider architecture, see operational identity and delegation for AI agents and why the usual human-in-the-loop label can fail.
A 30-day implementation plan
Days 1–7: choose one workflow. Select a job with clear inputs, a clear business owner and a clear end state. Avoid a workflow with unrestricted external authority as the first pilot.
Days 8–14: write the authority map. Document read, propose, change and commit permissions. State the Maximum Autonomous Consequence and the exceptions that trigger a stop.
Days 15–21: test normal and abnormal paths. Run examples with missing source material, conflicting data, unusual customer requests and an attempt to exceed the allowed action. Capture how the system stops and how a person receives the case.
Days 22–30: review decision evidence and recovery. Confirm the team can see the agent identity, instruction, important source context, tool action, approval and outcome. Test revocation and rollback. Only then decide whether the boundary can expand.
For a management-focused introduction, Responsible AI: Implement an Ethical Approach in your Organization is an optional Amazon UK Associates resource. It is not legal advice, a safety certification or proof that a named agent is suitable for a specific regulated workflow. Integrated.Social may earn from qualifying purchases.
The bottom line
The best governance test for an AI agent is not a vague promise of oversight. It is the most consequential action the agent can take before a person has to intervene. Name that action, decide whether it is acceptable, keep the evidence and test the stop path. That turns “human in the loop” from a slogan into an operating control.
References
- Reuters: OpenAI safety employee quits, says ‘time for trial and error is over’, 3 October 2026.
- Microsoft: Insights from the 2026 Microsoft Digital Defense Report, 1 October 2026.
- NIST: AI Risk Management Framework.
About the Author
Modi Elnadi is the founder of Integrated.Social, a London AI growth consultancy working across B2B, B2C, B2B2C and DTC. Since 2014, he has helped commercial teams connect performance marketing, AI-search visibility and governed AI workflows to clear evidence and accountable outcomes. His view: delegation earns trust only when its identity, authority, evidence and human escalation path are visible. Connect with Modi on LinkedIn or explore AI governance.