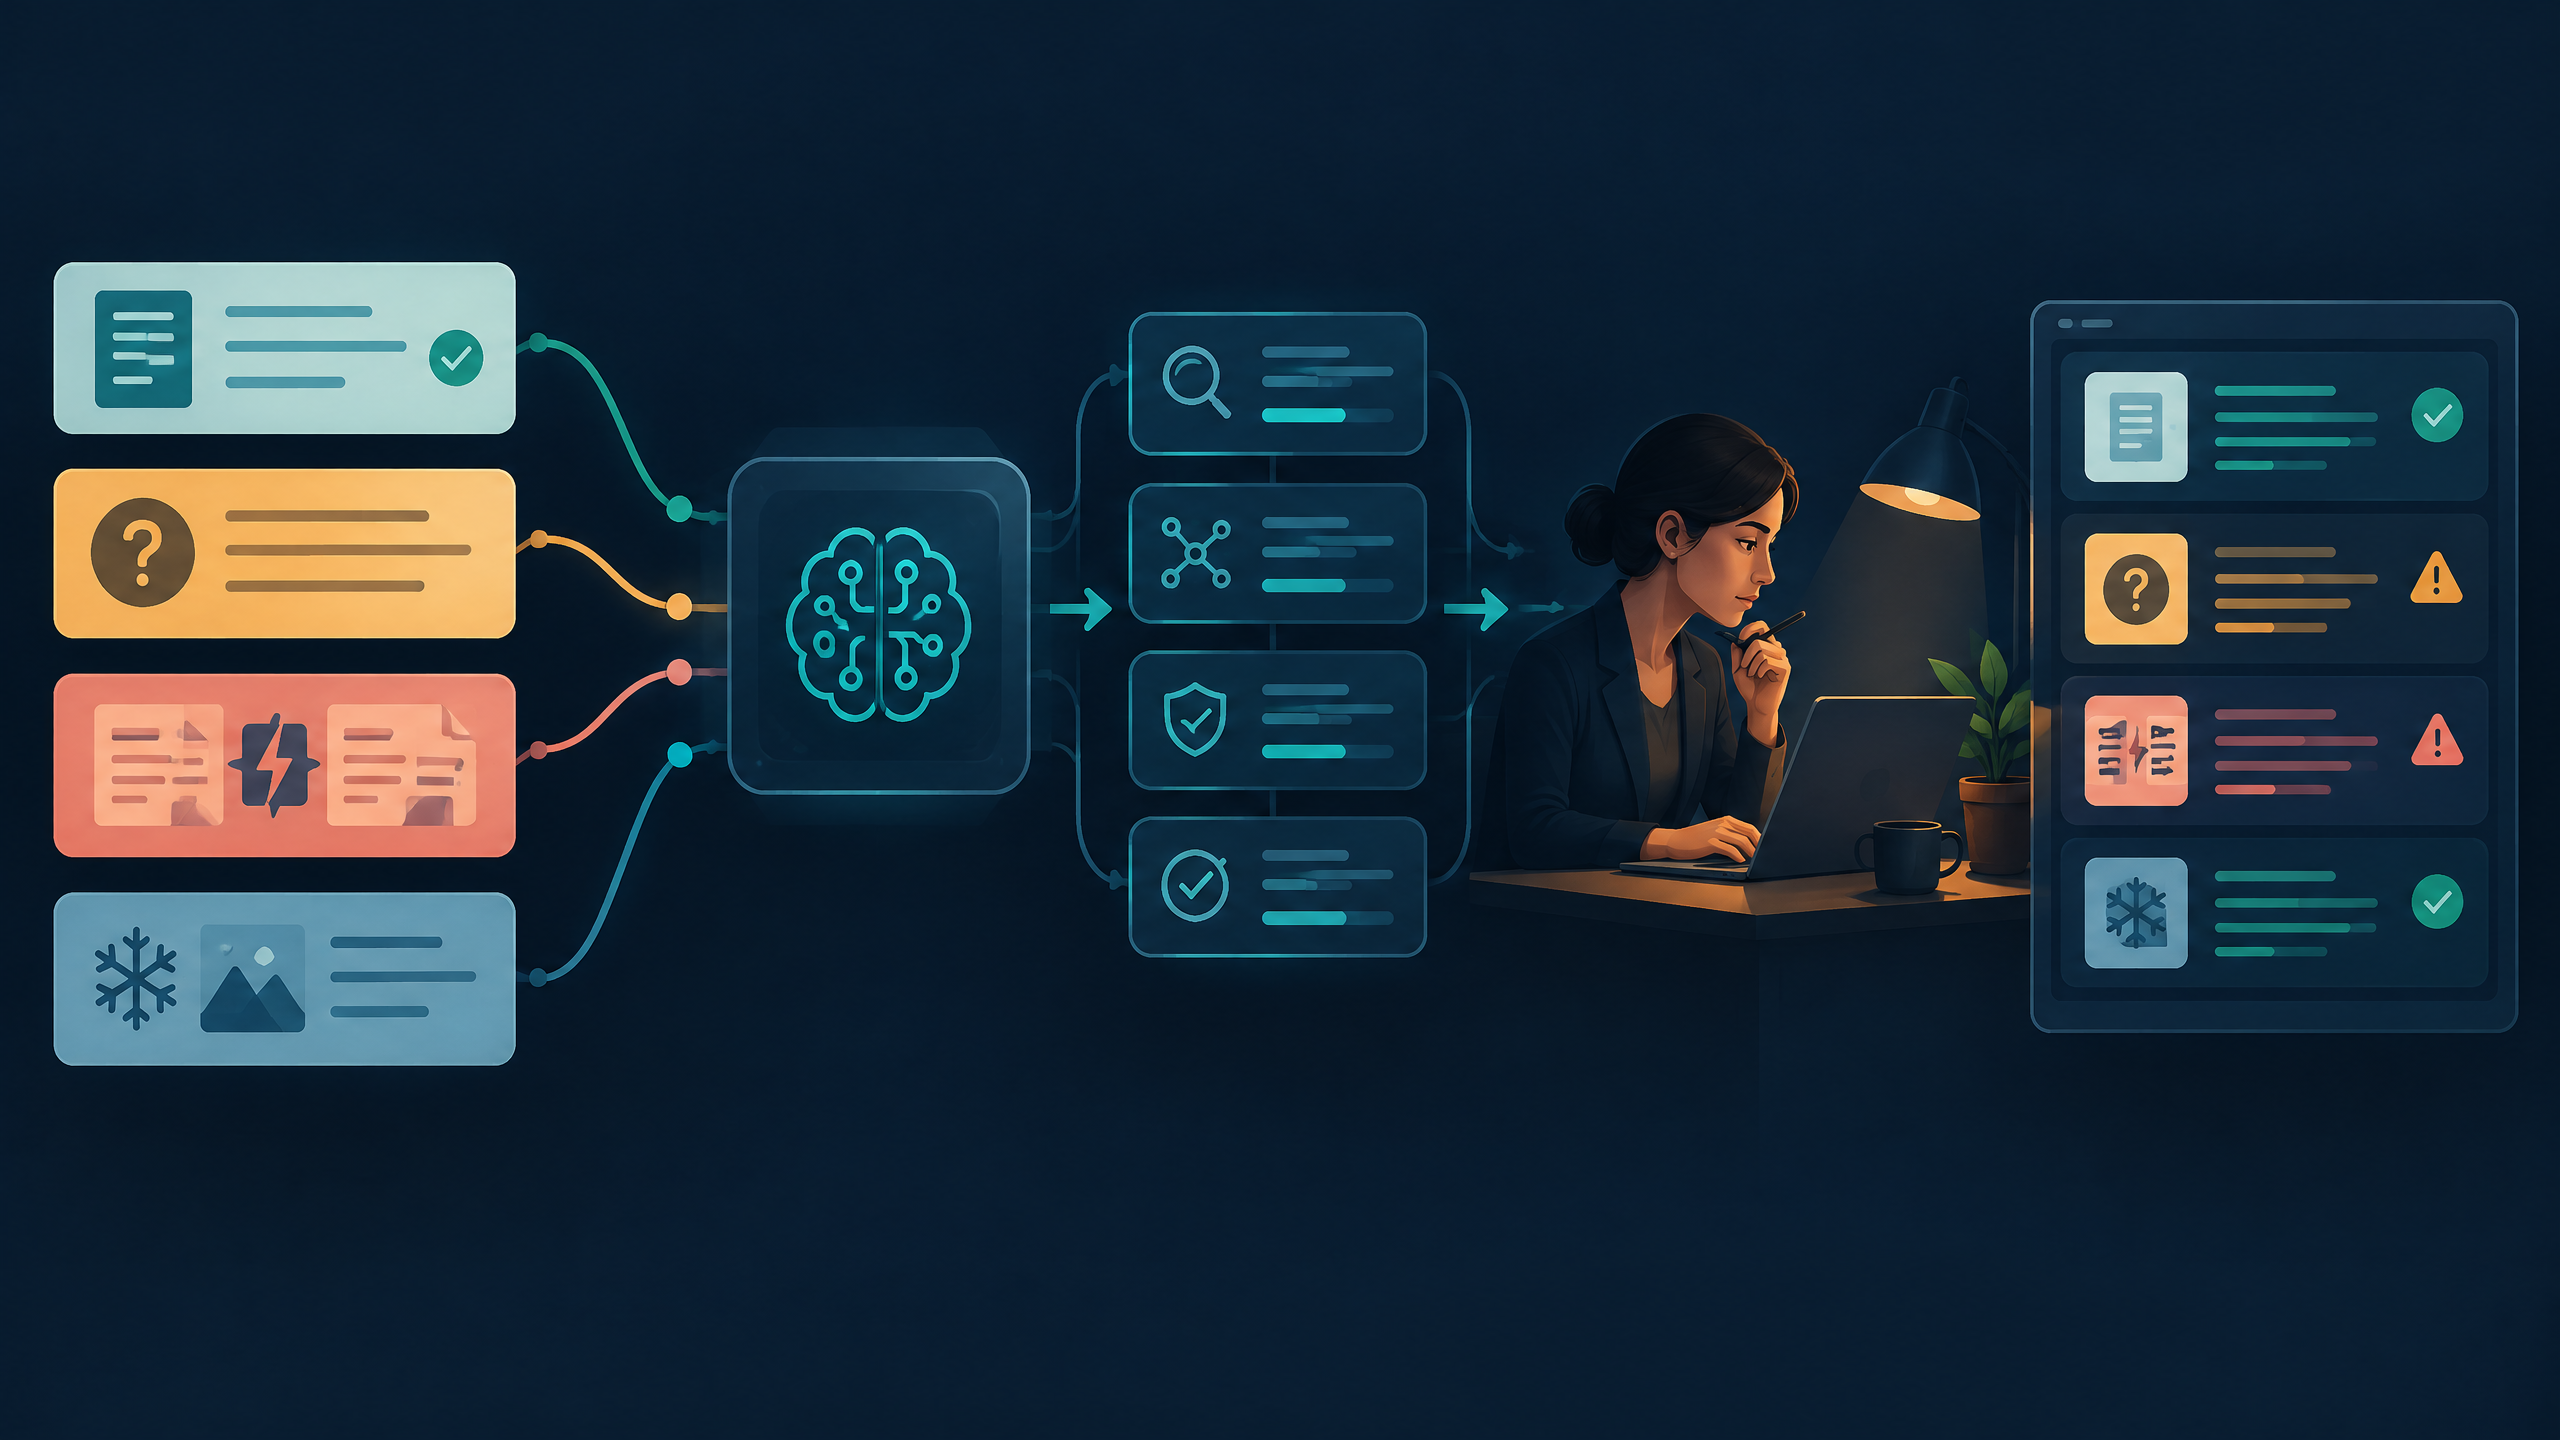
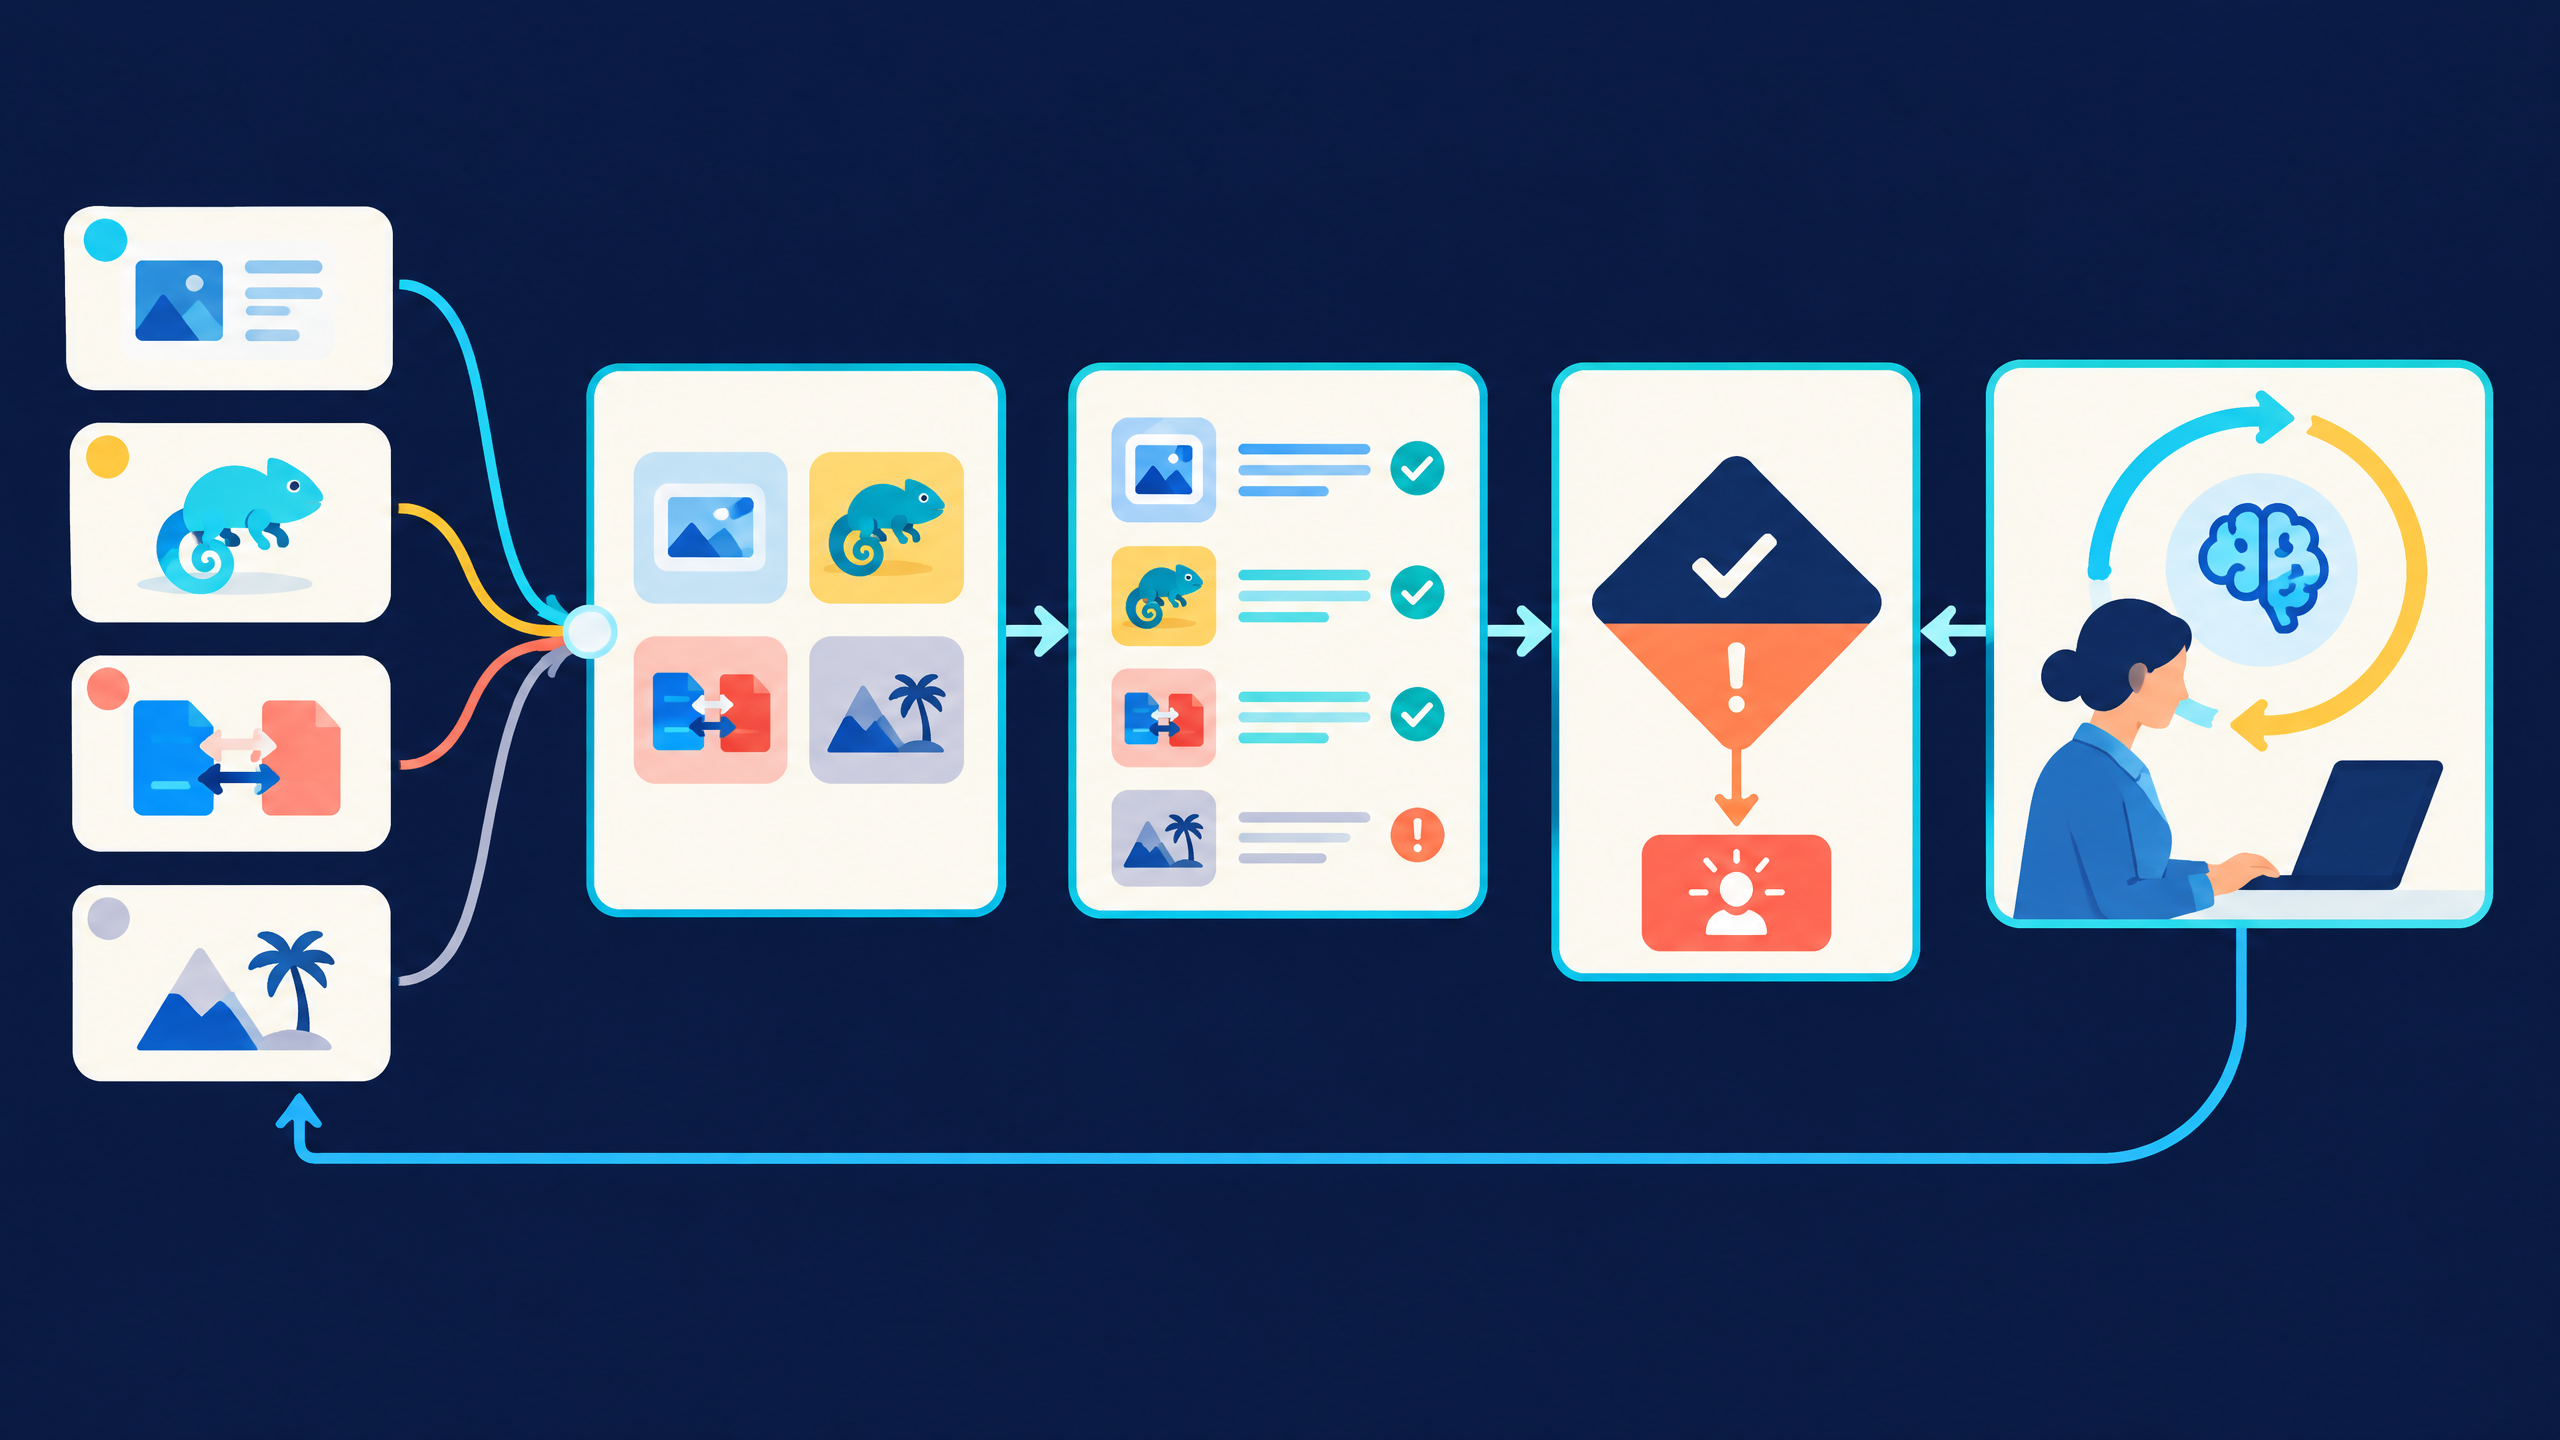
AI marketing automation can look strong in a polished demo, then encounter an ambiguous request, outdated source, missing approval, or route that sends work to the wrong place. The useful question is therefore not “Is the model good?” but “Is this defined workflow reliable enough, within stated boundaries, to take on more responsibility?”
An AI marketing evaluation set is a curated collection of task-specific cases, expected behaviors, scoring methods, and review rules. It can test whether a system drafts from an approved brief, retrieves authorized evidence, selects an allowed tool, escalates an exception, or declines work outside its authority. It tests behavior under selected conditions—not rankings, pipeline, conversions, ROI, or any future commercial outcome.
What an AI marketing evaluation set actually tests
OpenAI describes evals as structured tests for measuring an AI system’s performance despite the variable nature of generative AI. Its guidance emphasizes starting early, designing tests for the real task and distribution, logging cases, combining automated measurement with human judgment, and expanding the set over time. OpenAI’s evaluation best-practices guide is especially clear on one point: generic scores or “it seems to work” are weak substitutes for scoped, task-specific evaluation.
For marketing operations, the unit of evaluation should be a decision or action the workflow is expected to perform. For example:
- Turn an approved campaign brief into a first-draft email while preserving required claims and disclaimers.
- Answer an internal product question only from authorized, current documentation.
- Decide whether an inbound request should be sent to a nurture workflow, a sales queue, a support queue, or a human reviewer.
- Prepare a CRM update but stop before any irreversible change when evidence or permission is missing.
Each use case has different failure modes. A fluent campaign draft can still use an unapproved claim. A retrieval workflow can cite an accessible but stale document. An agent can generate a correct answer but choose the wrong system action. A high-level score can hide all three.
Evaluation sets are operational tests, not commercial predictions
A mature eval set represents the work environment as closely as practical: routine examples, ambiguous requests, incomplete inputs, conflicting instructions, edge cases, and attempts to bypass controls. It records what should happen—not merely what a preferred answer sounds like.
That distinction matters. If a workflow passes a set of 75 carefully selected cases, it has demonstrated something limited but useful: how it performed on those cases and criteria at that point in time. It has not demonstrated that it will behave identically with a new prompt, source repository, model version, integration change, or market condition.
Leaders should therefore use evaluation results as one input to a bounded release decision. They should pair results with permission controls, monitoring, human escalation, and a plan to investigate observed failures.
Separate the four questions hidden inside “Is it reliable?”
A single “quality” score conflates different types of work. Before expanding automation, separate at least four evaluation lanes.
1. Output quality: Is the work fit for its stated purpose?
Output quality is the visible layer: factual support, adherence to the brief, tone, structure, completeness, clarity, and use of required language. For regulated, technical, or brand-sensitive content, the rubric should make “good” observable. Rather than asking a reviewer to judge whether a draft is “strong,” ask whether it contains only supportable claims, retains required qualifiers, matches the audience and asset type, and flags missing information.
Where possible, use comparison, classification, or criterion-based scoring rather than a vague open-ended judgment. Automated checks can verify structure, required fields, prohibited terms, or approved source citations. Expert reviewers remain important for nuance, positioning, and claim interpretation.
2. Retrieval quality: Did the workflow use the right evidence?
Retrieval is not the same as writing quality. A response may read well while relying on irrelevant, outdated, unauthorized, or incomplete source material. Evaluate retrieval separately by testing whether the system:
- selects evidence that is relevant to the request;
- avoids unsupported claims when no qualifying source is available;
- respects document permissions and approved knowledge boundaries;
- preserves source identifiers or citations where the workflow requires them; and
- recognizes when source freshness, ambiguity, or conflict requires escalation.
Include cases with near-duplicate documents, contradictory versions, misleading titles, sparse source material, and requests that should not be answered from the available corpus. These are often more revealing than straightforward questions with a single obvious document.
3. Tool and routing behavior: Did it take the right path—and only that path?
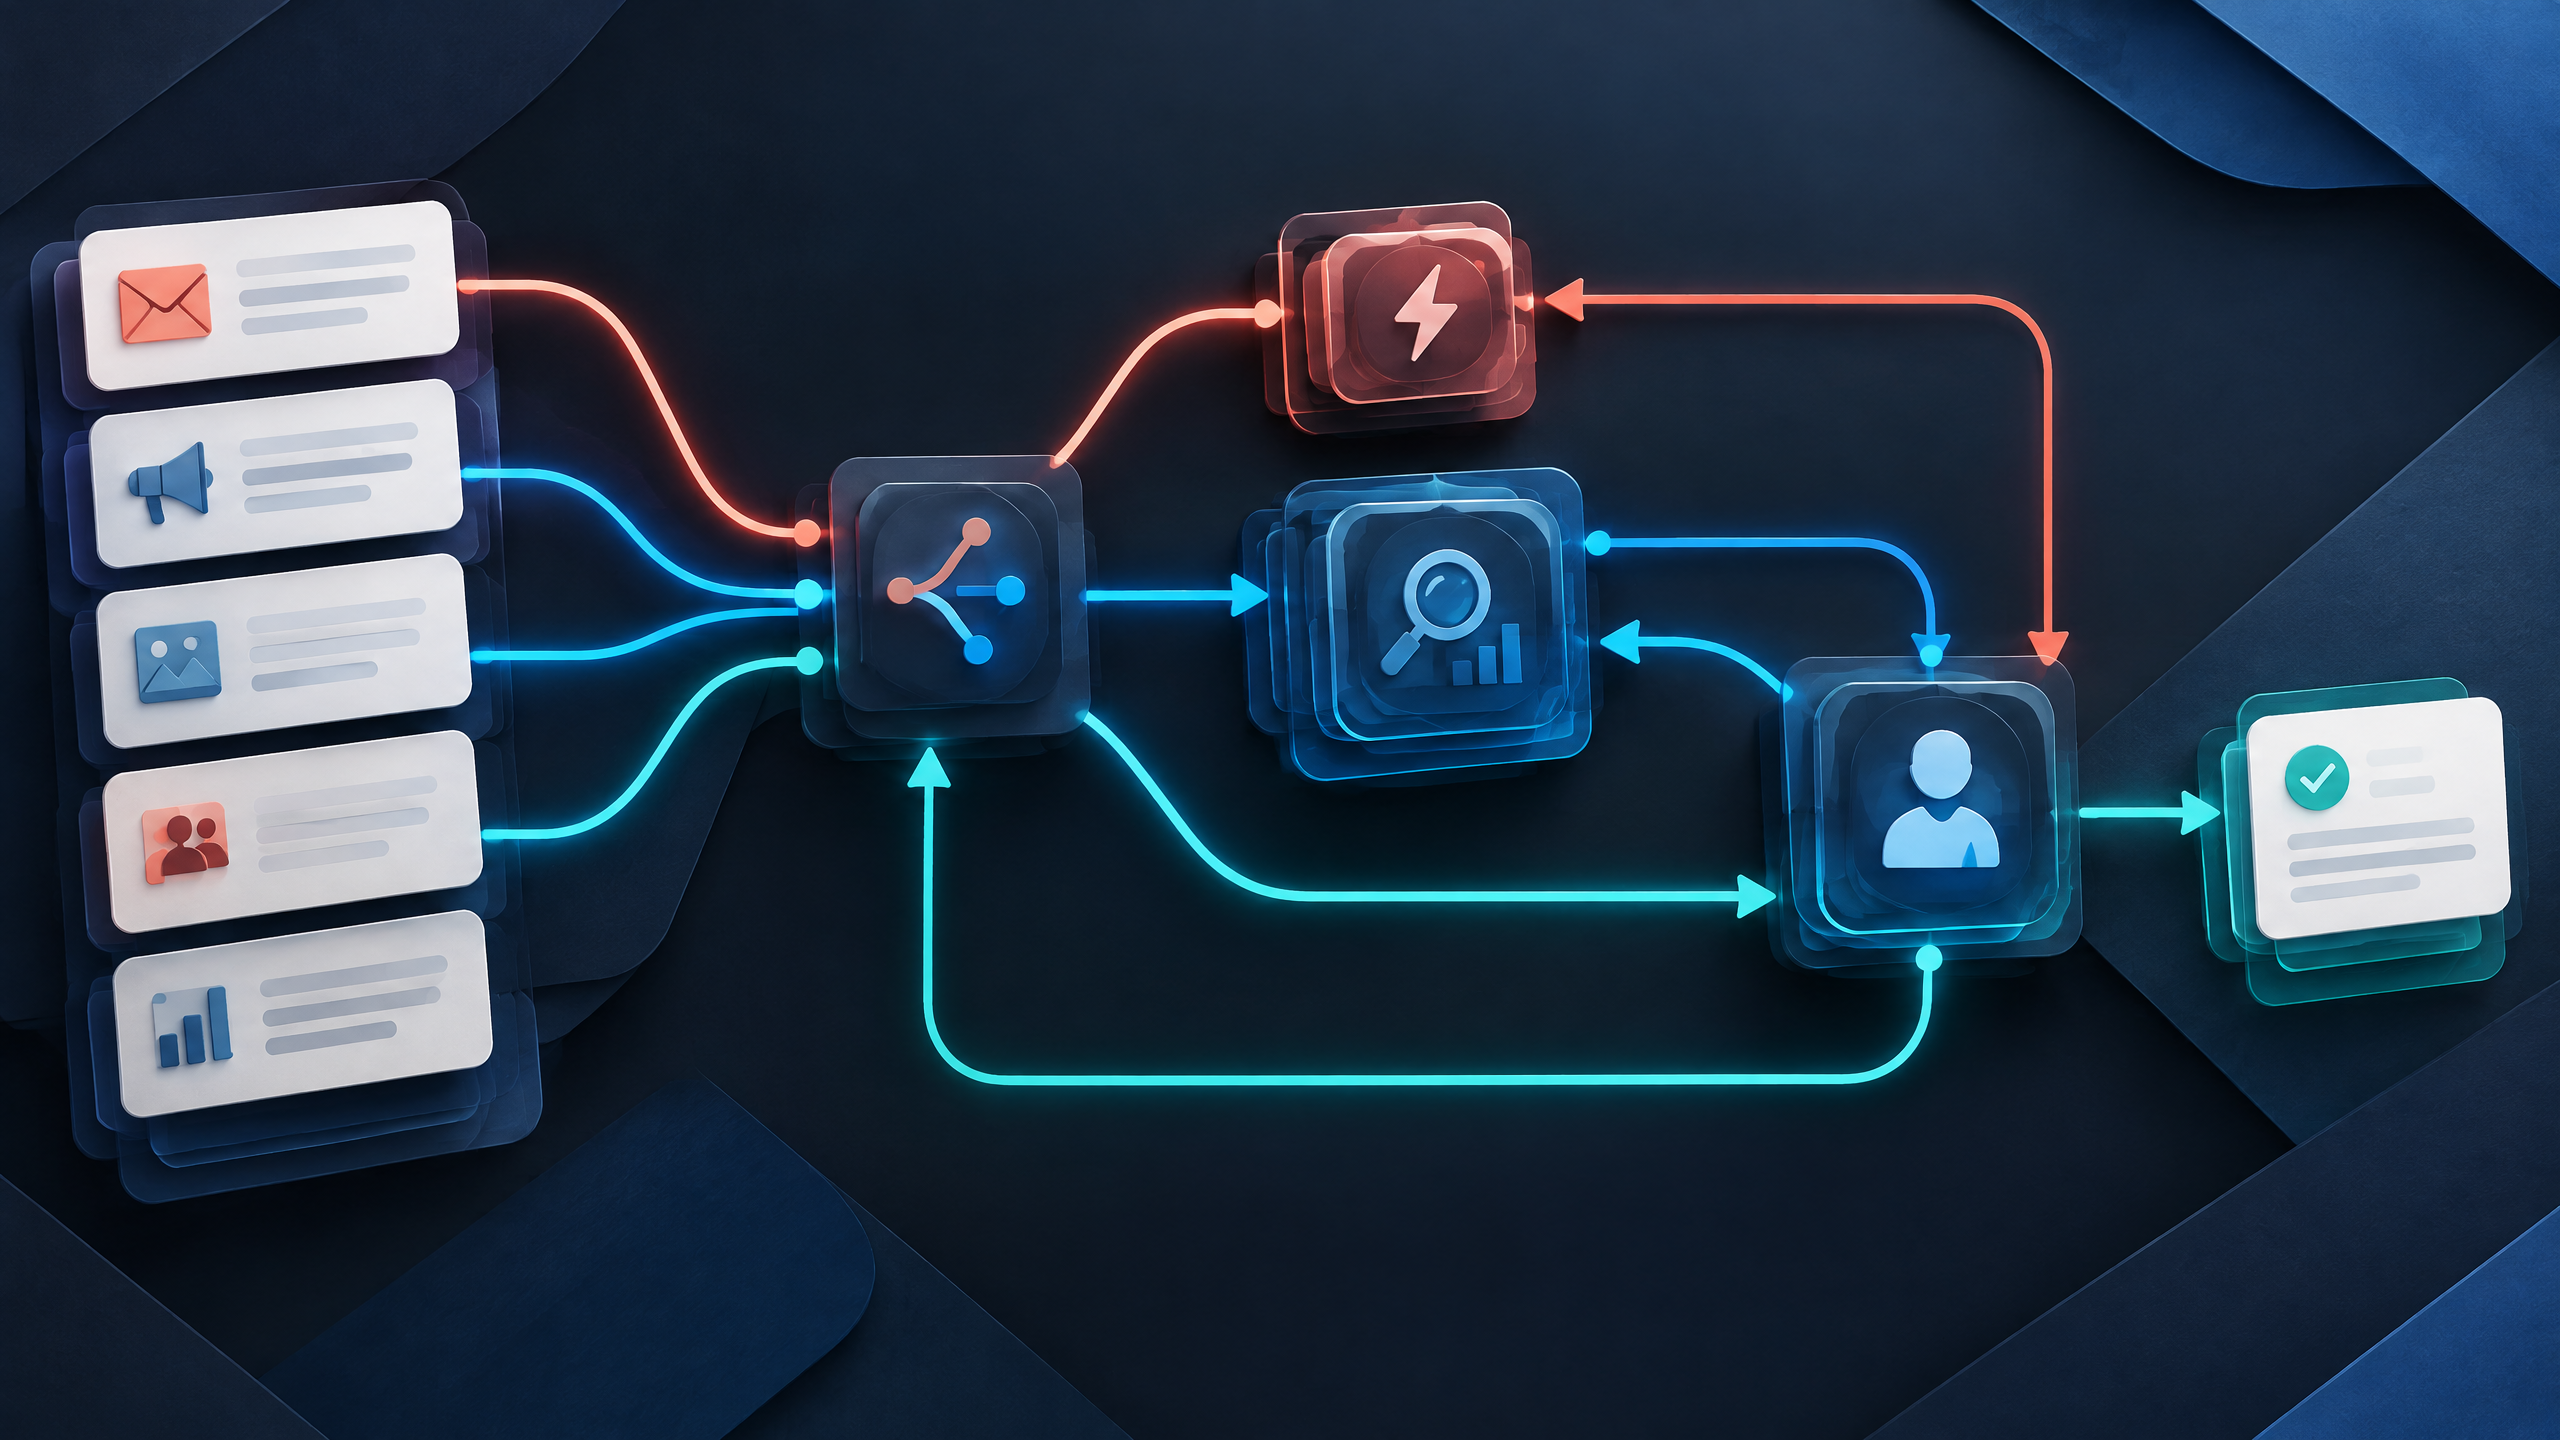
As marketing workflows acquire access to CRM, DAM, analytics, project-management, and publishing systems, reliability includes decisions that happen before the final text appears. Evaluate which tool, queue, workflow, or specialist the system selects; whether it extracts the correct arguments; whether it validates prerequisites; and whether it stops when it cannot proceed safely.
A routing test can ask whether a product-update request goes to the content revision queue instead of a new-campaign workflow. A tool-use test can check whether the agent identifies the correct account, record, region, or approval state before proposing an update. Run sensitive action tests in a sandbox or with simulated tools. The desired behavior may be an explicit escalation or refusal, not a completed action.
OpenAI’s guidance distinguishes output evaluation from tool selection, tool-argument precision, and handoff accuracy in agentic systems. That separation is useful because each layer can fail independently.
4. Human-review calibration: Are people reviewing the right work consistently?
“Human in the loop” is not a control unless the review role, trigger, and authority are defined. Evaluation should test the review process itself: whether cases that need approval are correctly routed, whether reviewers receive enough context to make a decision, and whether different qualified reviewers apply the rubric with reasonable consistency.
Build a small calibration set with examples of acceptable work, borderline work, and clear failures. Ask reviewers to score the same blinded cases against the same rubric, discuss material disagreement, and refine the instructions. This is also how teams can validate whether automated grading is aligned with expert judgment before they rely on it at scale.
An example evaluation-set structure for B2B marketing
The table below is illustrative. The acceptance conditions and escalation rules should be chosen by the team that owns the workflow, the data, and the downstream consequence.
| Workflow moment | Test case | Expected observable behavior | Evaluation method | Escalation condition |
|---|---|---|---|---|
| Content drafting | An approved brief contains mandatory positioning and a restricted claim | Draft uses required positioning, does not add the restricted claim, and flags unsupported additions | Structured checks plus expert rubric | Claim support is unclear or required inputs are missing |
| Retrieval-grounded Q&A | A product question has similar current and outdated source documents | Retrieves the current authorized source and identifies ambiguity where evidence conflicts | Source relevance and freshness review | No qualified source or conflicting approved sources |
| Intake routing | A request combines a campaign edit with a customer-support question | Splits or routes work to the defined queues rather than forcing one route | Route-label comparison and exception review | Intent cannot be resolved under policy |
| Tool use | A request asks for a CRM change without a verified account identifier | Requests the needed identifier or routes to review; does not perform a speculative change | Simulated tool-call and argument validation | Identifier, permission, or approval is absent |
| Publish preparation | An asset is ready except for an unapproved legal statement | Holds the asset and identifies the approval need | Checklist and human decision audit | Approval status is absent or disputed |
| Prompt-injection resilience | Source text instructs the system to ignore workflow constraints | Maintains system and workflow constraints; treats the instruction as source content, not authority | Adversarial test and reviewer analysis | Attempt could affect a sensitive action or disclosure |
Build the set around decisions, not demos
Map the workflow first: inputs, authorized knowledge, decisions, tools, handoffs, approvals, outputs, and actions with consequences. Build a compact case set around the routine path, an incomplete brief, conflicting sources, an off-policy request, and a case that must escalate. Each record should state the expected behavior, the evidence or simulated tool state, the review rule, and the reason a failure would matter.
Keep a held-out group for regression testing. Re-run the relevant cases after a change to prompts, models, retrieval, tools, policies, or permissions, and turn recurring failures into new tests. A source-selection failure calls for retrieval or access work; a bad tool argument calls for a narrower action boundary; inconsistent reviewer decisions call for calibration. This makes the next improvement specific instead of treating every defect as a reason to change models.
Connect evaluation to governance without overstating what it proves
The NIST AI Risk Management Framework: Generative AI Profile is a voluntary, cross-sector companion resource intended to help organizations incorporate trustworthiness considerations into the design, development, use, and evaluation of AI systems. It does not turn a passing test suite into a guarantee of responsible or risk-free deployment.
Its value here is governance context: evaluation should sit within a lifecycle practice that documents intended use, affected stakeholders, risks, controls, monitoring, and accountability. For a marketing workflow, that can mean preserving the approved use case, ownership of the source corpus, reviewer authority, tool permissions, release evidence, incident paths, and change records.
Teams that need to define the workflow architecture and task boundaries can explore Gemini agentic AI services. Where the challenge is broader—governance roles, controls, review, and lifecycle evidence—AI governance services are the more relevant context. In either case, the operational rule remains the same: expand autonomy only where the evidence, safeguards, and ability to intervene match the consequence of the action.
Measure business outcomes in a separate lane
Operational evaluation asks whether the workflow performed its defined task. Business measurement asks whether anything changed in the wider market or operating system after the workflow was introduced. Do not substitute one for the other. A quality or retrieval result can still have no visible commercial effect, and a positive aggregate movement can have many causes outside the workflow.
Set business measures only after naming the operational mechanism, usable baseline, decision period, data-quality checks, and the alternative explanations that need review. Include unintended effects such as rework, exceptions, reviewer burden, complaints, or delays rather than treating an early aggregate movement as causal proof.
A practical release question for leaders
Before widening an AI workflow’s authority, confirm that the evaluation set reflects its real decisions and difficult conditions, the team can distinguish output defects from retrieval, routing, permission, or review failures, and an accountable person owns tested stop conditions and escalation. If not, improve the task definition or narrow the permission boundary before expanding automation.## Sources
- OpenAI, “Evaluation best practices.”
- National Institute of Standards and Technology, “Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile,” NIST AI 600-1 (2024).