The practical answer: lower listed token prices and better reuse of stable prompt context can make repeatable agent workflows cheaper to test and govern. OpenAI lists GPT-6 Sol at $2 per million input tokens and $10 per million output tokens, and GPT-6 Luna at $0.10 per million input tokens and $0.50 per million output tokens—a 50% reduction versus the cited GPT-5.6 promotional prices.OpenAI’s Sol and Luna announcement At the same time, OpenAI says its revised prompt caching can discount eligible cached input-token reads by up to 90% when a shared prefix is reused within a 30-minute window.OpenAI’s prompt-caching announcement
That is meaningful operational news for marketing and revenue teams building agents that repeatedly start from the same brand rules, ICP definitions, product facts, tool schemas, approval policies, and campaign context. It is not a total-cost promise, an ROI claim, or proof that an autonomous agent should be trusted with unsupervised customer-facing decisions. Token pricing is one variable in an operating system that also includes task design, tool calls, retrieval, retries, human review, exception handling, data permissions, and the cost of getting a decision wrong.
The strategic question for GTM leaders is therefore more precise: which parts of a workflow genuinely repeat, which must change for each account or campaign, and what evidence would justify moving a task from assisted work to controlled automation?
The Actual Change: Lower Listed Prices Plus Cache-Aware Operations
OpenAI positions Sol as the higher-capability member of this pair for difficult work and Luna for faster, lower-cost, high-volume work. TechCrunch describes the tiers in similar terms: Sol for complex tasks such as coding, Luna for clerical work with a clear goal such as summarization, extraction, or quick answers.TechCrunch’s launch coverage For GTM, that distinction may matter more than a broad “best model” question.
The price card is simple; the work unit is not
| Model | OpenAI-listed input price | OpenAI-listed output price | Sensible GTM test hypothesis |
|---|---|---|---|
| GPT-6 Sol | $2 / 1M tokens | $10 / 1M tokens | More complex research, synthesis, planning, or multi-step work requiring stronger reasoning. |
| GPT-6 Luna | $0.10 / 1M tokens | $0.50 / 1M tokens | Bounded, repeatable classification, extraction, routing, formatting, or first-pass drafting. |
These are OpenAI’s published API prices, not a price per campaign, account, qualified meeting, or completed business outcome. A workflow can consume materially different input, output, tool, and review effort depending on its design. A low-cost model can also become expensive in practice if it produces more retries, longer outputs, or errors that need correction.
The New Stack makes the same budgeting point in its launch analysis: it is difficult to know in advance how many tokens an agent will use to finish a task. It also notes that no independent head-to-head comparison of Sol and Anthropic’s newly released Opus 5.5 had been run at publication.The New Stack’s analysis Treat model-price comparisons as inputs to a test plan, not an approval memo.
Prompt caching is shared-prefix reuse, not persistent memory
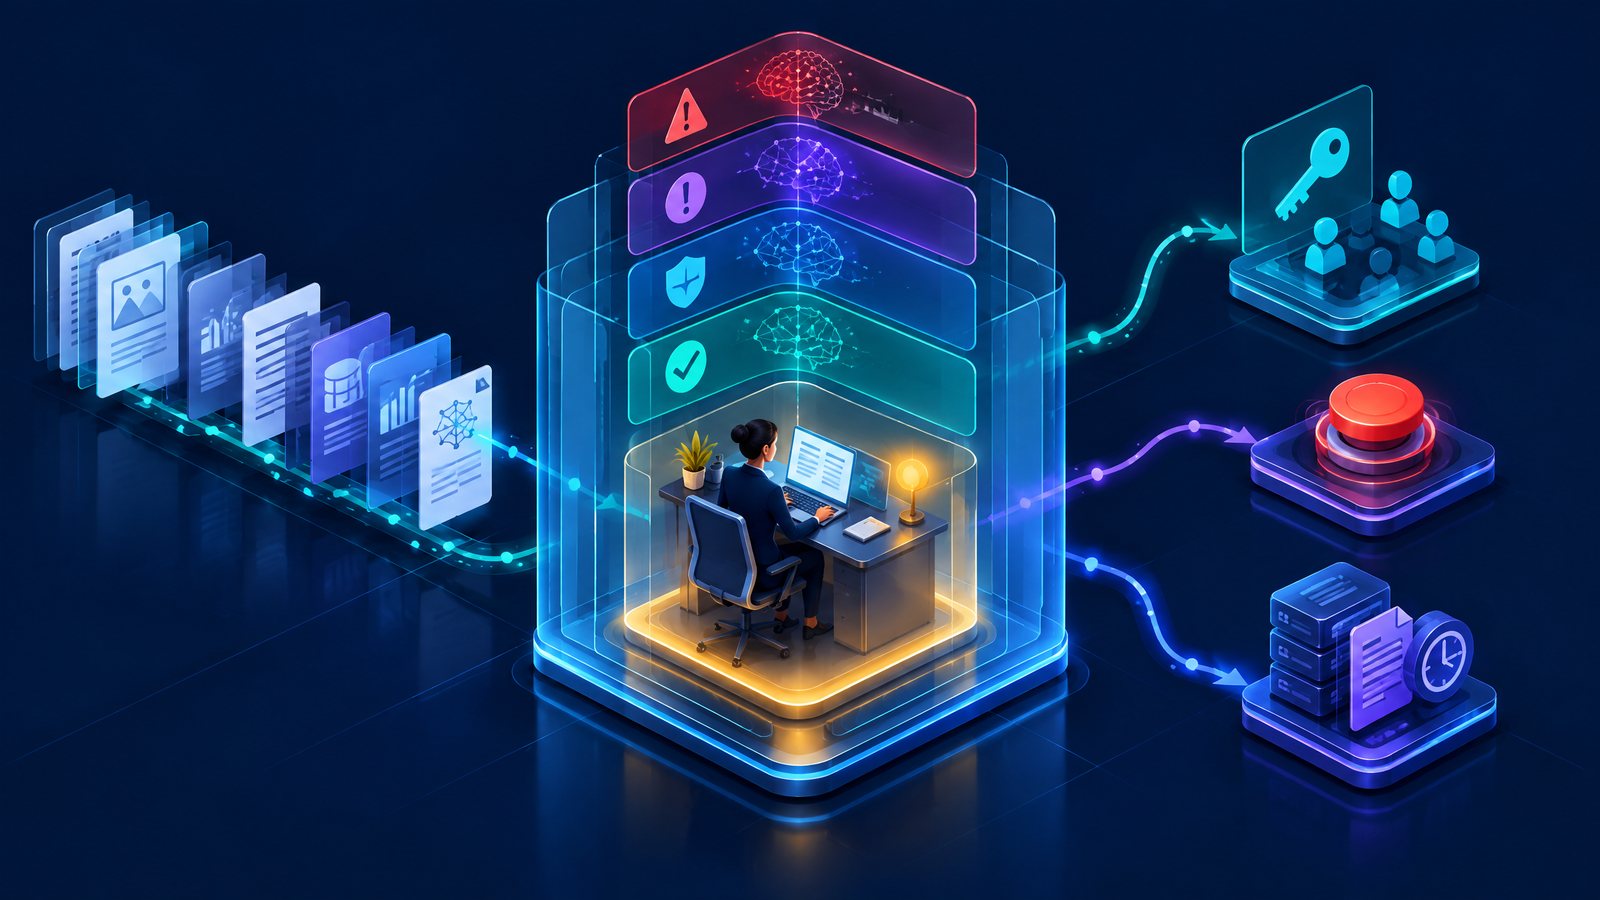
This distinction matters. OpenAI describes prompt caching as reuse of computation when a series of API requests carry forward the same instructions, tool definitions, and earlier context. For GPT-6, it says discounts apply to eligible shared prefixes reused within 30 minutes. A prefix might contain a brand voice guide, a campaign brief template, a stable tool catalog, a product taxonomy, or an agent’s operating rules.
That is not persistent memory. Prompt caching does not establish a durable, correctly governed record of a prospect, an account, a customer approval, or a prior conversation. If an agent needs durable state, the application must deliberately store, retrieve, authorize, update, and audit it. Caching can make the repeated context cheaper and faster to process; it does not decide what the system should remember, whether the information is current, or whether the agent should be allowed to use it.
OpenAI also says teams can adjust reasoning effort and tool availability without necessarily breaking earlier cache reuse, and offers explicit cache breakpoints, a dashboard, and diagnostics for cache misses. That makes cache performance inspectable, but it still has to be measured on the actual workload.
Where GTM Workflows Fit—and Where They Do Not
GTM work often has a stable operating layer—positioning, claims rules, approved sources, tool schemas, and CRM-field definitions—plus changing account or campaign facts. That supports a testable pattern: hold genuinely stable material early in the prompt and append volatile facts later. It is not universal. Frequent changes to the early prompt, tool ordering, or instructions can limit reuse.
Good first candidates are bounded: validate and route an inbound brief; assemble approved public facts into a sales-research template; or check a draft against a fixed disclosure and formatting list. The goal is better preparation and repeatable coordination, not a model assuming market judgment, legal approval, customer trust, or revenue responsibility.
Confirmed Facts Versus Commercial Inferences
A disciplined GTM plan separates what the announcement confirms from what a team still has to prove.
| Statement | Status | Responsible interpretation |
|---|---|---|
| Sol and Luna have lower listed API token prices than the cited GPT-5.6 promotional prices. | Confirmed by OpenAI | Update the model-cost assumptions in the test model. |
| Eligible shared prompt prefixes reused within 30 minutes can receive up to a 90% cached-input discount. | Confirmed by OpenAI | Measure eligible cached-input share; do not apply 90% to the total task cost. |
| GPT-6 caching produces a specific total-cost reduction for your workflow. | Inference to test | It depends on prompt composition, cache hits, output, tools, retries, and operational controls. |
| A marketing agent can be safely given more autonomy. | Governance decision | Require task-level quality, permission, escalation, and audit evidence. |
| A benchmark result proves GTM performance. | Not established | Benchmarks can inform model selection, but they do not reproduce your data, tools, constraints, or review rules. |
This boundary prevents a common error in AI business cases: treating the maximum discount on one token category as a total-cost or ROI result. Cached input reads are only one component; fresh input, output, tools, people, and rework remain part of the economics.
Practical Checklist: Test Cache-Aware Agent Economics Before Scaling
Use this checklist before you broaden an agent beyond a narrow pilot.
- Choose one measurable job. Define the start event, acceptable output, user, escalation path, and failure condition. “Improve GTM” is not a testable job; “validate and route a complete inbound campaign brief” can be.
- Map the prompt into stable and changing layers. Identify instructions, tool schemas, policy, and reference material that genuinely repeat. Keep account, campaign, or current-event facts clearly separate.
- Keep stable prefixes stable. Version brand rules and tool definitions. Avoid casually rewriting their ordering between runs if reuse is an objective.
- Respect the 30-minute eligibility window. Design batches, event timing, and any prewarming experiment around that window, while treating actual cache behavior as something to observe in the dashboard.
- Set a quality baseline. Compare agent outputs with the current human or assisted process using a rubric: factual support, routing accuracy, policy compliance, format completeness, and editor acceptance.
- Measure token composition, not just spend. Record fresh input, cached input, output, cache-hit rate, tool calls, retries, latency, and exception rate for every material run.
- Install authority boundaries. Restrict actions, use least-privilege access, require approval for external communication or record changes, and preserve a reviewable trace of material decisions.
- Define stop and scale criteria in advance. State what would pause the pilot, what evidence would permit more volume, and which human controls stay in place.
The checklist sounds cautious because it should be. A GTM workflow often touches customer data, offers, public statements, attribution, or CRM records. Cheap repeated computation does not remove the cost of an incorrect outreach message, a bad segment decision, an unsupported claim, or an unauthorized action.
How to Model the Economics Without Pretending to Have an ROI Result
Start with a per-run observation rather than an annual savings forecast. For each run, measure:
Total observed operating cost = fresh input cost + cached-input cost + output cost + tool and infrastructure cost + human review and exception-handling cost.
Pair cost with quality using visible, consistent criteria: task completion, factual correctness, policy compliance, and reviewer acceptance. If a polished output takes longer to validate, the workflow may not improve.
Cache-aware design changes the first two terms. A large, eligible, stable prefix reused within the stated window may shift more input to cached reads; small, infrequent, or constantly changing prefixes may not. Luna may merit tests for structured, high-volume work; Sol may merit tests where deeper synthesis reduces review burden. Demonstrate the routing rule before relying on it.
Benchmark Headlines Inform Selection; They Do Not Approve a Deployment
OpenAI reports benchmark results including GPT-6 Sol’s 33.2% AutomationBench score at xhigh effort and $0.27 per task. These are OpenAI claims from stated evaluation conditions, not deployment approval. Your stack has different permissions, data, integrations, and failure consequences. Use current documentation, independent reporting, and a controlled internal evaluation. The operative question is: which model, prompt, tool policy, and human checkpoint meets this job’s acceptance standard at a measured operating cost?
Governance Is the Cost of Doing Agent Work Responsibly
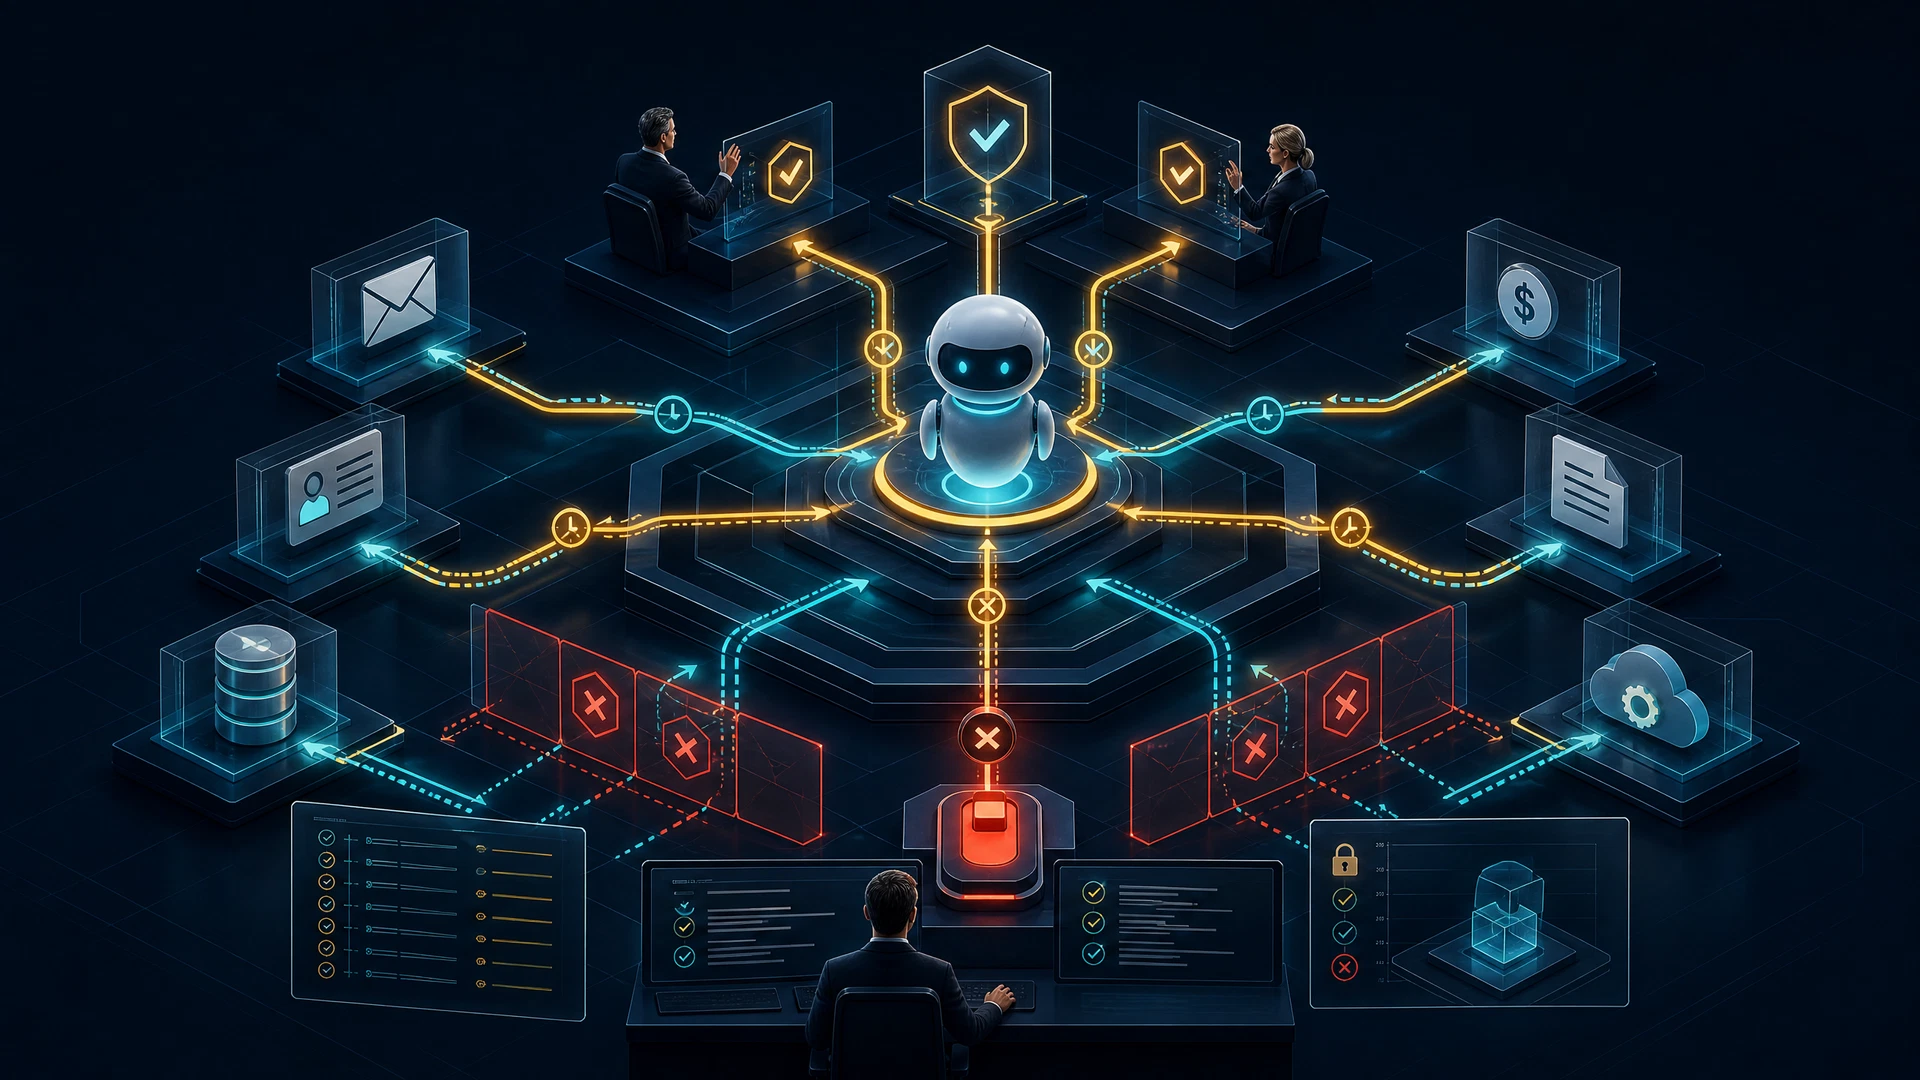
Cheaper iterations can multiply poorly scoped experiments. Each workflow should name its owner, approved sources, permitted tools, prohibited actions, required reviewer, and retention rules. An agent can prepare an account brief and flag ambiguity; it should not silently alter CRM stages, publish claims, send outreach, or infer sensitive attributes without explicit authority. The governing principle is contextual authority: the agent receives only the data and actions needed for its bounded role. Read AI Agents Do Not Need More Access. They Need Contextual Authority for that boundary.
Integrated.Social can help scope a controlled evidence, measurement, or governance review for a defined agent workflow through its Agentic AI service. The purpose is to clarify scope, controls, test design, and validation evidence—not to promise a commercial performance outcome.
For related operating context, see our guide to multi-agent AI systems for GTM and our explainer on AI governance and quality control.
The GTM Implication: Move From Model Excitement to Work-Unit Discipline
The Sol and Luna launch is important because it makes the economics of repeatable context a first-class design concern. The teams likely to benefit are not the ones that make the largest autonomy claim. They are the ones that identify a bounded job, stabilize the right shared context, retain human authority where it matters, instrument every run, and expand only when evidence supports it.
That approach is less theatrical than “AI agents for pennies.” It is also more useful. Lower listed token prices and improved cache controls may create room for more experiments. A controlled evaluation determines whether those experiments create dependable operational capacity—and where a human should remain firmly in the loop.
Frequently Asked Questions
What are the GPT-6 Sol and Luna API prices?
OpenAI lists Sol at $2 per million input tokens and $10 per million output tokens, and Luna at $0.10 and $0.50 respectively. These help estimate components, not a finished task: usage, tools, retries, and review differ by workflow.
Does GPT-6 prompt caching give an AI agent persistent memory?
No. It reuses eligible shared prompt prefixes within a 30-minute window. Persistent business context remains an application and governance responsibility: decide what is stored, who retrieves it, how it stays current, and how it is audited.
How should a GTM team test cache-aware agent economics?
Run a bounded pilot with a stable acceptance rubric. Separate stable prompts from changing facts, observe cache diagnostics and token composition, and log review, exceptions, and action outcomes before increasing volume or autonomy.
Should a company choose Sol or Luna solely on token price?
No. Start with the job. Luna may suit structured, high-volume work and Sol may suit more complex synthesis. Test against a quality standard, permission model, and measured operating cost; a cheaper rate is not a deployment decision.
Sources
- OpenAI, “Introducing GPT-6 Sol and Luna”: https://openai.com/index/introducing-gpt-6-sol-and-luna/
- OpenAI, “Better prompt caching for GPT-6”: https://openai.com/index/better-prompt-caching-for-gpt-6/
- The New Stack, “OpenAI releases GPT-6 Sol and Luna — and cuts token prices in half”: https://thenewstack.io/openai-gpt-6-sol-luna-release/
- TechCrunch, “OpenAI launches GPT-6 Sol and Luna, boasting lower cost and fewer mistakes”: https://techcrunch.com/2026/09/22/openai-launches-gpt-6-sol-and-luna/