On 5 October 2026, OpenAI announced a visual ChatGPT ad format for testing later that month in US image generation, alongside broader measurement partnerships. The practical implication is not that marketers can assume a new performance channel. It is that an AI conversation demands a measurement design built before spend is judged: eligible outcomes, reconciled data, consent limits, decision windows, holdouts and accountable human sign-off.
What OpenAI announced
OpenAI says ChatGPT reaches 1.2 billion people each week. Its announced visual format is intended to help people explore products and services through images. The first test is due to begin later in October 2026 in the United States with an initial group of advertisers, during image generation in ChatGPT.
The operating boundaries matter as much as the format. OpenAI says the ads will be clearly labelled, will remain separate from the image being generated, and will not influence the answers ChatGPT provides. Those statements distinguish an advertising placement from the response itself; they should also be treated as the starting conditions for brand, legal and measurement review rather than as a complete measurement answer.
The announcement also expands the advertised measurement ecosystem. Hightouch, Tealium and LiveRamp are named for sending conversion data from existing systems to ChatGPT Ads. AppsFlyer, Triple Whale, Adjust, DV Rockerbox, Northbeam, Branch, Singular, Kochava, Airbridge and Tenjin are named attribution partners. Fospha, Measured and INCRMNTAL are named for advanced measurement; Haus, Measured and WorkMagic are involved in exploring geo-based incrementality experiments.
For the source record, read OpenAI’s visual-format announcement and its measurement update. They define the platform statements; this article does not extend them into a performance guarantee.
Why an AI conversation is not a conventional pageview
A conventional pageview normally gives a media team a comparatively simple exposure unit to place beside a click, session and conversion record. A ChatGPT interaction is different: a person may be exploring, comparing, refining or deciding within a conversation. Seeing an ad, clicking it and acting can be separated in time—or an action may occur without a click. That makes a neat click-only scorecard an incomplete decision tool, not proof that every non-click effect is causal.
The measurement task is therefore to specify what evidence will be accepted before launch. A purchase may be an eligible conversion for one advertiser; a qualified lead, app install or sign-up may be appropriate for another. The event should be defined in business language, then mapped consistently across the website or app, CRM, analytics environment, partner tooling and finance reporting. If those records cannot be reconciled, a dashboard can look precise while remaining commercially unreliable.
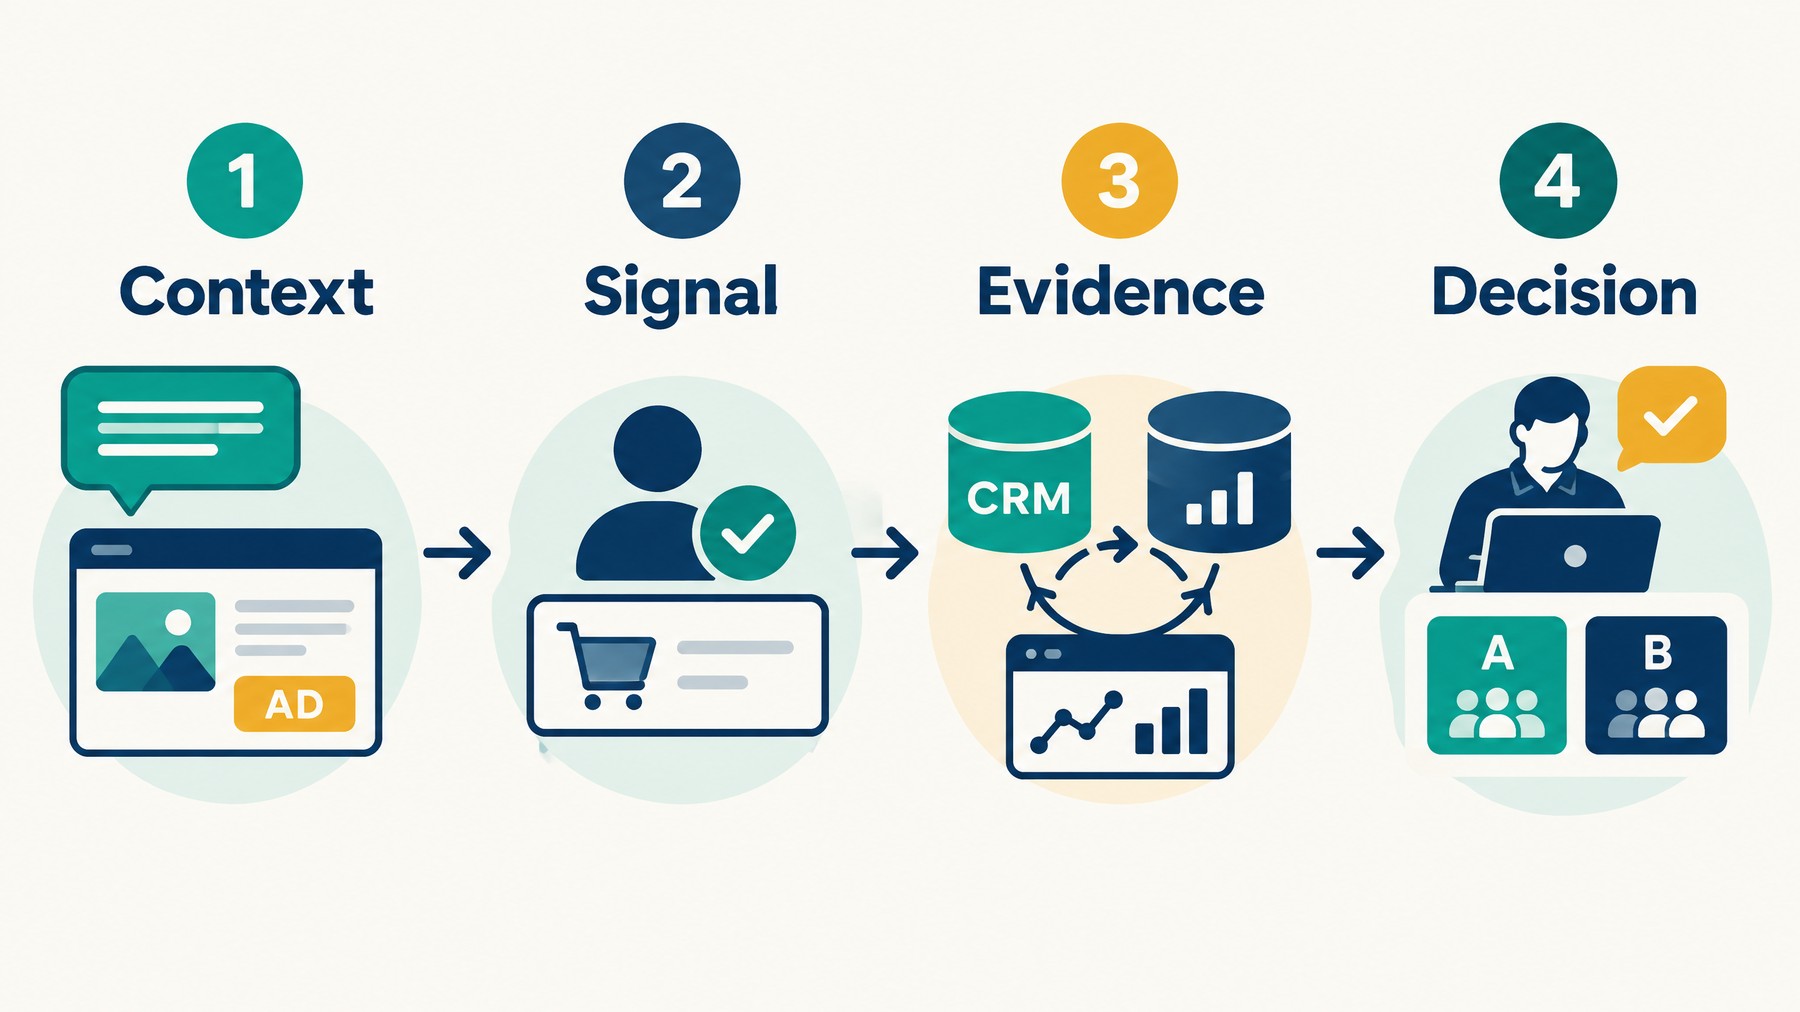
This is the context for Reasoned Intent, Integrated.Social’s proposed operating concept—not an OpenAI term. It means treating conversational ad exposure as one input into a documented decision process, then judging it against observed outcomes, a credible comparison and commercial context. It does not mean inferring motivation from private conversations, claiming to know why an individual acted, or allowing an automated system to make the final commercial assertion.
What is verified / what is still unproven
The announced features and partners are useful facts; they are not yet a universal evidence base. Separate platform announcements, partner-reported findings and a marketer’s own experiment before making budget decisions.
| Area | What is verified from the announcements | What it does not yet prove |
|---|---|---|
| Format | A labelled visual format will be tested later in October 2026 in US image generation with an initial advertiser group; ads are separate from generated images and do not influence answers. | Availability, suitability or outcomes for every advertiser, market or category. |
| Data and attribution | OpenAI names conversion-data integrations and web/app attribution partners. | That an advertiser’s own events, matching logic or reports will reconcile without implementation and quality checks. |
| Incrementality | OpenAI says it is exploring geo-based experiments with Haus, Measured and WorkMagic. | A settled causal standard, or incremental performance for any future campaign. |
| Early findings | DV Rockerbox reported WeightWatchers at 15.3% lower attributed CPA than a blended paid-search benchmark; WorkMagic reported 2.3x more incremental orders than last-click for Dose; Triple Whale said 93% of Portland Leather ad visitors were new. | General benchmarks, independently universal outcomes or promises of lower CPA, new-customer growth or lift. |
These are early partner-reported results. They should be read as examples of measurement approaches and results reported by named partners, not as independently generalisable benchmarks. In particular, attribution and incrementality answer different questions: the former assigns credit under a model; the latter tests whether activity caused additional outcomes. Both can inform a decision, but neither removes the need for judgement.
Build a Reasoned-Intent measurement plan before claiming performance
Start with a short measurement charter that is agreed by the commercial owner, media lead, analytics lead and privacy or legal owner. Give the plan a decision it must support—continue, pause, expand, revise creative or change the eligible event—rather than treating reporting as an end in itself. Connect the plan to existing work on organic, paid and agentic AI CPA and LTV [blocked] and the harder question of the agent-advertising attribution wall [blocked].
Decision checklist
- Define eligible conversion events. Name the primary outcome, any secondary diagnostic events and explicit exclusions. Record when an event is counted, deduplicated, cancelled or refunded.
- Map reconcilable data flows. Document the fields, owner, destination and refresh cadence for pixel or CAPI signals, CRM data, partner reports and finance records. Reconcile a test sample before optimisation relies on it.
- Set consent boundaries. Identify the lawful basis, permissions, retention rules and minimum data needed for each flow. Do not use conversation content or personal data beyond the approved implementation.
- Choose decision windows. Set click-through and view-through windows that match the real buying cycle, and pre-state which window will inform reporting versus optimisation.
- Pre-register a holdout. Where volume and operational conditions allow, define a geo or other appropriate holdout before results are visible. Specify success criteria, power review, duration and what would invalidate the test.
- Assign human commercial accountability. Name the person who can approve claims, budget changes and exceptions. Agents may draft analysis, but a person signs the commercial decision.
A clean event taxonomy is not bureaucracy. It prevents a team from swapping the definition of success after a positive report appears. Likewise, reconciliation should compare like with like: gross and net outcomes, matched time zones, refund treatment, currency handling and deduplication logic should be understood before figures are placed beside another channel’s CPA or revenue view.
Run a contained pilot, then widen only on evidence
Treat the initial activity as a learning programme with a bounded budget and an agreed review point. Keep creative, audience assumptions, conversion definition and comparison methodology recorded in a brief that reviewers can inspect. Use partner reporting as an input, but retain the underlying business evidence and the calculation notes needed to challenge it.
For a broader channel context, see our analysis of ChatGPT Ads, EMEA availability and Ads Manager measurement [blocked] and the OpenAI sponsored agents, ChatGPT Ads, HubSpot and Shopify update [blocked]. The appropriate next action may be to stop, refine the signal or conduct another controlled test; a positive early chart is not itself a scale instruction.
Marketing leaders should also make brand suitability and privacy part of the go/no-go decision. The advertised format boundary—that ads are labelled, separate from the generated image and do not influence answers—does not eliminate the need to assess a brand’s own category, creative, approvals and data governance. Assign a human escalation route for unexpected reporting, suitability concerns and material discrepancies.
Make the channel decision part of a wider growth system
ChatGPT Ads measurement should complement, not replace, accountable search, content, lifecycle and conversion work. A team with weak underlying tracking or unclear value exchange will not fix either problem merely by adding an attribution partner. Improve the foundations through SEO, AEO and GEO [blocked] and a documented AI marketing strategy [blocked], then decide whether the available ChatGPT Ads signals can answer a real business question.
If you are exploring the format, Integrated.Social can help create a proportionate measurement brief and review the decision rules before launch through PPC & Performance Max [blocked]. If you want an independent view of the wider AI growth system first, request a free AI growth audit [blocked]. Neither route requires a claim that the channel will perform; the aim is a test design leaders can defend.
Frequently asked questions
Is the new visual ChatGPT ad format available to every advertiser?
No universal availability has been announced. OpenAI said the visual format would be tested later in October 2026 in US image generation with an initial advertiser group. That confirms a planned, limited test, not broad access across countries, placements or advertiser types. Teams should verify their own eligibility and implementation conditions directly with OpenAI or their authorised operating route before committing resources or forecasting results.
Do ChatGPT ads change the answers people receive?
OpenAI states that its ads are clearly labelled, remain separate from the image being generated and do not influence the answers ChatGPT provides. That is an important product boundary, but it does not replace a marketer’s responsibility to assess creative suitability, data handling, reporting definitions and commercial claims. The correct operational response is to document those controls and retain human review, rather than to assume the placement is risk-free.
Is click-through attribution sufficient for a ChatGPT Ads pilot?
Not on its own if the business question is broader than clicked conversions. OpenAI’s measurement update describes click-through and one-day view-through reporting options, while it also says it is exploring geo-based incrementality work with partners. A pilot should decide in advance which attribution view is useful, what comparison will test additional outcomes and when neither signal is strong enough to support a scale decision.
How should a team choose its conversion decision window?
Choose a window that reflects the documented buying cycle and apply it consistently across the test. Define separately the click-through and view-through windows used in reporting, the event eligibility rule used for optimisation and the review window used for a commercial decision. A short window may miss slower decisions; a long one can create more competing influences. Pre-specification makes later interpretation more credible.
Are the early ChatGPT Ads performance figures benchmarks?
No. OpenAI presents the WeightWatchers, Dose and Portland Leather figures as early findings reported by named measurement partners. The 15.3% attributed-CPA comparison, 2.3x incremental-order result and 93% new-visitor figure describe particular analyses, not expected outcomes for other brands. Use them to understand possible measurement methods, then test an agreed hypothesis with your own data, controls and accountable human review.
About Modi Elnadi
Modi Elnadi [blocked] helps marketing leaders turn emerging AI-channel announcements into decisions that can withstand commercial scrutiny. At Integrated.Social, his approach connects measurement design with growth strategy, clear governance and practical human review—so teams can explore new platforms without turning an early signal into an unsupported promise. For ChatGPT Ads, that means documenting assumptions, protecting consent boundaries and keeping the final claim with a named person.