Universal GEO is already too blunt a planning model for B2B marketers. In one vendor dataset of 5,331 AI answers, YouTube appeared in 45.0% of Google AI Overview answers, 27.4% of AI Mode answers and none of 1,164 ChatGPT answers. That is not a web-wide rule. It is a reason to map each priority buyer question to the evidence each relevant engine actually shows.
The short answer: stop treating “AI” as one audience
A universal GEO strategy is not necessarily dead as a set of foundational publishing practices. It is, however, too broad to be the decision-maker for a B2B content program.
The more useful unit of planning is a priority buyer question, on a specific engine, with a current pattern of cited sources and a clearly identified evidence gap. That distinction matters because an apparent authority signal in one engine may not appear in another, and because even two Google AI surfaces can behave differently.
The evidence for that comes with an important qualifier. Howseen AI, a vendor, analyzed 5,331 answers, 41,711 source links and 5,724 domains across 378 buyer questions tracked by 16 accounts between August 16 and October 4, 2026. The answers came from Google AI Overviews, Google AI Mode, ChatGPT, Perplexity and Gemini. This is not a random or universal sample of the web. Its source mix reflects the vendor’s accounts.
Still, the differences in this vendor dataset are directionally useful for planning. YouTube appeared in 390 of 867 Google AI Overview answers, or 45.0%, and in 300 of 1,096 Google AI Mode answers, or 27.4%. It appeared in zero of 1,164 ChatGPT answers. A single “make more video” directive is therefore not an engine-agnostic authority strategy. It is a hypothesis worth testing only where the buyer questions and observed source pattern justify it.
Google’s own documentation reinforces the need to separate surfaces rather than flatten them. Google says that AI Mode and AI Overviews may use different models and techniques, so the responses and links they show can vary. For B2B teams, the implication is straightforward: build one shared authority foundation, then make engine-specific decisions about the questions to prioritize, the evidence to improve and the formats to test. That work belongs alongside established search practice, not outside it. Our SEO, AEO and GEO service [blocked] is designed around that connected view.
Why a generic visibility score can send teams in the wrong direction
A blended AI visibility score may be useful as a directional dashboard metric. It is not enough to choose a content investment on its own.
If one engine’s answers repeatedly surface one source type and another does not, an average can hide the decision that actually matters. A brand could appear more often overall while still missing the engine and buyer question closest to a high-value commercial conversation. Conversely, a drop in a blended score might reflect a change in a lower-priority surface rather than an urgent demand-generation problem.
That is why organic rank is not the same as AI citation [blocked]. The underlying mechanics, answer formats and cited links can differ. Before expanding reporting, also distinguish a diagnostic from a flattering headline metric in AI Visibility Check vs. Vanity Score for UK B2B [blocked].
The goal is not to create five disconnected content strategies. It is to prevent a broad category label, “AI search,” from overriding evidence about where buyers ask questions and what each relevant engine currently surfaces.
| Planning question | Google AI Overviews | Google AI Mode | ChatGPT | Decision implication |
|---|---|---|---|---|
| Answers citing YouTube in the vendor dataset | 45.0% (390/867) | 27.4% (300/1,096) | 0.0% (0/1,164) | Do not assume one format will earn visibility everywhere. |
| Relationship to the other Google surface | May vary | May vary | Separate engine | Measure and interpret each surface separately. |
The Engine-Specific Authority framework
Engine-Specific Authority is our name for a disciplined planning framework, not a claim about any search engine’s ranking factors. It starts with one proposition: a useful authority plan connects a commercially important question to the actual evidence a buyer can inspect in each relevant answer environment.
1. Start with a finite portfolio of buyer questions
List the questions that matter at distinct moments of the B2B journey: problem recognition, evaluation, comparison, implementation and risk review. Write them in the language a prospective buyer would use, rather than as internal product categories.
Then assign each question a business owner, intended audience and decision relevance. A question should earn testing resources because it matters to buyers and the business, not merely because it sounds likely to produce an AI answer. This keeps the program grounded in audience need.
2. Choose the engines that matter for that question
Do not begin with the assumption that every engine deserves equal effort. Identify the engines the team needs to observe for each priority question, then record the answer, the cited links where available and the date of observation.
Keep the record question-level and engine-level. “We are visible in AI” is not a usable finding. “For this evaluation question, this engine currently surfaces these source types and does not surface our evidence” is usable. It gives the team something concrete to investigate and test.
3. Classify the source pattern before selecting a format
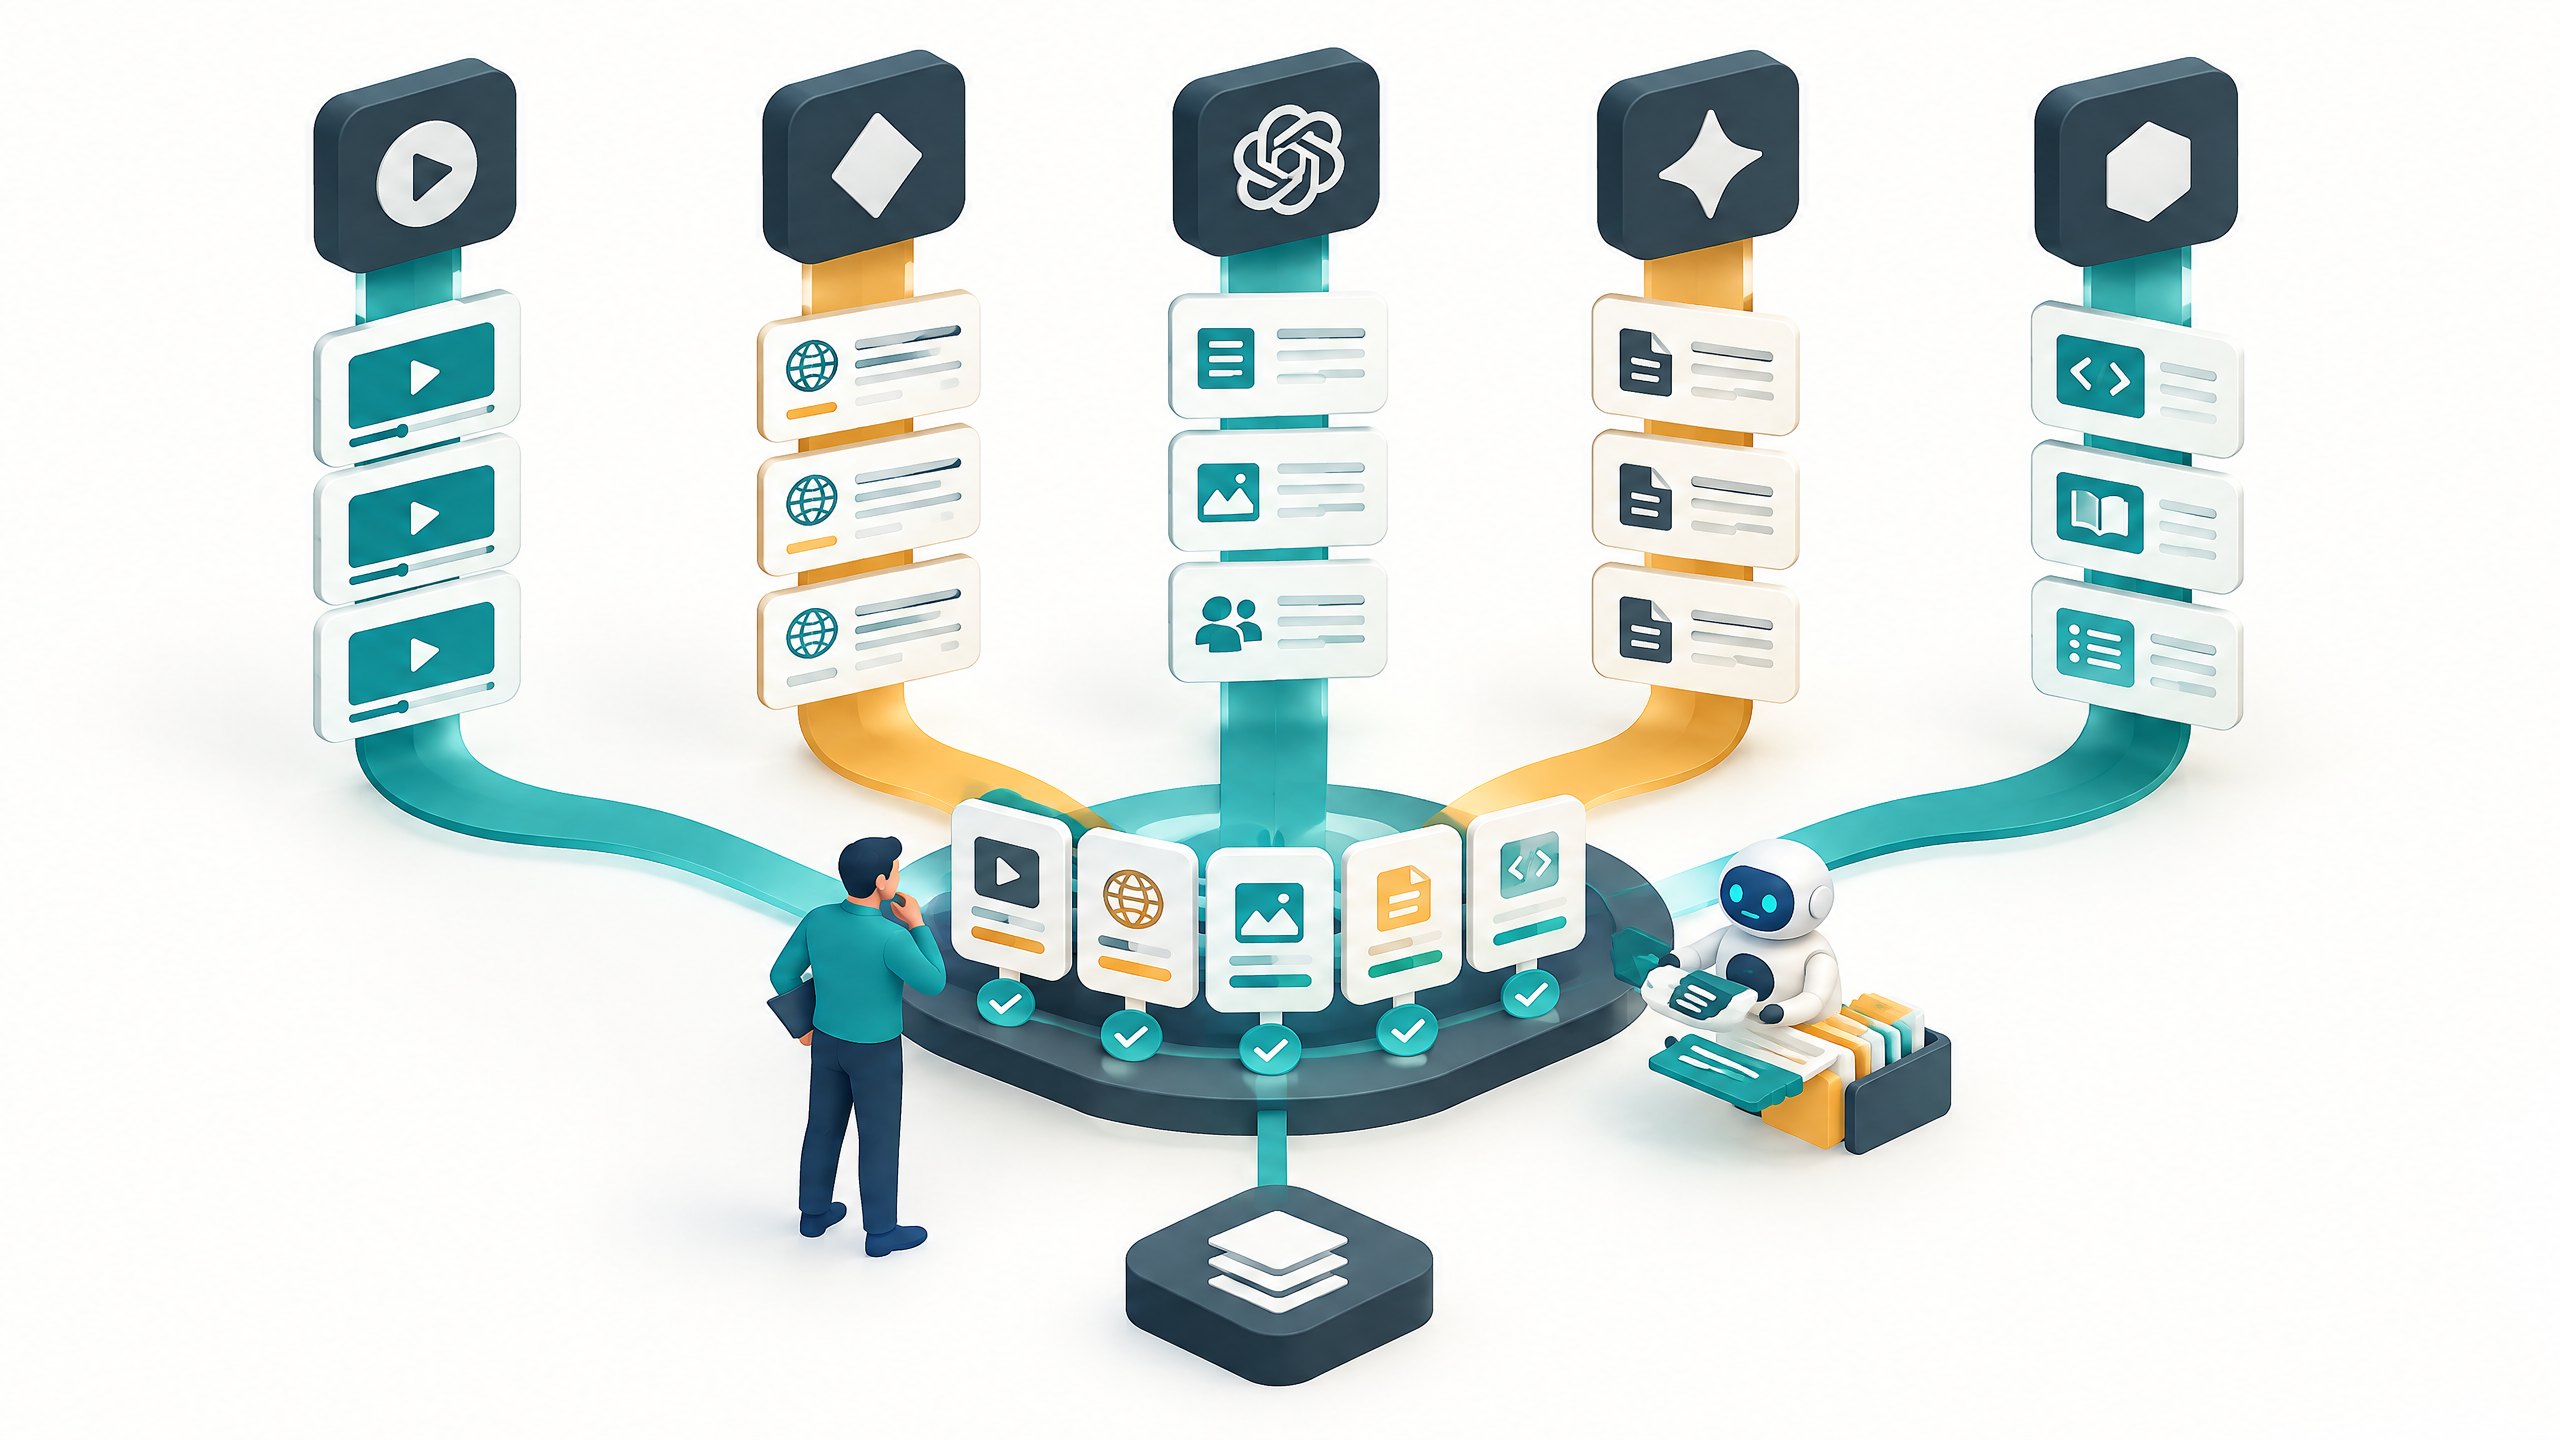
For each answer, classify cited sources in plain terms: first-party product or documentation pages, independent editorial explanations, video, community discussion, trade coverage or another relevant category. The labels are not a ranking-factor model. They make observations comparable.
Then ask two questions: which source types appear repeatedly for this buyer question in this engine, and what do those sources make easier for a buyer to understand? The answer might point to a missing explanation, an unaddressed implementation concern or insufficiently clear proof, not automatically to a need for more of one content format.
The Howseen figures make this step essential. In this vendor dataset, YouTube’s visibility differs sharply across the two Google surfaces and ChatGPT. That observation justifies inspecting your own question set. It does not justify a universal instruction about video.
4. Define the authority or evidence gap
An evidence gap is the difference between what a buyer needs to assess and what your currently accessible, accurate material makes clear. It might be a missing comparison criterion, an unclear scope statement, inadequate explanation of a process or a missing substantiation for a claim.
Write the gap as a testable editorial brief: “For this question and engine, publish or improve a buyer-useful resource that answers this unresolved point, using evidence that a reviewer can verify.” Avoid briefs that begin and end with “optimize for AI.” They lack an audience need and make later evaluation ambiguous.
This is also where one integrated strategy remains valuable. The foundation, clear information architecture, helpful content, technical accessibility and credible evidence, can support multiple discovery paths. The question is not whether AEO replaces SEO. As explored in Is AEO a New Channel or One SEO Job? [blocked], the productive question is how the work connects without pretending every output is identical.
5. Select a measured action, then require human publication approval
Choose the smallest appropriate action: update a high-value page, commission a genuinely useful explanatory asset, clarify documentation or create a new resource where there is a verified gap. Record what changed, the question it serves, the engines being observed and the rationale.
Agents can prepare observations, organize source lists, flag inconsistencies and draft options. A person must sign the claim, the interpretation and the public publication decision. That safeguard matters because an agent should not convert a limited dataset, a changing result or a competitor citation into an unreviewed public assertion.
Put the framework into a practical operating rhythm
Start with a small, repeatable test set rather than a sprawling monitoring program. A cross-functional owner can maintain a question register with five fields: buyer question, priority engine, observed source types, evidence gap and next human-approved action. Add a dated outcome note after the relevant pages or assets are updated.
Review findings at the level of decision, not just percentage change. Did the source mix differ by engine? Did the team strengthen a buyer-needed explanation? Is the next action to improve evidence, change the page, observe again or stop investing? Those questions make the work accountable without claiming that a citation pattern proves causation.
If the team needs a structured starting point, a free AI growth audit [blocked] can help turn a broad concern about AI discovery into a prioritized review. The output should inform judgment, not replace it.
Limitations: what this evidence cannot prove
The Howseen study is a vendor dataset, not a random sample of all buyer questions, all industries or the whole web. It pools data from 16 accounts, and its source mix reflects those accounts. The sample period, August 16 through October 4, 2026, is also limited. Neither the figures nor a pattern observed in your own monitoring should be presented as a permanent rule.
The study’s YouTube figures are counts of answers that cited YouTube, not a measure of business outcomes, traffic quality, lead quality or revenue. They do not prove that publishing a video will cause an engine to cite a brand. They also do not prove that one engine’s behavior will stay stable, transfer to a different query set or apply to every Google product.
Finally, cited links are only one observation layer. A buyer may see an answer, follow a link, compare alternatives or take no action. Authority work therefore needs normal editorial standards: accurate claims, useful scope, current evidence, appropriate review and measurement tied to business context.
Modi's POV
The phrase “universal GEO strategy” is tempting because it offers a simple answer to a complicated operational problem. But simple language should not produce simplistic allocation decisions.
My view is that B2B teams should pursue universal standards, not universal tactics. Keep the basics strong: buyer-centered content, sound SEO, accessible pages, clear evidence and thoughtful internal linking. Then let specific buyer questions and observed engine behavior determine where to spend incremental effort.
That approach is more disciplined than chasing a generic score, and more honest than promising a formula for inclusion. In practice, the winning question is not “How do we optimize for every AI engine?” It is: “What can we substantiate and improve for the buyers we serve, on the engines that matter to their decision?”
Sources
- Howseen AI: Google’s AI Cites YouTube in 45% of Answers. ChatGPT Never Does. — Vendor dataset, methodology and engine-specific figures cited in this article.
- Google Search Central: AI features and your website — Google’s statement that AI Mode and AI Overviews may use different models and techniques, causing responses and links to vary.
About the Author
Modi Elnadi is the founder of Integrated.Social. He helps B2B teams connect SEO, AEO, GEO and evidence-led content decisions to buyer needs. His work favors human accountability over generic visibility promises: agents can prepare and organize, while a named person signs the claim, interpretation and public release decision.