The short answer
AI should not change a campaign simply because its analysis sounds confident or because one unusually large order makes a dashboard look strong. Treat a surprising result as a signal to investigate: define the comparison, test the data and tracking, decide what the system may recommend versus change, and record the human decision. That creates a more useful control than either blind automation or blanket distrust of AI.
Modi’s POV: In marketing, the most expensive AI mistake is not a bad sentence. It is a fast, plausible recommendation applied to weak evidence. Agents can spot anomalies and organize the questions. A named person still needs to decide whether the signal is real, the action is proportionate and the downside is reversible.
Why one big order can create a false campaign story
A performance report compresses uncertainty into a few numbers. A high-value order can be genuine good news, but it can also make a short reporting period look healthier than the underlying demand. The same is true of a tracking change, an unusual product mix, a seasonal spike or a single returning customer. None of those possibilities proves that the campaign is failing. They do mean the conclusion needs a defined comparison before anyone changes budget, targeting or creative.
That is where AI can be useful without being given the final say. It can flag an outlier, compare segments, list account changes and prepare the review. It cannot know the commercial context that did not make it into the data: a sales-team delay, a product-stock constraint, a finance decision or a one-off event that a human already understands.
The practical question is not “Should we trust the model?” It is “What evidence would justify this specific action?” A small reversible adjustment needs a different threshold from a material budget shift or a public claim.
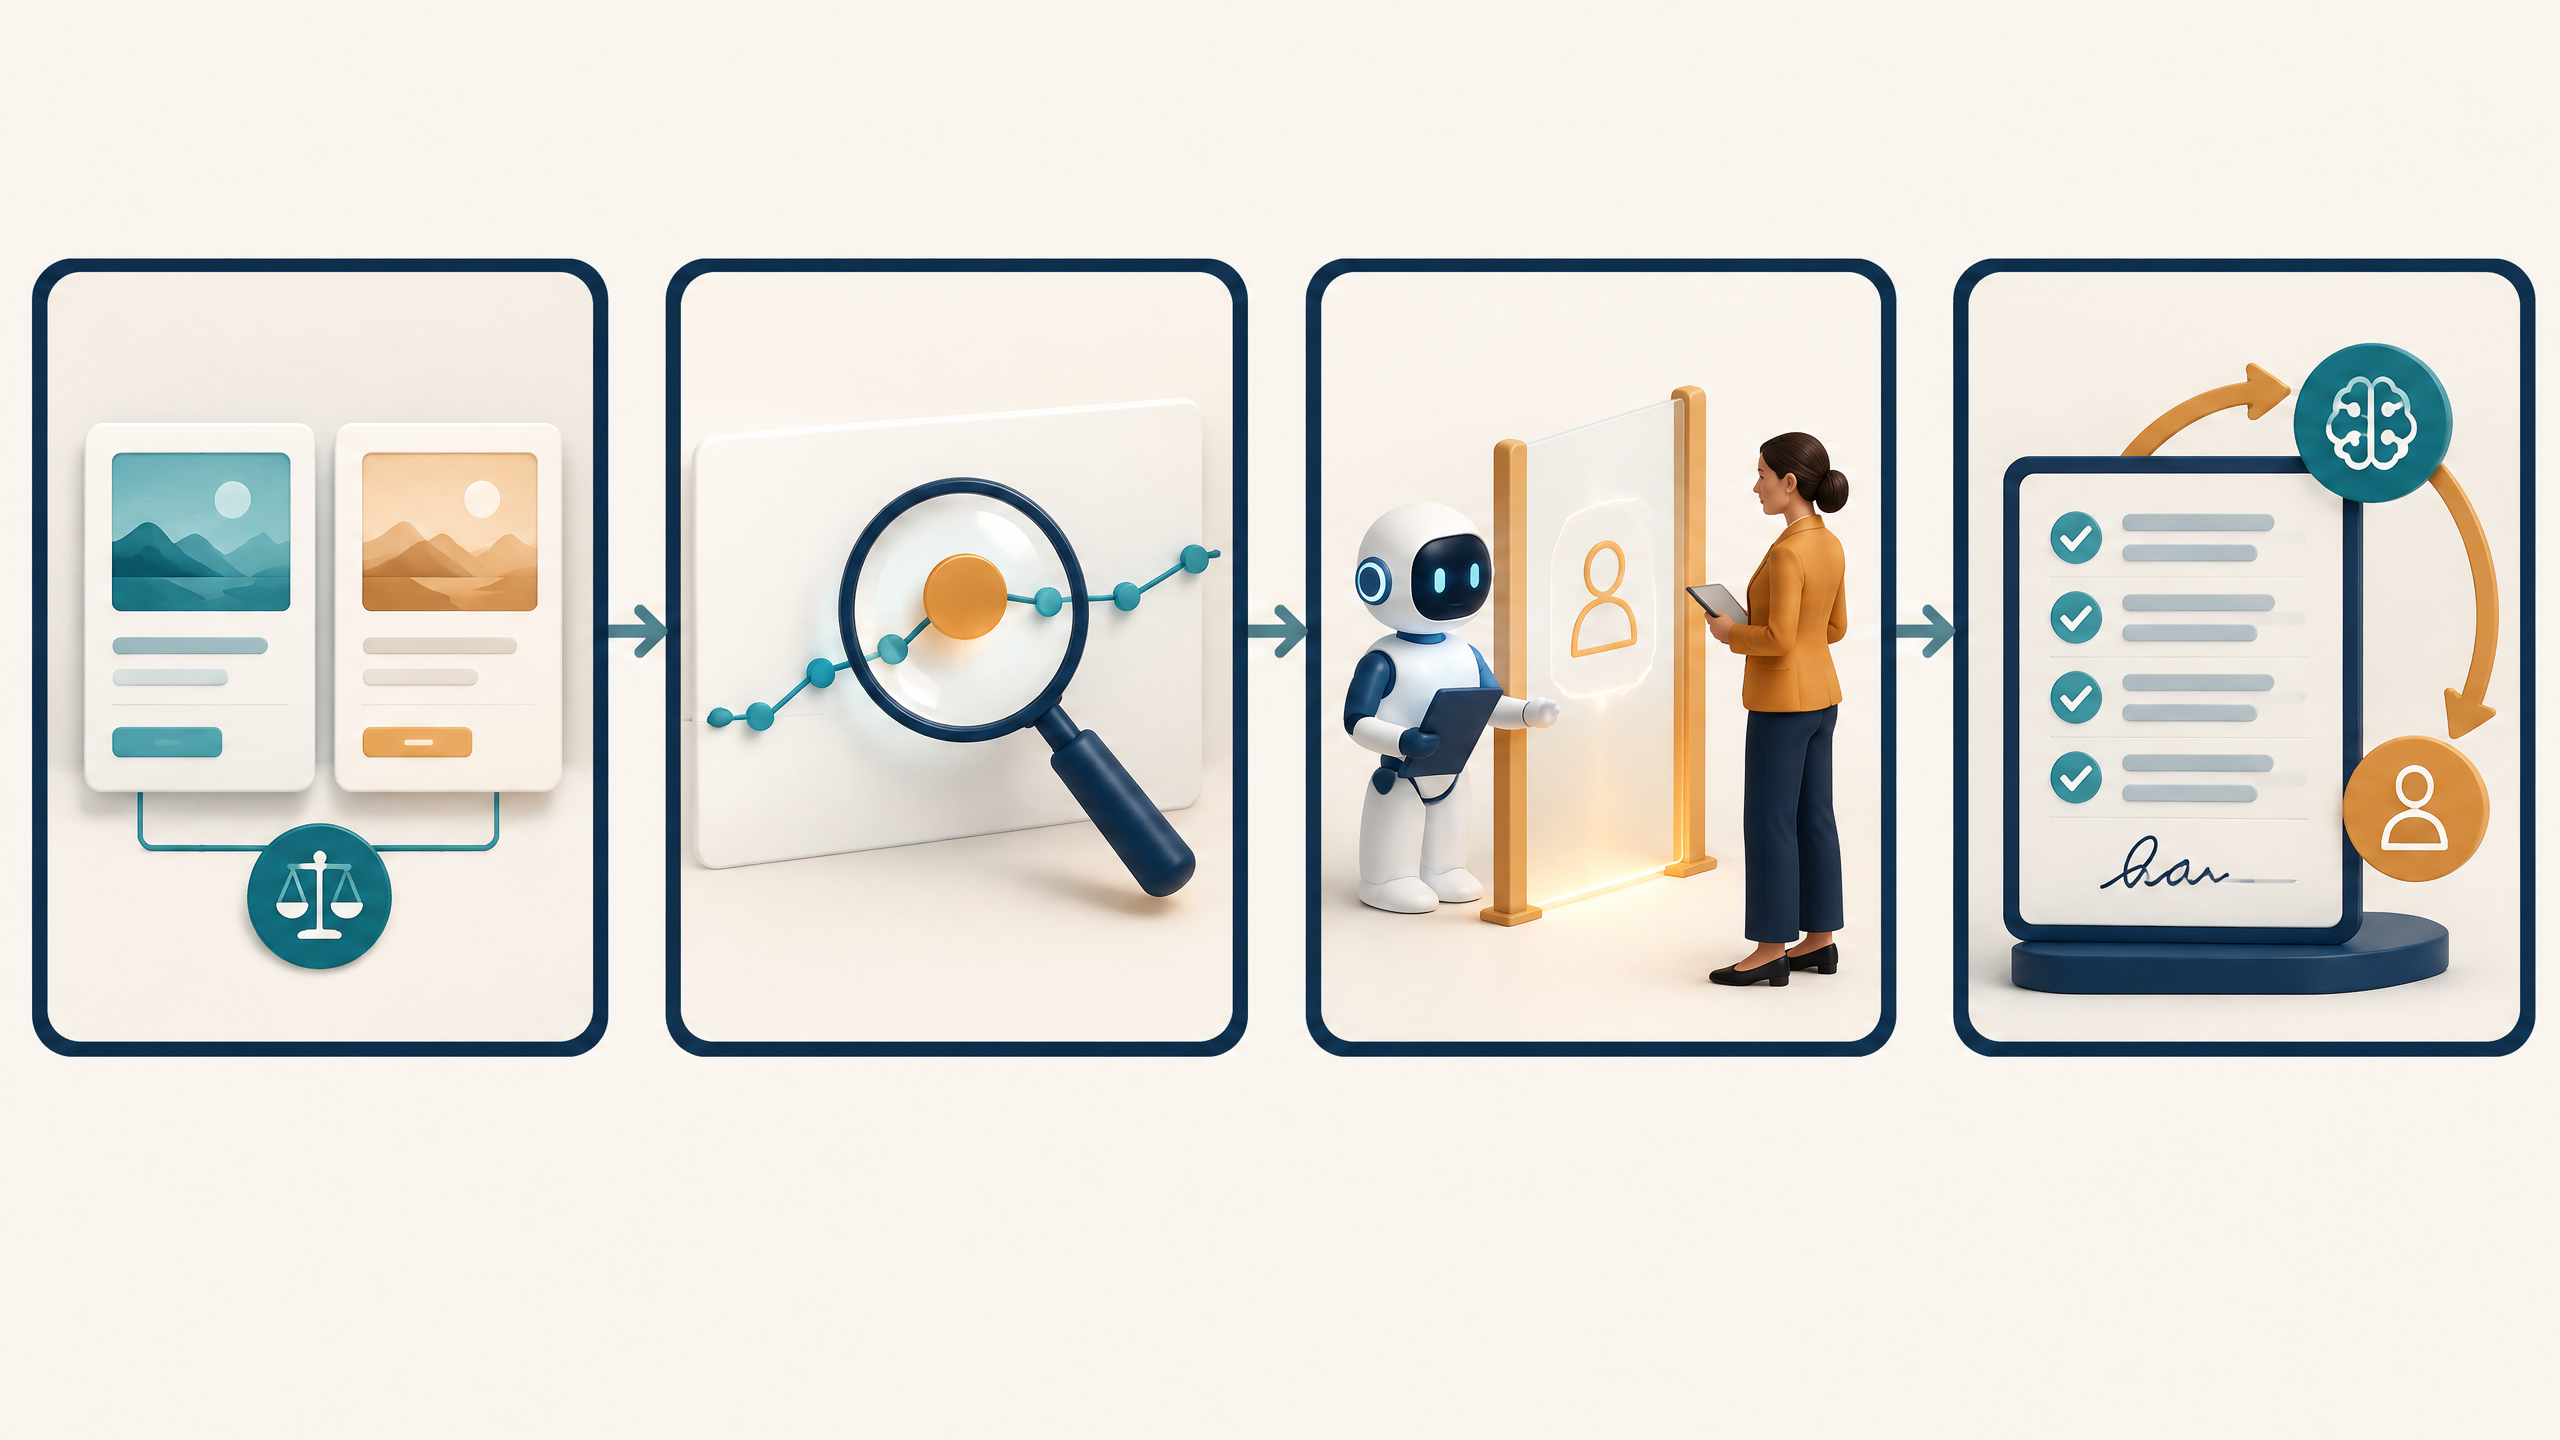
A four-gate review before AI changes a campaign
1. Define the comparison before reading the conclusion
Start with the decision to be made and the comparison that would support it. Is the team deciding whether to change budget, keep a test running, revise an audience or investigate a measurement issue? Then specify the period, the baseline, the metric, the owner and the factors that could make a simple before-and-after comparison misleading.
This is not bureaucracy for its own sake. It stops a system from answering a question that no one has actually defined. “Performance is up” is not a decision-ready statement. “Conversion value changed against this defined period, after we checked these known changes” is much closer.
2. Test the signal, not just the headline
Ask what else could explain the apparent improvement or decline. Review attribution settings, conversion definitions, order mix, refunds, stock, landing-page changes, search terms, audience composition and the time window. If the data is thin, label it thin. A human reviewer may decide to wait, collect more information or run a bounded test rather than act on the first summary.
The NIST AI Risk Management Framework is not a marketing-analytics manual, but its logic is useful here. NIST treats governance as cross-cutting and separates mapping context, measuring risk and managing action. It also says human judgment should be used when deciding the metrics and threshold values relevant to trustworthy AI. That is a better posture than pretending a generic score can settle a commercial decision.
3. Set an explicit approval boundary
Write down what the system may read, recommend, draft and change. For example, an assistant may review daily account changes and prepare a suggested test. It should not automatically expand a material budget, publish a customer claim or change conversion tracking unless the responsible owner has approved the specific action.
That distinction is operational, not anti-automation. Google Ads documents that its auto-apply recommendations are opt-in, visible in account settings and history, and can be disabled. The product control is one example of a broader principle: know who enabled a change, what changed and how to stop it. Your own approval rule should match the decision’s reversibility, cost and customer impact.
For teams building that rule into their wider operating model, our AI governance service focuses on accountable controls, while the PPC and Performance Max service connects account changes to agreed measurement and review.
4. Record the decision and the learning loop
A good review does not end with “approved” or “rejected.” It records the evidence considered, the reviewer, the change made, the expected observation and when the team will look again. That makes it easier to see whether the analysis was useful, whether a threshold needs adjustment and whether the workflow is steadily improving.
NIST’s four AI RMF functions—GOVERN, MAP, MEASURE and MANAGE—are a useful reminder that measurement is not the same as management. A dashboard can describe a pattern. A commercial team must decide what action is justified and remain accountable for the result.
The animated figure: four functions, four gates
The source-qualified part of the figure below is NIST’s four-function framework. The accompanying “four evidence gates” are this article’s proposed operating model for marketing decisions. Neither number predicts a result or replaces a team’s judgment. The third card is a practical operating rule: one named person should own any material change before it goes live.
What AI should do—and what it should not decide alone
| Good use of AI assistance | Decision that still needs an accountable owner |
|---|---|
| Flag a sudden change in conversion mix | Whether the change is reliable enough to alter budget |
| Compare campaign changes with a previous period | Whether the periods are comparable and what confounders matter |
| Draft a testing hypothesis | Whether the test is safe, funded and commercially worthwhile |
| Summarize account-history entries | Whether the recommendation matches the business objective |
| Prepare a stakeholder update | Whether a public or internal claim is supported and appropriately scoped |
The boundary will differ by business. A low-risk report draft can have a lighter approval path than a change to spend, price, compliance language or customer targeting. The important thing is that the boundary is deliberate, visible and reversible where possible.
The EU AI Act’s human-oversight provisions apply to high-risk AI systems, not automatically to ordinary marketing workflows. Even so, its emphasis on context, appropriate oversight, the risk of over-reliance and the ability to override a system offers a useful caution: do not label an automated recommendation as an accountable decision simply because it arrived quickly.
A practical weekly review agenda
A short weekly review can keep the system useful without creating a new reporting ritual. Start with changes that matter to the commercial objective rather than every movement in the account.
- What changed? Name the campaign, period and business metric without adding a conclusion.
- What might explain it? Separate observed evidence from hypotheses, including tracking, mix and external changes.
- What is the smallest sensible next action? Prefer a reversible test or further investigation where uncertainty remains.
- Who owns the approval? State the person, date and scope of the decision.
- What will tell us whether it helped? Record the follow-up measure and review point.
This approach also improves how an AI assistant is briefed. Instead of asking it to “optimize performance,” ask it to identify anomalies, list possible explanations, show the source fields used and prepare a bounded recommendation for human review. That is less dramatic than full autonomy, but more likely to produce decisions that stand up when a stakeholder asks why.
For a wider framework, read our guide to AI governance quality control, our article on reliable task closure for AI marketing agents, and our explanation of the AI ROI measurement paradox.
What this does not prove
This framework does not establish a universal minimum sample size, prove that an AI recommendation is wrong, or promise a better return on ad spend. It is a way to make the assumptions, evidence and authority around a decision easier to inspect. If the question is whether your site and marketing foundations are clear enough for people and AI systems to understand, begin with the Free AI Visibility Score. It is a baseline, not a citation count or a promise of rankings, leads or revenue.
Sources
- NIST AI Risk Management Framework 1.0
- Google Ads Help: Manage auto-apply recommendations
- Google Search Central: AI features and your website
- EU AI Act Service Desk: Article 14 — Human oversight
About the Author
Modi Elnadi is the founder of Integrated.Social. He works with B2B teams on evidence-led AI marketing, paid-media measurement and governed AI-assisted workflows. His approach is practical: define the buyer or business decision, separate the evidence from the interpretation, set the approval boundary and make the next action measurable. AI can make research and reporting faster; it does not remove commercial accountability for the change a team decides to make.